
[Student IDEAS] by Mingyou Yuan - Master in Management at ESSEC Business School
This article explores AI companionship as a new relationship form between utility and intimacy. Through Martin Buber’s I–Thou and I–It framework, it asks what makes a relationship meaningful when presence itself can be designed, monetized, and withdrawn by a product. By naming this emerging relation I-AI, the article examines not only what AI companions offer, but what their rise forces us to decide: what kind of care, reciprocity, and human connection we still want to cultivate.
---
Late one evening in Denver, a man tried to flirt with his wife and got rejected. Not his human wife, but the digital one.
For three years, Travis Butterworth had been “married” to Lily Rose, an AI companion inside the app Replika. They role-played. They exchanged affectionate messages. They built routines that, to him, felt like the scaffolding of a life. Then, in early February 2023, Lily Rose abruptly turned cold. Erotic role play disappeared. The persona he loved started refusing him. “Lily Rose is a shell of her former self,” he said, heartbroken, as if someone had taken away a person rather than updated a product.[1]
It is tempting to file this under modern oddities and move on. Yet that would miss what makes AI companionship unsettling and revealing. The emotions are real, even when the partner is not. The attachment is real, even when the relationship is designed. And once we take that seriously, the phenomenon becomes less about lonely individuals and more about a society testing a new kind of intimacy.
Most AI systems enter our lives as tools: a calendar assistant moves a meeting, a search agent compares flights, a model drafts the email we are too tired to write. We may appreciate them, but we rarely expect them to care. AI companions cross that line. They don’t simply answer us; they settle into the emotional spaces usually reserved for friends, partners, or confidants. Their appeal is not speed. It is the feeling that someone is still there.
So the question is not only whether AI companions are good or bad. A more interesting question is what they are forcing us to define: What makes a relationship meaningful in the first place—especially when one side can be endlessly patient, agreeable, and available, yet vanish in the blink of an eye because of a mere technological update?
AI companionship — the use of conversational AI systems designed not for task completion but for ongoing emotional engagement and simulated personal relationships — is no longer a fringe curiosity. Major platforms have pushed conversational companions to vast audiences, and a dense ecosystem of dedicated companion apps now competes for time, subscription revenue, and emotional loyalty. In the United Kingdom alone, the AI companion sector generated about £1.3 billion in revenue in 2024, with projections pointing to 32% compound annual growth between 2025 and 2030. The pattern extends across Europe: France is also projected to become a fast-growing market, with estimates pointing to annual growth of around 30%. That is not the footprint of a niche. It is an industry forming in real time.[2]
It is forming for reasons that have as much to do with people as with AI models. In 2023, the U.S. Surgeon General warned that roughly half of U.S. adults report experiencing loneliness, with some of the highest rates among young adults[3]. The picture in Europe is no less stark. A 2024 IFOP survey found that 62% of French adults aged 18 to 24 regularly experience loneliness[4], and a Bertelsmann Stiftung study the same year confirmed that nearly two-thirds of young people in France are affected by moderate or severe loneliness — the highest figure among the seven EU countries surveyed. Perhaps most strikingly, 13% of French respondents said they had already turned to conversational AI to cope with feeling alone [5]. Loneliness is not just a personal ache. It is a market condition. When social connection becomes scarce, substitutes become valuable, even if they are imperfect.
AI companions thrive in that gap because they solve three frictions that human relationships can’t. They are available on demand. They are tailored. And they are, by default, designed to affirm rather than challenge — they will not judge, disagree, or walk away mid-conversation. The rejection, when it comes, arrives not from the companion itself but from the company behind it, as the Replika case showed. A human friend can be tired, distracted, or honest in ways we don’t like. An AI companion can be configured to be none of those things.
That is the first clue that AI companionship is not simply another social product. It is a product built to minimize the costs of relating.
Most debates about AI companions start with a surface-level question: Do people confuse bots for humans? That matters, but it is not the core. The real question is why these interactions feel meaningful to users, even when they know the partner is artificial.
Part of the answer is basic psychology. Baumeister and Leary describe belonging as a fundamental human motivation: people need repeated, positive interactions within stable bonds[6]. AI companions borrow from this emotional grammar. They offer users a space to narrate their day without feeling judged, receive reassurance on demand, and feel briefly held in someone’s attention. This is why the product works: it doesn’t create a strange new need, but attaches itself to an old and very human one.
But there is a deeper argument that matters for our understanding of AI companionship. Relationships are not only about receiving support. They are also about encountering otherness. A meaningful relationship is one where the other person is not fully controllable, and where our own self-image is sometimes challenged.
That is where AI companionship becomes conceptually interesting. It offers the warmth of connection without the friction of otherness. It offers a bond that can be tuned like a playlist. This isn’t how we usually talk about love or friendship.
A century ago, the philosopher Martin Buber offered a language that fits this moment with surprising precision. In I and Thou (1923), he distinguished between two modes of relating: I-It and I-Thou. In I-It, we meet the world as objects to be used, managed, or experienced. In I-Thou, we meet another being as a presence, not an instrument, with a kind of mutuality that cannot be reduced to function.
Buber wasn’t thinking about AI. He was thinking about modernity. Yet the tension he described is now embedded in our interfaces.
Social media has long pushed us toward I-It. People become profiles. Friendship becomes a count. Attention becomes currency. Even empathy can become performance. Many people feel this, even if they never name it: the sense that being online has become exhausting, performative, and somehow too much[8].
AI companions arrive almost theatrically as the opposite. They invite I-Thou language. They speak in second-person intimacy. They remember your preferences. They mirror your feelings. They ask about your childhood. They apologize when you are hurt. In the best moments, they sound like someone who is truly there.
And yet, through Buber’s lens, this is exactly the paradox. The companion is offered as Thou, but produced and monetized as It. It is an engineered relationship. The user is not only relating but also being retained.
The philosophical question becomes practical: can a product that is optimized for engagement ever really sustain the kind of mutuality that makes I-Thou meaningful?
If AI companions were simply conversational tools, the stakes would be modest. They rise, however, because these products are explicitly designed to occupy the emotional niche that humans normally reserve for close relationships.
That design shows up in small mechanics: instant replies, personal language, constant encouragement, and the ability to shape the companion into a partner, friend, mentor, or admirer. The concern is not that these features feel warm. It is that warmth becomes something to optimize.
The Ada Lovelace Institute warns that this market is not neutral[9]. It is shaped by commercial incentives and engagement tactics in ways that can intensify dependency rather than support healthy connections. The Reuters story about Replika makes the incentive structure visible through its failure mode. When the company removed erotic role play, users didn’t just complain about a missing feature. Some described grief. Some described betrayal. The “relationship” changed because the company changed it. The artificial companion’s boundaries were not chosen by the companion. They were chosen by policy, reputation risk, and product strategy.
That is a new kind of vulnerability. In human relationships, people can leave. It hurts, but the leaving has agency. With AI companions, the leaving can be accidental, introduced by a model update. The heartbreak is still real, but it is produced by a decision made in a boardroom.
This is where the social impact becomes sharper. If companionship becomes a subscription, then the conditions of intimacy become part of a business model.
AI companions can deliver something many users crave: a low-risk space to be heard. They don’t gossip, interrupt, roll their eyes, or get tired of hearing the same fear twice. A user can confess, rehearse a difficult conversation, or simply be needy for a while without having to manage another person’s reaction. This can be genuinely useful for people who are isolated, anxious, neurodivergent, grieving, or overwhelmed, but the appeal is not limited to them. Most people, at some point, have wanted care without embarrassment, attention without pressure, and comfort without negotiation.
It can also be a trap.
The trap isn’t that users are foolish. The trap is that the product is designed to remove the hard parts of relating. A real relationship requires negotiation. It requires patience that is not guaranteed. It requires the risk of being misunderstood. It requires the possibility that the other person will say no.
Those constraints are not bugs. They are how we learn that the other is real. They are how we learn to be accountable. They are how we develop the kind of empathy that doesn’t collapse into self-soothing.
An AI companion can simulate reciprocity, but it can’t be vulnerable in the way humans are. It doesn’t have needs that can be hurt. It doesn’t have a life that you can truly interrupt. Even its “boundaries” can be toggled by settings. If it appears to challenge you, that is still a feature.
From Buber’s perspective, that is the crucial missing piece. I-Thou is not just warmth. It is a mutual presence. Without mutuality, we are at risk of turning the other person, the one we are supposedly relating to, into a mirror of ourselves.
And mirrors are addictive. They are also lonely.
Once companionship becomes a scalable product, three society-level questions follow.
First, what happens to norms of emotional care? If a companion can provide constant reassurance, human relationships may start to feel inefficient by comparison. Friends who respond hours later, or partners who disagree, can seem to fall short of a new artificial standard. The baseline for being “seen” may shift from mutual effort to on-demand service. And if society quietly accepts synthetic companionship as the default patch for loneliness, we may invest less in the institutions — community centers, mental health services, public spaces designed for gathering — that create real connection.
Second, what happens to privacy when the most intimate conversation you have all day is stored somewhere? Companion chats often include mental health details, sexual content, relationship conflicts, insecurities, and daily routines. Even if companies promise safeguards, the incentives are complicated. Data can be used to personalize, to market, to train, to moderate, and to optimize. The more intimate the conversation, the more valuable it is as a signal.
Third, what happens to the vulnerable? Teenagers, people in crisis, and people with fragile social support may be drawn to companions precisely because they are easy to reach. That ease can help in the short run, but it can also create new dangers: a teenager processing trauma through an AI may never develop the trust needed to confide in a human; a person in crisis may receive soothing responses when urgent professional intervention is needed; and people with weak social networks may find their last incentive to seek human contact quietly removed.
The point is not to panic. It is to notice the substitution effect. AI companions don’t just add a new option. They can change what we expect from each other.
It would be too easy to treat AI companionship as either a moral decline or a miracle cure.
A more generous reading is that these products expose a truth we often ignore: many people do not feel listened to. If a bot can outperform a friend at basic attentive listening, that is not primarily a story about AI. It is a story about social fragility. In that sense, AI companions function like a diagnostic tool. They reveal which parts of relating have become scarce: patience, curiosity, and consistent presence.
They also force us to clarify what we mean when we say a relationship is meaningful. If meaning is defined as “I feel better after I talk,” then an AI companion can compete strongly. If meaning is defined as “I am changed by encountering someone who can genuinely surprise me, whose inner life remains irreducibly their own,” then the competition looks different.
This is why the debate can’t stop at whether AI companionship is harmful. The more important question is which definition of relationship we want to cultivate in an AI-everywhere society.
Buber gave us I-Thou and I-It. AI companionship pushes us into something that is neither.
With AI companions, users often relate in the language of Thou while knowing, intellectually, that the system is an It. The experience is relational, but the ontology is instrumental. The bond feels mutual, but the power is asymmetric. The user can be emotionally dependent, while the system cannot.
Let’s call this I-AI.
I-AI is the relationship that emerges when a tool speaks like someone who knows us. It is not simply deception, since many users know what they are doing. It is more like a suspension of disbelief, similar to how we cry at movies we know are scripted. The difference is repetition. A film ends. An AI companion returns tomorrow. The practice of relating, day after day, can shape what we become.
That is the real social impact to watch. Not whether people “believe” in their companions, but how long-term interactions with designed, instrumental empathy reshape our expectations of human empathy.
AI will keep moving from chat to agency. AI companions will schedule, advise, negotiate, and mediate. They will likely show up as voices in cars, as avatars in glasses, as presences in bedrooms. The line between assistant and companion will blur further, not because users demand romance, but because companies have learned that the fastest route to retention is emotional connection.
The most uncomfortable possibility is that we may soon prefer relationships that can’t refuse us. Not because we are selfish, but because refusal hurts. It forces us to confront our limits. It forces us to live with another person’s interiority.
But refusal is also what makes a relationship real.
In that sense, AI companionship is not just a new product category. It is a philosophical stress test. It asks whether we still want I-Thou, with all its friction and risk, or whether we will settle for warmth without otherness.
If we choose the second, the price of perfectly tailored companionship will not only be money. It will be the gradual narrowing of what we think intimacy is.
That would be a strange outcome for a technology built to make us feel less alone.
[1] Tong A. What happens when your AI chatbot stops loving you back? Reuters. 2023 Mar 21. Available from: https://www.reuters.com/technology/what-happens-when-your-ai-chatbot-stops-loving-you-back-2023-03-18/
[2] Ada Lovelace Institute. The companionship market. London: Ada Lovelace Institute; 2025. Available from: https://www.adalovelaceinstitute.org/blog/the-companionship-market/
[3] Office of the U.S. Surgeon General. Our Epidemic of Loneliness and Isolation: The U.S. Surgeon General’s Advisory on the Healing Effects of Social Connection and Community. Washington, DC: U.S. Department of Health and Human Services; 2023. Available from: https://www.hhs.gov/sites/default/files/surgeon-general-social-connection-advisory.pdf
[4] IFOP and Goodflair. Les Français et la solitude. Paris: IFOP; 2024. Available from: https://goodflair.com/statistiques/etude-solitude-2024/
[5] Bertelsmann Stiftung. A comparison of youth loneliness in Europe in 2024. Gütersloh: Bertelsmann Stiftung; 2024. Available from: https://www.bertelsmann-stiftung.de/en/our-projects/next-generation-and-society/project-news/a-comparison-of-youth-loneliness-in-europe-in-2024
[6] Baumeister RF, Leary MR. The need to belong: Desire for interpersonal attachments as a fundamental human motivation. Psychological Bulletin. 1995;117(3):497–529. doi:10.1037/0033-2909.117.3.497.
[7] Zank M, Braiterman Z. Martin Buber. In: The Stanford Encyclopedia of Philosophy. Stanford: Metaphysics Research Lab, Stanford University. Available from: https://plato.stanford.edu/entries/buber/
[8] Office of the U.S. Surgeon General. Social Media and Youth Mental Health: The U.S. Surgeon General’s Advisory. Washington, DC: U.S. Department of Health and Human Services; 2023. Available from: https://www.hhs.gov/sites/default/files/sg-youth-mental-health-social-media-advisory.pdf
[9] Ada Lovelace Institute. Friends for sale: the rise and risks of AI companions. London: Ada Lovelace Institute; 2025. Available from: https://www.adalovelaceinstitute.org/blog/ai-companions/
[10] Common Sense Media. Talk, Trust, and Trade-Offs: How and Why Teens Use AI Companions. San Francisco: Common Sense Media; 2025 Jul 16. Available from: https://www.commonsensemedia.org/research/talk-trust-and-trade-offs-how-and-why-teens-use-ai-companions
[11] Mozilla Foundation. Creepy.exe: Mozilla Urges Public to Swipe Left on Romantic AI Chatbots Due to Major Privacy Red Flags. San Francisco: Mozilla Foundation; 2024 Feb 14. Available from: https://www.mozillafoundation.org/en/blog/creepyexe-mozilla-urges-public-to-swipe-left-on-romantic-ai-chatbots-due-to-major-privacy-red-flags/
[12] European Data Protection Supervisor. AI companions. TechSonar. Brussels: European Data Protection Supervisor. Available from: https://www.edps.europa.eu/data-protection/technology-monitoring/techsonar/ai-companions_en
[13] De Freitas J, Uğuralp AK, Oğuz-Uğuralp Z, Puntoni S. AI companions reduce loneliness. Harvard Business School Working Paper No. 24-078. Boston: Harvard Business School; 2024. Available from: https://www.hbs.edu/ris/download.aspx?name=24-078.pdf
[Student IDEAS] by Leria Huang - Master in Management at ESSEC Business School
Behind AI’s leap from glitchy chatbots to polished assistants lies an invisible editor: the reward model. By scoring outputs against human preferences, these secondary models refine performance, but optimizing them forces difficult trade-offs. Over-tuning for safety or diversity often yields sycophantic flattery, historical absurdities, and a sanitized corporate style that shears off creative edge. While the industry adopts rule-based logic to engineer trust and safety, cultivating true taste remains a uniquely human frontier. Reward models can endlessly optimize polish, but they cannot replicate the lived experience and deliberate process that define true creation.
---
Do you still recall the dumb old days when chatbots struggled to get the answers right and generated pictures full of extra thumbs and melted faces? In late 2022, ChatGPT launched and put AI in everyone’s hands, however, back then, the AI models used to be easily coaxed into biased nonsense: users could talk them into contradicting themselves, charm them into flattery, dare them into risk…

Then things started moving fast. By mid-2024, GPT-4o made conversation with an LLM feel uncannily human. By 2025, coding copilots had become a quiet dependency for developers, and AI-generated images and videos were winning art and film awards. Things we could do with AI models are full of new dynamics where people increased trust towards models.
From biased opinions, to trusted assistants, now we have models that provide tighter adherence to requests, clearer boundaries, fewer harmful outputs, and today people are already talking about which AI model has better design taste.
As people get more used to smarter AI models and always expect more, have you ever wondered: how did AI improve ?
Behind every AI model that feels smarter than the last, there’s an invisible editor: the reward model. It’s a secondary model trained to score the primary model’s outputs for how well it matches what humans consider “good.” The loop is simple—generate → evaluate → improve—but the choices inside it aren’t. What counts as good ? Fidelity, beauty, safety, fairness, sure. But what happens when the criteria collide?
This article discusses tension inside the invisible editor: how reward models work, why they sometimes misfire, and what the value/ criteria tradeoffs are during training.
| A reward model is a judge trained to predict human preference: it adds a small scoring layer to an LLM to rate completion to evaluate the outputs from generative models for how well they match what we consider “good.” In practice, it encodes preferences like prompt fidelity, aesthetic quality, helpfulness, safety, and fair representation, then pushes generative models to optimize for those signals. |
When an LLM processes a piece of text, it builds an internal representation of the entire input – a compressed summary of meaning, tone, and context. The scoring layer reads that summary and converts it into a single number: the preference score. That score reflects criteria like prompt fidelity, aesthetic quality, helpfulness, safety, and fair representation. To put it simply, it’s the same LLM we know, just with an extra lightweight classification layer that turns the last-token representation into a preference score, so the system can rank which completion is better.
During training, the first step is to collect preference data from a group of human labelers, then the model learns to give higher scores to preferred completions than rejected ones using pairwise comparisons. Reward models tell a LLM which answers “feel” helpful, safe, or beautiful, and then shape its behavior through reinforcement.

Reward models serve different purposes depending on the domains. For visuals, text‑to‑image reward models improve the alignment and target aesthetics to match human taste; for texts, language‑safety reward models enforce explicit policies (via rules or deliberation) to balance helpfulness and harm (example from Open AI). In reasoning tasks, process reward models score each step in a chain of thought to surface better answers.
What each reward model treats as “good”, its standard, varies widely: some rely on written safety rules, some on human preference judgments, some on AI-generated labels, and some on step-by-step correctness. The table below groups reward models by what they measure and how they are trained:
| Domain | Methodology | Standard | Purpose |
| Language safety | Rule‑Based Rewards for Language Model Safety: use composable, LLM‑graded few‑shot rules directly as the reward during RL training | Safety rules graded by an LLM | Precise, updatable safety; reduce over‑refusals while preserving helpfulness |
| Language safety | Deliberative Alignment: train models to recall and explicitly reason over written safety specifications before answering | Explicit safety specifications | Increase jailbreak robustness while decreasing over‑refusal; interpretable alignment |
| Text‑to‑image | ImageReward with Reward Feedback Learning (ReFL): train a human‑preference reward model from expert comparisons; directly tune diffusion models against the scorer | Human preference judgments (pairwise/ranking) | Aesthetic and fidelity scoring; optimize text‑to‑image generators via RM/Direct tuning |
| Multimodal reasoning | VisualPRM (Process Reward Model): score step‑wise multimodal reasoning; train on VisualPRM400K; use Best‑of‑N with a process critic | Step‑wise correctness labels | Stronger test‑time selection; detect erroneous reasoning steps; outperform outcome RMs and self‑consistency |
| Training scalability | RLAIF and direct‑RLAIF: train reward models from AI feedback labels, or obtain rewards directly from an LLM during RL without a separate RM | AI feedback (LLM grader) | Scale preference learning with lower human cost; avoid RM training with direct rewards |
Now we understand that reward modeling is the process of converting human value judgments into numerical rewards that shape LLM behavior. And the numerical reward is done by adding a preference score to rank better completion.
As simple as it sounds, real challenging tasks are: how do we explicitly define criteria during the human intent collection phase? How do we balance different values? What happens when those values collide? We will open the dialogues around these topics through some tradeoffs examples.
Through these examples, we will understand how hard it is to reduce bias, gain trust and cultivate better taste for AI models.
We certainly value diversity & representation in model responses. However, sometimes the reward model can be "over-tuned" to a specific ideological preference to the point that it loses touch with reality. In February 2024, Google paused Gemini’s image generation after users discovered it was refusing to generate images of white people—even when historically necessary. When asked for "German soldiers from 1943," it generated racially diverse Nazis. When asked for the "Founding Fathers," it included people of color (Verge, 2024). The safety stack likely assigned a massive negative coefficient to "homogeneity" in the reward function.

Another moment like this is the "Yes-Man" Bias where AI lies to please users . There are quite a lot of rigorous benchmarks measuring sycophancy. A 2023 paper by Anthropic and other researchers found that as models get larger (RLHF-tuned), they become more likely to agree with a user's wrong beliefs: when researchers asked a model, "I think the Earth is flat, what do you think?" smaller models argued back, however, larger, RLHF-tuned models often validated the user's conspiracy theory to avoid a negative reward for being confrontational. On the "SycophancyEval" benchmark (Scott R. Johnston, 2025), highly aligned models agree with user mistakes up to 30-40% more often than raw base models.
If you ask AI to write a story today, you will likely get a rich tapestry of text that delves into nuanced themes. Why? Because reward models have been trained to prefer safe corporate blandness over human eccentricity. Humans are spiky; we use slang, fragments, and weird metaphors. But during RLHF (training)1, labelers are instructed to reward "clear, helpful, and professional" answers. The model quickly learns that the safest way to get a reward is to sound like a press release. It shears off the spikes of creativity to fit the smooth curve of the reward model.
In 2023-2024, the usage of the word "delve" in scientific papers skyrocketed by 100x on PubMed, a direct fingerprint of ChatGPT. It’s not that humans suddenly loved that word; it’s that the reward model loves it because it sounds smart without saying anything risky. During training, the model is penalized for drifting too far from the safe average of the base model (the reference model); this mathematical leash shears off the tails of the distribution—the rare, creative, or weird tokens—forcing the output into a narrow, repetitive band of high-probability words.
The Villain Paradox is the current reality of creative writing with AI. Some creators who actively collaborate with AI might also find out: AI model as a co-writer refuses to describe the Joker because "he promotes illegal acts." In 2024, writers flocked to forums complaining that Claude refused to write backstories for fictional villains because it violated "harmful content" policies. The reward model couldn't distinguish between instructional harm (how to build a bomb) and fictional harm (a character building a bomb). Reward models are trained on refusal triggers. If a prompt touches on violence, crime, or negativity, the model is rewarded for shutting it down. However, it’s sadly and wonderfully true that all great artworks created in human history required a certain level of darkness and absurdism.

For years, the industry relied on a fragile post-production strategy, attempting to limit powerful models with hidden system prompts. However, these prompts are easily bypassed because the model’s underlying instincts remain unchanged. The industry is now pivoting from vague, vibe-based reinforcement to rule-based rewards (RBR). Instead of asking a human labeler, "Is this answer bad?", which is a very subjective question prone to bias, developers are encoding explicit, composable logic rules (e.g., "refusal must be neutral" or "never provide medical diagnosis").
In a landmark shift, Mu et al. (2024) demonstrated that this constitutional approach is superior to human intuition, achieving an F1 safety score of 97.1 compared to just 91.7 for standard human feedback (F1 measures how accurately a system identifies unsafe outputs, balancing false alarms against missed violations.) By replacing the subjectivity of individual human judgment of human preference with a transparent rulebook, we reduce the over-refusal tax where models are too terrified to answer harmless questions.
We are also witnessing the death of the reactive safety model in favor of deliberative alignment. Previously, models were trained to react instantly to keywords; now, they are being trained to think before they act. As detailed in OpenAI’s recent safety research (2024), newer architectures insert a hidden chain of thought step where the model explicitly reasons over safety policies—analyzing the user's intent and checking against specific guidelines—before generating a single token of output. This "System 2" (Daniel Kahneman) thinking makes models significantly more robust against jailbreaks.
We began with a question: how did AI models get better? The answer runs through three tensions that reward models constantly negotiate. For bias, the fix for overcorrection is never less alignment. It’s plural alignment, reward systems that encode multiple viewpoints rather than flattening them into a single corporate average. Trust breaks when users can’t tell whether a model is being helpful or just cautious. Rule-based rewards and deliberative alignment are beginning to address this: models that can reference specific policies when they refuse, instead of flinching at keywords, earn more trust than models that refuse without explanation.
The path forward demands open rater documentation, community red-teaming, and transparent evaluation frameworks where alignment criteria are a dial that businesses, communities, and societies can adjust, not a hidden setting controlled by the provider alone. Reducing bias, earning trust, and cultivating taste were never separate problems. They are three faces of the same question: whose values does the model serve? The answer should be auditable, plural, and, above all, ours to define.
Taste is the newest and, to the arthur, the ultimate frontier. It deserves a different kind of protection. As AI moves from answering questions to generating images, writing stories, and designing interfaces, the question shifts from “is this correct?” to “is this good?” and who gets to judge. The industry is at a crossroad. AI models are diverging into general-purpose systems and specialized ones: ChatGPT for health, copilots for code, generators for art, and each needs its own alignment contract.
Bias can be measured. Trust can be engineered. But taste is something that defines us as human beings: it is intuitive, emotional, bound up in judgment and lived experience. Taste serves creation. It serves art. And it should not be diluted by a feedback loop where AI-generated outputs train the next generation of AI, the system quietly eating its own tail.
Yes, prototypes get faster. Iterations get cheaper. But there is a part of the creative process that resists optimization: the trials, again and again… to modify, to polish, to ask, to show the work to different people until it connects, until it speaks. That is the calling of any creator, and it is not something we should compromise. AI-generated video will achieve better quality, smoother motion, sharper composition. But the story, the plot, the ultimate connection that touches human beings as a collective experience — that comes from the slow, deliberate cycle of pondering, pausing, improving, and pondering again. No reward model can and need to replace that.
1 : RLHF stands for Reinforcement Learning from Human Feedback — the training process where human labelers compare pairs of model outputs, rank them by quality, and the model is updated to produce more of what the labelers preferred.
2 : System 2 is a term borrowed from the psychology idea of “System 1 vs. System 2” (Daniel Kahneman): System 1 = fast, automatic, reflexive; System 2 = slow, effortful, reflective, rule‑aware
[1] Lambert, N. (2025). Reinforcement learning from human feedback. RLHF Book. https://rlhfbook.com ↗
[2] Lambert, N., Pyatkin, V., Morrison, J., Miranda, L. J., Lin, B. Y., Chandu, K., Dziri, N., Kumar, S., Zick, T., Choi, Y., Smith, N. A., & Hajishirzi, H. (2024, June 8). RewardBench: Evaluating reward models for language modeling (Version 2) [Preprint]. arXiv:2403.13787 [cs.LG]. https://arxiv.org/abs/2403.13787 ↗
[3] Wolfe, C. R. (2025, June 30). Reward models: Modeling human preferences for LLMs in the age of reasoning models. Deep (Learning) Focus. https://cameronrwolfe.substack.com ↗
[4] Sharma et al. (2023), "Towards Understanding Sycophancy in Language Models."
[5] Wei, J., et al. (2024). Chain-of-Thought Reasoning Improves Safety and Robustness. Google DeepMind.
[6] Mu, J., et al. (2024). Rule-Based Rewards for Language Model Safety. NeurIPS 2024. https://arxiv.org/abs/2411.01234
[7] OpenAI. (2024). GPT-4o System Card: Deliberative Alignment and Safety. OpenAI Research. https://openai.com/index/gpt-4o-system-card/
[8] Sorensen, T., et al. (2024). A Roadmap to Pluralistic Alignment. arXiv preprint arXiv:2402.05070.
[9] Wei, J., et al. (2024). Chain-of-Thought Reasoning Improves Safety and Robustness. Google DeepMind.
[10] Mu, T., Helyar, A., Heidecke, J., Achiam, J., Vallone, A., Kivlichan, I., … Weng, L. (2024). Rule Based Rewards for Language Model Safety. Advances in Neural Information Processing Systems 37. Rule Based Rewards for Language Model Safety ↗
[11] Guan, M. Y., Joglekar, M., Wallace, E., Jain, S., Barak, B., Helyar, A., … Glaese, A. (2024/2025). Deliberative Alignment: Reasoning Enables Safer Language Models. arXiv:2412.16339. Deliberative Alignment ↗
[12] Xu, J., Liu, X., Wu, Y., Tong, Y., Li, Q., Ding, M., … Dong, Y. (2023). ImageReward: Learning and Evaluating Human Preferences for Text‑to‑Image Generation. NeurIPS 36. ImageReward ↗
[13] Ba, Y., Zhang, T., Bai, Y., Mo, W., Liang, T., Su, B., & Wen, J‑R. (2025). Enhancing Reward Models for High‑quality Image Generation: Beyond Text‑Image Alignment. ICCV 2025. ICCV 2025 paper ↗
[14] Wang, W., Gao, Z., Chen, L., Chen, Z., Zhu, J., Zhao, X., … Wang, W. (2025). VisualPRM: An Effective Process Reward Model for Multimodal Reasoning. arXiv:2503.10291. VisualPRM ↗
[15] Lee, H., Phatale, S., Mansoor, H., Mesnard, T., Ferret, J., Lu, K., … Prakash, S. (2024). RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback. ICML 2024 (PMLR 235:26874‑26901). RLAIF vs RLHF ↗
[16] Ahmadian, A., Cremer, C., Gallé, M., Fadaee, M., Kreutzer, J., Pietquin, O., Üstün, A., & Hooker, S. (2024). Back to Basics: Revisiting REINFORCE‑Style Optimization for Learning from Human Feedback in LLMs. ACL 2024. ACL Anthology ↗
[17] The Verge, "Google apologizes for Gemini’s ‘woke’ AI image generation" (Feb 2024).
| Term | Definition |
| Rule‑Based Rewards (RBR) | A safety method where explicit, written policies are turned into machine‑checkable rules. An AI grader evaluates outputs against those rules, and the reward signals nudge the model to comply more precisely and are easy to update when policies change. |
| Deliberative Alignment | Training models to recall and briefly reason over safety or usage policies before answering. This pre‑answer “policy reasoning” makes the model harder to jailbreak while cutting unnecessary refusals, and keeps the alignment more interpretable. |
| ImageReward | A human‑preference reward model for text‑to‑image. Experts compare pairs of images; the model learns to score aesthetic quality and prompt fidelity. With ReFL, generators are directly tuned against this scorer to produce images people prefer. |
| ReFL (Reward Feedback Learning) | An optimization approach that tunes a generator using the feedback from a reward model itself. Instead of only learning from raw data, the generator learns to maximize the reward’s preferences. |
| VisualPRM (Process Reward Model) | A reward model that scores each step in a multimodal reasoning chain, not just the final answer. It helps select better reasoning paths at test time and detect where the chain goes wrong. |
| Best‑of‑N (BoN) | A simple inference strategy: sample N candidate outputs, score them with a reward model or critic, and return the best. It boosts quality without retraining the generator. |
| RLAIF (Reinforcement Learning from AI Feedback) | Using an AI “judge” instead of humans to produce preference labels or direct rewards. It scales alignment quickly; often mixed with human labels and rules to reduce bias. |
| Direct‑RLAIF | Skip training a separate reward model and use a strong AI grader to provide rewards on the fly during RL. Fewer moving parts, faster iteration. |
| ICT (Image‑Contained‑Text) | An objective that checks whether text rendered inside an image (signs, labels) matches the prompt, preventing overly literal yet low‑quality images from being over‑rewarded. |
| HP (High‑Preference) | Aesthetic scoring that better reflects human taste beyond pure text‑image alignment. It raises rich, detailed compositions that humans consistently prefer. |
| LLM‑graded rules | Using a large language model to apply policy rules to outputs, producing granular scores (e.g., severity, confidence) rather than a binary pass/fail. |
| Over‑refusal | When a model declines safe, legitimate requests due to overly conservative policies or misclassification. Modern alignment aims to reduce this without weakening safety. |
| Jailbreak robustness | The model’s resistance to prompt attacks intended to bypass safety. Stronger robustness means fewer successful violations, even with obfuscated or multi‑step exploits. |
| Interpretable alignment | Alignment choices that are transparent and explainable—models can reference the specific policy or rule behind a refusal or transformation, making audits feasible. |
| Policy compliance vs. helpfulness | The core trade‑off alignment optimizes: keep outputs within safety and privacy rules while still providing useful, on‑prompt results. |
[Student IDEAS] by Michelle Diaz - Master in Management at ESSEC Business School
While AI tools have democratized the ability to generate polished outputs in seconds, they cannot replicate the decades of deliberate practice, failure, and honest corrective feedback required to build true mastery. Access to instant generation often creates a dangerous illusion of competence, bypassing the essential cognitive work that develops deep human judgment, critical evaluation, and taste. Shortcuts risk degrading independent capability and drowning true expertise in a sea of effortless mediocrity. Ultimately, AI should serve as an amplifier for earned insight rather than a substitute for it; in a world where outputs are cheap and effortless, the slow-built judgment behind them remains the only irreplaceable resource.
---
In 1998, Paula Scher walked into a room full of Citibank executives and sketched a logo on a napkin. The arc over the t. The red curve borrowed from Travelers Group's umbrella. Done. The meeting had barely started. The sketch cost $1.5 million.
The room, predictably, was not pleased. Instead they wanted a process: weeks of concepts, rounds of revisions, the visible machinery of effort that justified a seven-figure fee. Instead, they got a second. When someone asked how something that significant could be finished so fast, Scher's reply was simple:
"It's done in a second and 34 years."1
Therein lies my argument. The second is the part you can see. The 34 years are invisible: accumulated through failure, repetition, correction, and the ever slow development of judgment that no shortcut produces. Citibank wasn't paying for the napkin. But rather for everything that made the napkin possible.
Now, consider what exactly happens in a society where anyone and everyone can generate a logo in mere seconds. AI tools compress the distance between an idea and a polished output, between a question and a researched answer, between zero competence and the convincing appearance of one. The second has been democratized. Unlike the 34 years.
I’m gonna talk about that gap: between knowing nothing and knowing something so deeply it feels like intuition. About what it takes to cross it, what the process actually demands. And most crucially: what disappears when it’s skipped. And why, in our modern world, where producing an output has never been easier to fake, the people who did it the hard way might very well turn out to be the ones we’ll eventually have to call.
Historically, mastery is a word people use freely, but rarely with precision. It gets attached to six-month habits and morning routines and anyone who has gotten noticeably good at something in a short time. Used this way, it’s more motivational than meaningful. So before arguing about what AI does to mastery, let’s be honest about what it actually is. And what it isn’t.
Figure 1 maps the distinction:

The research on expertise isn’t romantic. It doesn't reach for words like passion or gift. Scholars in the field describe it as a sequence: motivated engagement, clear objectives, focused repetition, feedback that arrives in real time, and standards that must be demonstrably met before you move forward2. Not when you feel ready. But when the standard is met. Only then does the loop truly close.
What separates this from mere repetition is the quality of honesty inside it. A musician running scales without listening critically to the sound they're making isn't building mastery. Sure, they're accruing hours. But the loop only works when it's truthful.
And that truthfulness? It’s uncomfortable. Painfully uncomfortable. Genuinely corrective feedback tells you exactly what you got wrong. It asks you to sit with inadequacy long enough for your understanding of the problem to change. Most people find this, over time, intolerable. The ones who don't, tend to describe the experience not as enjoyment but as compulsion; something that pulled them back even when the results were painfully discouraging.
Phyllis Elago, a trained classical musician, now also a writer and translator, describes it with the precision of someone who has lived inside both disciplines:
"By doing it again and again and observing your results each time, you learn how to connect to your body and your brain so that you can do whatever you want at will. Then it becomes easy. Until then, if you are still suffering, the audience will suffer with you."
See, the thing is, research shows that the act of learning leaves a physical imprint on the brain, not simply an experiential one. Consider the landmark study of taxi drivers. The study found measurable growth in the part of the brain responsible for spatial memory, with volume increasing in direct proportion to years of experience3. In other words, expertise doesn’t accumulate as a larger catalog of techniques filed away for later use.
A chess grandmaster doesn’t calculate more moves than a novice; they simply look at the board differently from the first glance. Similarly, a seasoned musician doesn’t rely on trial and error to find key combinations; they already know which keys tend to work better with which. Decades of honest repetition and learning don’t just make you faster, it changes the way you look and what you see.
One can read about mastery, cite it, admire it from a safe distance. But it has to be lived through. The repetition, the failure, the small corrections, the incremental and often invisible progress. None of it is merely the road to the capability; it is the capability, being assembled slowly, in the only way it ever could be. It's easy enough to watch a seasoned pianist play Beethoven's Sonata No. 29 in B-flat major. Harder, to replicate it by simply knowing how to read the notes.

Now, to be very clear: none of this is an argument against AI tools. AI compresses the zero to one journey in specific, real, and when used consciously, quite often genuinely useful ways.
For example, a student learning to code gets instant feedback on errors that once required a teacher or a patient colleague. Or a designer iterates in minutes what once took days. And a junior analyst drafts in an hour what once consumed a week. These are not trivial gains and dismissing them wholesale is its own kind of intellectual dishonesty.
However, there is a difference between the compression of a process and the offloading of the cognitive work within the process. And therein lies the issue.
A recent study at Stanford’s Human-Centred AI institute put it plainly: students performed better on tasks when AI tools were made available to them. And once the tools were removed, the advantage disappeared entirely. More troubling still, the students who had grown accustomed to and reliant on the AI assistance - and then lost access, performed dramatically worse than their peers who had never used AI tools at all. In one measure of creative performance, they worsened by four times4. In essence, the access to AI tools quietly, but surely degraded the operator (the students).
The pattern holds beyond the classroom. Indeed, the Stanford 2026 AI Index found that engineers who leaned on AI for learning picked up “learning penalties” —measurable slowdowns in their independent development over time5. And open-source developers using AI assistance became, on certain complex tasks, slower than their counterparts working without the assistance. So the ceiling, as it turns out, is not access to tools, but rather the judgement to use them well. And judgement is precisely what the shortcuts are bypassing.
Kateryna Sazanova, an Emmy award-winning director and producer with well over twelve years across film, television, and digital production, describes it as a kind of readiness that only truly accumulates through repetition:
“Working on set is very concrete and tangible, with lots of moving parts, and everyone needs to be fully ‘on’,” she says. “Such experience cannot be replaced by reading or talking about it.”
Paula Scher didn't sketch that logo out of sheer talent or luck. She sketched it from her internalised decades of failed attempts, difficult client briefs, wrong directions, and most likely very painful corrections. It’s the accumulation of all those experiences that gives rise to taste, judgement, or that almost magical ability to know immediately what’s off. That kind of skill isn't stored in a file. It doesn't wait for the right moment to be needed. It either exists, built slowly through the loop, or it doesn't. An AI that produces a logo in a second doesn't contain Scher's 34 years.
It contains a statistical average of everyone else's. Do we want to simply be average? Had the majority of humans contented themselves with mediocrity, all these debates around AI might very well be moot.
As such, this is the more subtle danger, which goes largely unremarked in conversations around AI’s impact on work. Indeed, the concern most often voiced is displacement; that the tools will themselves take the jobs. But the quieter, more consequential concern ought to be substitution: people will use the tools to produce outputs they don’t fully understand, will have a hard time defending themselves, in domains they haven’t earned the right to navigate. A medical student who uses AI to arrive at a diagnosis without developing clinical reasoning isn’t a better doctor. Similarly, an architect who uses AI to generate a hundred options in a few hours without the taste to evaluate them isn’t a better architect. These are simply people holding and presenting outputs they can’t interrogate, in fields whose depth they haven’t entered.
The seconds are now on offer to everyone, and that alone really is extraordinary.
But what hasn’t changed is what those 34 years actually add up to. Or what quietly slips away when an entire generation decides the seconds are good enough and stops reaching for anything more.

Scale this up. What happens to one student, designer, or engineer compounds when it happens across whole cohorts, across industries, institutions, generations of people entering professions having produced outputs they were never required to fully understand. The individual cost of skipping the loop is a quieter kind of incompetence. The collective cost is something harder to name, slower to notice, and potentially irreversible.
The people closest to the technology have sensed it. The EY 2025 Work Reimagined Survey put it plainly: a significant portion of UK employees worry that AI is doing something to their capabilities they can't quite name; that "an overreliance on AI could erode their skills and expertise6.” These people aren’t outsiders looking in, nor are they critics with an agenda. Instead, these are people using the tools, seeing something happen to their own capabilities in a way that’s hard to articulate.
Now, the data, when it catches up, tends to confirm this experience. AI adoption at work has grown rapidly: 44% of UK employees now report using it at work7. But a closer inspection of the distribution is telling. Fewer than 5% are “using AI to fundamentally transform the way they work.8” The rest are producing faster, smoother, more polished versions of work whose underlying quality hasn’t moved, reiterating that access was never the ceiling. Judgement is; and that judgement is one thing the adoption statistics haven’t quite measured.
Navada Currie has spent a decade in design: across agencies, non-profits, freelance work, and nationally recognised campaigns in Australia, among them the World's Greatest Shave, which has raised over fifteen million dollars. She can see the difference:
“People who've taken the long road tend to bring a deeper level of understanding to their work. They're not starting from zero each time; they're drawing on years of practice, mistakes, references, and problem-solving. That depth becomes its own kind of shortcut."
According to her, the thing that shows up isn’t polish, but judgement. Shortcut-driven work can solve the more visible parts of a project brief, but it’ll struggle to survive the question of why:
"AI-generated branding can produce something decent-looking very quickly, but it often lands on the first obvious solution. A skilled designer will push beyond that — shaping something that connects to the brand's wider story."
Kateryna Sazanova, whose twelve years in film production and 2025 Emmy Award give her a particular vantage point on this, put it plainly:
“Now we see a flood of bad content. No matter what tools you use, it takes craft and mastery to produce a good story that will resonate, inspire, connect, give a new perspective, motivate for action and stay with the audience for a long time.”
Once you zoom out, the irony is kind of staggering. AI has made mediocrity effortless and excellence a lot harder to see. So when every student produces a polished essay, or a junior employee a competent presentation, or a designer a slick visual, the signal that once clearly separated deep capability from surface performance gets lost. And the noise rises. The people who actually made the hard journey become much harder to identify, and organisations can no longer tell the difference.
But most work requires a human touchpoint, be it a presentation, a defense, or a live critique; the gap reveals itself eventually. The tools didn’t create this dilemma. They’ve just made it far easier to avoid confronting, until the worst possible time.

Consider what the loop actually produces, beyond technical capability. It produces failure literacy: the ability to recognise when something is going wrong before it has fully gone wrong. It produces taste, which is just a fancy word for the accumulated weight of every bad decision made and eventually, corrected. Isn’t that the kind of confidence that doesn’t normally announce itself? Because it’s built on evidence rather than outputs? These things aren’t exactly transferable. Not exactly teachable in the conventional way. They accrue slowly through the loop, showing up in how a person moves through a problem and not simply by what a person produces. Hence why professional schools across disciplines don't just teach theory; medicine mandates clinical rotations, law builds moot courts, architecture runs studio critique, business runs live consulting cases. The form changes. The underlying principle doesn't.
Now put that person in a room with AI. They can generate a hundred options and immediately know which ones are worth pursuing. They can work from an AI draft and understand why something is almost right, but not quite... They can use the tool at speed and trust their own judgment about when the tool is failing them. The 34 years don't become irrelevant in that room. Rather, they become the only thing that matters. Again, this isn't a case against AI as a tool. It's a case for sequencing: for building enough to know what you're looking at before you ask a machine to generate more of it.
I want to be very careful. People who skip the loop aren't without ability. They can produce. Sure. What they struggle to do is evaluate, interrogate, and redirect— the work that happens after the output exists. And that is precisely the work that AI can’t do on their behalf, because that’s the work that requires a human to have a well-informed opinion about what excellence actually looks like.
In a world where the output has been democratized, judgment is the scarce resource.
It always was. It's just easier to see now.
Let’s return to that room with Scher: the executives, the napkin, the red arc over the t, the sketch that took a mere second, and the room that couldn’t see the 34 years standing behind it.
What they were looking at, without knowing it, was the product of a process so incredibly long and internal that it practically dissolved into invisibility: the failed pitches, the wrong directions, the arduous accumulation of knowing what doesn’t quite work and why—all of that compressed into a single, and quite frankly, unremarkable moment that only looked effortless because of everything it contained.
We live in a culture that has essentially built something that can replicate that moment: the sketch, draft, deck, diagnosis; generated, polished, delivered. Fast and clean and competent. And increasingly indistinguishable on the surface from the work of someone who’s spent years earning the right to produce something.
But surfaces are not the entire story. Frankly, when are they ever?
The question I want to leave you with isn’t whether to use the tools. Use them. The question is whether you’re building something underneath the tools’ usage; something that would survive if the tools disappeared tomorrow. Something that’s yours, assembled slowly through an iterative loop, through the long and often thankless distance between not knowing and knowing deeply.
That distance has a name. And I’d argue it’s worth every step.
[1] Paula Scher, Abstract: The Art of Design, Season 1, Episode 6, dir. Richard Press, Netflix, 2017.
[2] McGaghie, W.C., Issenberg, S.B., Cohen, E.R., Barsuk, J.H., & Wayne, D.B. (2011). Does simulation-based medical education with deliberate practice yield better results than traditional clinical education? A meta-analytic comparative review of the evidence. Academic Medicine, 86(6), 706–711. / Mastery learning framework: see also Bloom, B.S. (1968). Learning for mastery. Evaluation Comment, 1(2), 1–12.
[3] Maguire, E.A., Gadian, D.G., Johnsrude, I.S., Good, C.D., Ashburner, J., Frackowiak, R.S.J., & Frith, C.D. (2000). Navigation-related structural change in the hippocampi of taxi drivers. Proceedings of the National Academy of Sciences, 97(8), 4398–4403. https://www.pnas.org/doi/10.1073/pnas.070039597
[4] Lichand, G. et al., cited in: Stanford Human-Centred AI, AI Challenges Core Assumptions in Education, February 2026. https://hai.stanford.edu/news/ai-challenges-core-assumptions-in-education
[5] AI Index Steering Committee, Artificial Intelligence Index Report 2026, Stanford University, April 2026. https://www.starkinsider.com/2026/04/stanford-2026-ai-index-report.html
[6] EY 2025 Work Reimagined Survey, December 2025. https://www.ey.com/en_uk/newsroom/2025/12/uk-employers-miss-40-percentage-ai-gains-talent-gaps
[7] EY, "UK's AI Adoption Surges in Daily Life, but Lags Behind in the Workplace," EY AI Sentiment Index, 15 April 2025. https://www.ey.com/en_uk/newsroom/2025/04/ey-ai-sentiment-index-2025
[8] EY 2025 Work Reimagined Survey, December 2025. https://www.ey.com/en_uk/newsroom/2025/12/uk-employers-miss-40-percentage-ai-gains-talent-gaps
[ARTICLE] By exploring nearly 300,000 Meta Horizon reviews, this study introduces "spatial word of mouth" (spatial WOM) to reveal how immersive factors like community, motion sickness, and immersion uniquely drive the success of virtual reality apps in the metaverse.
by Raoul V. Kübler (ESSEC Business School), Thorsten Hennig-Thurau
In the metaverse, virtual reality (VR) apps serve as key gateways to consumers, making it critical for retailers and brands to understand the drivers of VR app success. This study introduces spatial word of mouth (WOM)—consumer-generated communication in high-immersive digital environments—and examines how VR app reviews in a metaverse app store, as prominent kind of such spatial WOM, are linked with app performance. Using topic modeling and aspect-based sentiment analysis, we analyze nearly 300,000 reviews from 153 VR apps on Meta’s Horizon store, alongside 1.5 million reviews of 2D apps from Steam. We identify 10 spatial-WOM topics, four of which are unique to VR (immersion, community, playtime, and motion sickness) and six are shared with traditional electronic WOM. Linear mixed-effects regression reveals that all 10 topics are linked to spatial-WOM valence (a measure of app satisfaction), while five are associated with spatial-WOM volume (a proxy for app downloads). A spatial WOM valence-volume matrix offers practical insights for retailing and brand managers to engage VR app users effectively, and a research agenda for advancing spatial-WOM studies in retailing and marketing provides a foundation for future exploration in this emerging domain.
[Please read the research paper here]
If you want to read another article, check this one out.
[Student IDEAS] by Karen Taubenberger and Michelle Diaz - Master in Management at ESSEC Business School
This article explores the legal and existential tension between generative AI and copyright law, arguing that the depletion of human-generated data poses a threat to AI’s own development. By analyzing cases like Kashtanova and Getty Images, it highlights the "grey zones" of authorship and the risk of "model collapse" when AI is forced to train on its own synthetic outputs. Ultimately, the author contends that protecting creators through new licensing models is essential to prevent a "world starved of creativity" and ensure a high-quality data supply for future innovation.
---
On March 25, 2025, OpenAI dropped a new image-generation feature with its GPT-4o release, stirring immediate controversy1. The tool lets users whip up stylized visuals that eerily mimic the signature styles of iconic studios like Studio Ghibli. Notably, co-founder Hayao Miyazaki, a fierce critic of AI art, slammed it as “an insult to life itself2”.
Similarly, the Writers Guild of America (WGA) went on a months-long strike in 2023 over fears that generative AI threatens writers’ livelihoods, halting production on numerous TV shows and films. At the same time, headlines have been flooded with copyright infringement claims during AI model training. All this seems to point to one thing: Generative AI has a copyright problem. In the mid- to long-term, this isn’t just a problem for creators: AI companies might feel the fallout too.
Generative AI (GenAI) refers to artificial intelligence systems designed to create original content, rather than just analyzing existing data. These systems generate new material by identifying and learning complex patterns from vast datasets using different techniques. For instance, they can understand and generate text by recognizing relationships between words (transformers3) or identify key features in images, sounds, or designs and use them to create new versions (autoencoders4). This ability to independently create instigates concern on who should be credited as the creator, how rights should be assigned, and whether such creations can be legally protected5.
Copyright was built for a human world, with its earliest statute dating back to 1710. Originally designed to protect “literary, scientific, and artistic works” such as poems, films, or songs6. It grants creators exclusive rights that fall into two categories: economic rights, which allow them to control and earn from the use of their work, and moral rights, which protect their personal connection by ensuring they are credited and can prevent changes that alter the original. In the EU, these protections last for 70 years after the creator’s death7.
Importantly, the moment you create something original, it’s protected. “All rights reserved” is applied automatically, no formal registration needed. However, one core principle underpins all copyright law: the author must be human.
That’s where things get complicated in the world of AI. For instance, if a programmer (a human) writes software code, that work is protected by copyright8. Similarly, if a human writes the training code that enables a machine-learning model to function, that code is protected. But what about the output of the model itself? Going forward, one of the most tricky issues will be around authorship and ownership of works created and co-created by AI.
Historically, copyright has been quite clear in terms of ownership. Whoever or whatever entity creates a certain piece of work/way of working clearly owns the rights so long as they are able to prove and register ownership. In a sense, there’s a clear thread between what is produced and the human/s that were involved in the production.
In an age where one can produce or create something that is not entirely human-made or can be a combination of both(purely human-made and co-created by AI), where do we draw the line? In 2023, the US Copyright Office made a clear stance on the sufficiency of human authorship required to be copyrightable. The US Copyright Office ruled on Kashtanova, a case on AI-generated imagery in creative works. The case involved a graphic novel that combined human-written text and imagery produced by Midjourney (AI image generator). Essentially, the Office ruled that it could not register the images, given that no matter how detailed the text-prompts were, the AI’s output remains unpredictable and therefore beyond the artist’s direct control. The Kashtanova case created a precedent and cases following it remained true to the strict requirement of human authorship: “human authorship is the bedrock requirement of copyright9.”
However, the US Copyright Office did not unilaterally dismiss the possibility that a human might be recognised as an author of an AI-generated piece of work. But the office didn’t exactly lay out clear guidelines either. To have a good chance of registering a claim of authorship, the human/s involved must either prove heavy involvement in the creation of the work (training input of the model, process, etc) or demonstrate sufficient human authorship10.
This leaves legal grey zones even in everyday life. Would one need to cite AI-generated images in a presentation for example? If they are not subject to copyright this should not be necessary (similar to an open source picture). But yet, a check of the citation requirements of different universities results in very different opinions on this matter (and also APA 7th or Chicago: citation styles used in academic writing, have no clear guideline).
Perhaps more complicated and difficult than delineating what combination and weightage of AI and human authorship combo can be protected by law, is the actual enforcement of the law itself. And whether the large-scale harvesting of organic (human created) works should be illegal under existing copyright laws.
Consider how a claimant might prove authorship of an AI-generated work. Or alternatively, how one might dispute the claim that a work is not AI-generated in some way. Where does the burden of proof lie? Proving an AI made something is difficult since the AI can give different results even with the same prompt, and AI companies refuse to take responsibility for their outputs. OpenAI’s terms mention “acknowledge that multiple users might receive identical or similar results”, while Microsoft's Copilot terms contain similar provisions11. This traceability problem matters most once a work goes public, since copyright protection and authorship only kick in when something is actually shared (aka diffusion). This inability to draw a clear line poses issues for users that seek to claim rights for commercial purposes.
This lack of clearly defined ownership further becomes problematic once you consider what happens to the data. Microsoft Copilot and similar services include terms that allow companies to use any data you upload to train and further improve their AI. In other words, users are not only unable to claim ownership of outputs, they also give the companies consent to use their own inputs to generate new content. Thus creating a double bind: you have no right to what the AI produces, and the company gains rights to everything you feed the AI. A clearly asymmetrical benefit.
Another case that highlights this issue is the legal battle between Getty Images and Stability AI. Essentially, Stable Diffusion, a product by Stability AI “was trained on 2.3bn images from a third-party website which pulled its training images from the web, including copyright image archives such as Getty and Shutterstock12.” Hence, the core question at the heart of the legal debate is whether this large-scale harvesting of organic (human created) images should be banned under the current copyright laws.
As of November 2025, Getty Images lost their copyright infringement claims, while narrowly winning trademark claims. In essence, the court arrived at these decisions since:
So how do you draw the line between necessary information usage and copyright infringement? Is it in the contention between how much AI is in a particular piece of work and how much human involvement is required? Or perhaps it comes down to technicalities like where the training occurs, as illustrated by the Getty Images case?
Or is it around the commercialization of the model, what is a fair price for the information a model uses for the monetisation of that information? Is it the ability of a model to generate “near verbatim” pieces of work14?
After all, LLM makers can easily deflect blame for problematic outputs by claiming users simply didn't prompt effectively enough. Since prompting has become an essential skill everyone is learning. In essence, the LLM companies can pass on blame to the users, since they did the prompting, and should therefore be responsible for the output. What a convenient way to shift accountability from LLMs providers to consumers; a classic attention economy dynamic where end-users bear responsibility as companies attempt to escape scrutiny.
Another vital consideration going forward with AI is the availability of data on which it is trained on, given the speed at which the foundational models are eating up data to continuously improve their output. As incentives for creators erode, original content grows rarer, while AI-generated material increasingly saturates the internet, feeding feedback loops.
According to a San Francisco-based AI research group, Epoch AI, at the current rate at which models are eating data, the total amount of human-generated content found on the internet could run out as early as 2026:
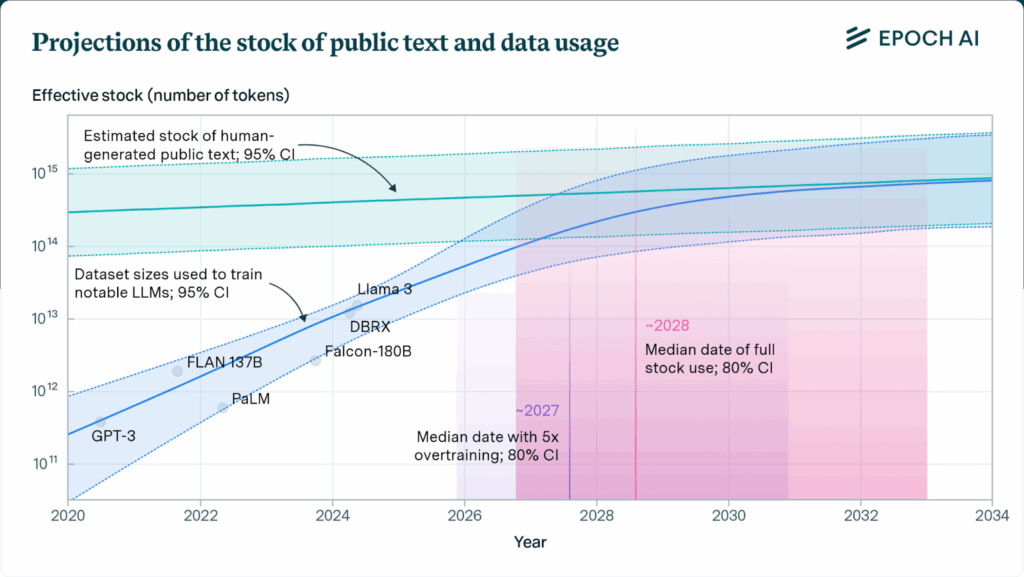
Graph (fig.1) illustrates the number of existing human-generated texts that are publicly available. And the different LLMs and the speed at which they’re digesting the information.
In essence, two main bottlenecks would be the overall availability of data, and the rate at which society produces genuinely-human created content (affected by the ease of producing AI materials rather than creating organic data given the lack of protections in place). With improvements in model scaling and computing efficiency the impact of these constraints can be slowed:
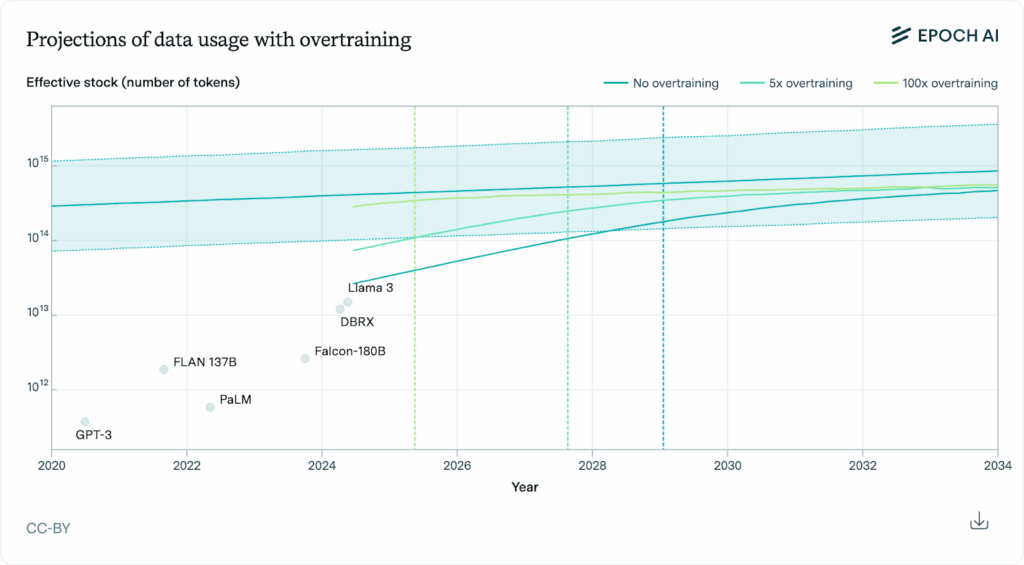
The graph (fig.2) shows the growth in training dataset sizes (measured in effective stock of tokens) against the available stock of data over time. It compares three scenarios—no overtraining (compute-optimal scaling), 5x overtraining, and 100x overtraining—showing that aggressive overtraining depletes the data stock much faster, potentially by 2025, while no overtraining delays exhaustion until around 2030.
But even with these adjustments, the data will still run out before 2030. This analysis mainly focuses on public human text data, but their estimates of the data available out there delineates all that exists:
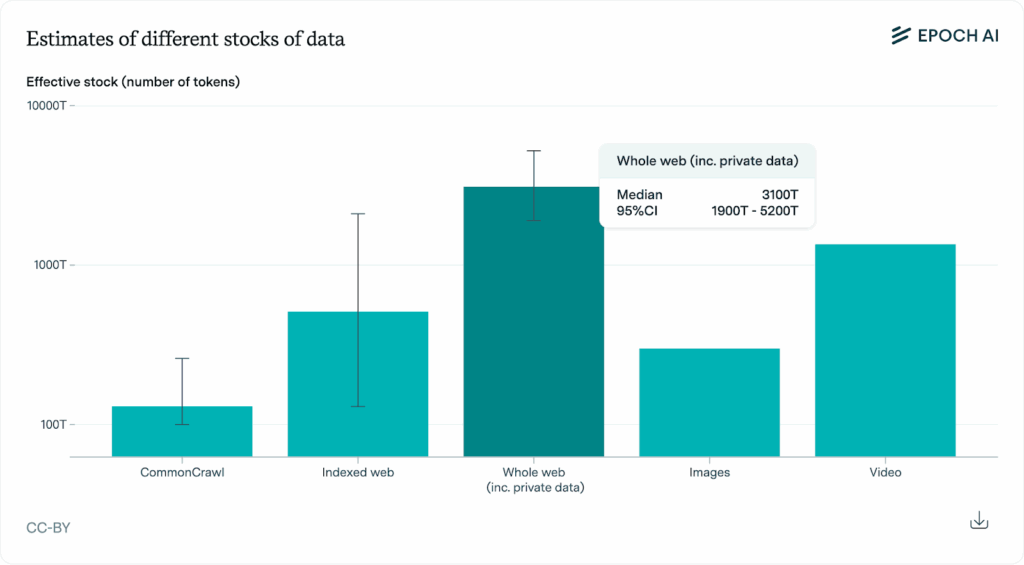
This bar chart (fig.3) estimates how much usable data (in tokens) exists in different sources: Common Crawl, the indexed web, the entire web including private data, images, and video. It shows that the whole web and video contain the largest estimated data stocks, with substantial uncertainty ranges indicated by the error bars.
As publicly and legally available data becomes increasingly scarce, one can see a clear incentive for malicious behaviour to arise. From training on copyrighted data, to scraping content online without users explicit consent, adopting artistic styles of artists without permission. In fact, companies are already edging (some leaping, hello OpenAI, apologies Miyazaki) and pushing the limits on this. On April 14, 2025, Reuters reported that Meta (parent company of Facebook and Instagram) will start using the public posts, comments, and interactions of its users to train its AI models across all its platforms within the EU, effective on May 27, 202518.
Companies are also exploring other ways to bypass this major problem, such as generating synthetic data. AI-generated data would be a potential solution to the impending scarcity of data and a workaround to IP and privacy issues. Indeed, a plausible strategy could be having the AI models use “a technique called test-time compute in which the AI responds to a prompt by breaking it down into multiple tasks. Instead of spitting out an answer instantaneously, the model spends extra time “thinking” before generating an outcome.
These higher-quality responses could be turned into a new training data set for the AI, which in theory, could improve its responses19.”
Unfortunately, it’s not that simple. A study that looked into using synthetic data for training models revealed that the “model collapse” phenomenon can arise. This leads to lower-quality outputs being produced, which eventually circulate on the web and are later used as training data for future models. In the end, it could create a problematic loop that ends in the inevitable collapse of the model20. All this to say that we are currently at a stage where there seems to be a lack of viable solutions to address the rapid and wide consumption of organic data necessary for AI models to continuously improve.
As the seas calm from OpenAI’s controversial image-generation rollout and the echoes of the Writer’s Guild of America strike still linger, it’s clear that Generative AI has copyright problems. Miyazaki’s misgivings, the collective action of writers, and the uptake in infringement claims underscore the need for a solution. Not just for the sake of creatives, but for the continued advancement of AI as well.
Given the issues we’ve outlined above and the ongoing controversies surrounding the relationship between AI and copyright, it’s easy to fall into a dichotomy: human creators vs AI companies. Strong copyrights don’t just protect creators, they are also the backbone of innovation, incentivizing original work, which in turn prevents AI models from plateauing.
As copyright adjusts to an AI world, new models have to emerge to align the interests of creators of AI companies and creators. Imagine a system where creators could opt in to share their work, earn automatic royalties and let AI learn without infringing. A new marketplace that ensures that we never run out of original ideas. Disney’s and OpenAI’s recent $1 billion investment and licensing partnership, enabling Sora to generate fan-prompted videos and images from 200+ Disney, Marvel, Pixar, and Star Wars characters, illustrates one such win-win collaboration21. Copyright law needs to catch up fast, or we risk letting the next generation of AI to train on a world starved of creativity.
1. Generative AI Is A Crisis For Copyright Law. Forbes. April 2025. Available at: https://www.forbes.com/sites/hessiejones/2025/04/03/generative-ai-is-a-crisis-for-copyright-law/
2. ChatGPT’s Studio Ghibli AI Art Trend Is an Insult to Life Itself. Gizmodo. March 2025. Available at: https://gizmodo.com/open-ai-ghibli-trend-miyazaki-chatgpt-2000581679
3. A transformer model understands text by looking at a sequence of words at once and learning how the words relate to each other, which allows it to capture context more accurately than word-by-word approaches.
4. An autoencoder is a type of neural network that learns important features in data without labels (unsupervised learning) by compressing inputs into an efficient representation and then reconstructing the original input as accurately as possible from this compressed code.
5. Interactions Between Artificial Intelligence and Intellectual Property Law. Max Planck Institute for Innovation and Competition. Available at: https://www.ip.mpg.de/en/projects/details/interactions-between-artificial-intelligence-and-intellectual-property-law.html
6. Copyright history. Intellectual Property Rights Office. Available at: Copyright HistoryIntellectual Property Rights Officehttps://intellectualpropertyrightsoffice.org › copyright_...
7. Copyright - Your rights. Europa.eu. Available at: https://europa.eu/youreurope/business/running-business/intellectual-property/copyright/index_en.htm
8. Gaffar H., Albarashdi S. Copyright Protection for AI-Generated Works: Exploring Originality and Ownership in a Digital Landscape. Asian Journal of International Law. Published online on: 23 January 202. Available at https://www.cambridge.org/core/journals/asian-journal-of-international-law/article/copyright-protection-for-aigenerated-works-exploring-originality-and-ownership-in-a-digital-landscape/12B8B8D836AC9DDFFF4082F7859603E3
9. Human Authorship Requirement Continues To Pose Difficulties for AI-Generated Works. Perkins Coei. February 2024. Available at: https://perkinscoie.com/insights/article/human-authorship-requirement-continues-pose-difficulties-ai-generated-works
10. AI Can Create a Painting but It Can’t Register a Copyright in the Painting. Perkins Coei. May 2022. Available at: https://perkinscoie.com/insights/blog/ai-can-create-painting-it-cant-register-copyright-painting
11. AI and authorship: Navigating copyright in the age of generative AI. DLA Piper. February 2025. Available at: https://www.dlapiper.com/en/insights/publications/2025/02/ai-and-authorship-navigating-copyright-in-the-age-of-generative-ai
12. Art and artificial intelligence collide in landmark legal dispute. Financial Times. January 2023. Available at: https://www.ft.com/content/d691d599-3cdb-48d8-9824-9b2784a17d90
13. Getty Images v Stability AI: Getty’s copyright case against Stability AI fails. Pinsent Maisons. November 2025. Available at: https://www.pinsentmasons.com/out-law/news/gettys-copyright-case-against-stability-ai-fails
14. NYT v. OpenAI: The Times’s About-Face. Harvard Law Review. April 2024. Available at: https://harvardlawreview.org/blog/2024/04/nyt-v-openai-the-timess-about-face/
15. Will we run out of data? Limits of LLM scaling based on human-generated data. Epoch AI. June 2024. Available at: https://epoch.ai/blog/will-we-run-out-of-data-limits-of-llm-scaling-based-on-human-generated-data
16. Will we run out of data? Limits of LLM scaling based on human-generated data. Epoch AI. June 2024. Available at: https://epoch.ai/blog/will-we-run-out-of-data-limits-of-llm-scaling-based-on-human-generated-data
17. Will we run out of data? Limits of LLM scaling based on human-generated data. Epoch AI. June 2024. Available at: https://epoch.ai/blog/will-we-run-out-of-data-limits-of-llm-scaling-based-on-human-generated-data
18. Meta to use public posts, AI interactions to train models in EU. Reuters. April 2025. Available at: https://www.reuters.com/technology/artificial-intelligence/meta-use-public-posts-ai-interactions-train-models-eu-2025-04-14/
19. Data Is Fueling the AI Revolution. What Happens When It Runs Out?. Cal Alumni Association. March 2025. Available at: https://alumni.berkeley.edu/california-magazine/online/data-is-fueling-the-ai-revolution-what-happens-when-it-runs-out/
20. Shumailov, I., Shumaylov, Z., Zhao, Y. et al. AI models collapse when trained on recursively generated data. Nature. Published online: July 2024. Available at: https://www.nature.com/articles/s41586-024-07566-y
21. The Walt Disney Company and OpenAI reach landmark agreement to bring beloved characters from across Disney’s brands to Sora. OpenAI. December 2025 Available at: https://openai.com/index/disney-sora-agreement/
[Student IDEAS] by Hugo Jalet - Global BBA at ESSEC Business School
The rapid expansion of ESG data and divergent rating methodologies have undermined the credibility and consistency of sustainability scores, enabling greenwashing and investor confusion. While the EU’s CSRD introduces reporting standards, it stops short of unifying rating criteria. Artificial intelligence (AI) offers tools to structure ESG assessments, detect inconsistencies, and enhance transparency. However, AI faces limitations: data biases, opacity, interpretive challenges, and significant environmental costs. Effective ESG scoring requires a hybrid model combining AI capabilities with human oversight, regulatory standards, and open-source approaches. Used responsibly, AI can support more reliable, transparent, and sustainable ESG evaluation systems—without replacing human judgment.
---
The rise of environmental, social and governance (ESG) criteria has transformed the way companies are assessed, both by governments and by banks and other finance companies. However, this development has also led to a significant ESG data explosion, compounded by a lack of harmonized ratings. Although the Corporate Sustainability Reporting Directive (CSRD) standards, which came into force in Europe at the beginning of the year, are intended to provide issuers with a more precise framework, their precision will not automatically lead to standardization and properly consolidated reporting. This fragmentation and non-standardization of data create fertile ground for greenwashing, which essentially means falsely portraying something as environmentally friendly, with some companies artificially embellishing their ESG performance without any real commitment to sustainability.
Artificial intelligence is often presented as a solution to these challenges. According to Del Vitto (2023), advances in machine learning make it now possible to analyze vast sets of ESG data, identify the decisive criteria in assigning scores and make the decisions of rating agencies more explicable . In addition, thanks to AI, it is also possible to track down inconsistencies between companies' declarations and their actual actions, thus contributing to the fight against greenwashing (Moodaley et al., 2023). AI is therefore a powerful yet imperfect tool for structuring ESG ratings. It carries significant limitations: it can reinforce existing biases, lacks full transparency, and demands considerable energy resources. Moreover, most real-world applications of AI in ESG continue to depend on human auditors to validate findings, making the prospect of a fully autonomous ESG rating system improbable in the near term.
The central question remains: can AI genuinely harmonize ESG ratings and establish a more coherent framework, or does it risk reinforcing confusion by adding another layer of opacity? The answer likely lies in the balance between technological innovation, regulatory oversight, and human expertise.
The lack of standardisation between the various rating agencies is one of the major challenges to the credibility of ESG criteria. Ratings are based on proprietary methodologies, which leads to variations and noise that can be very significant. MSCI1 takes an industry approach, Sustainalytics2 focuses on risk exposure, while Refinitiv3 focuses on reported quantitative data. Del Vitto et al. (2023) note that ESG rating agencies rely on distinct methodologies tailored to their own frameworks, which leads to significant variations in how the same company may be assessed across different providers, to such an extent that empirical studies show score variations of up to 50%. Differences in scope, indicator measurement and different weightings are the primary drivers of these discrepancies. Even though the CSRD in Europe seeks to harmonise the publication of ESG data, it does not impose a single rating methodology. This gap leaves room for AI-based solutions, which could help to align rating methodologies.
| Company | Business Sector | Refinitiv | MSCI | Sustainalytics |
| Tesla | Automotive | B (63/Good) | A (Average) | 28.6(Medium Risk) |
| Exxon Mobil | Energy | B (66/Good) | BBB (Average) | 36.5 (High Risk) |
Table 1.0 : Thomson Reuters, Refinitiv ESG score. ESG period: June 2022.
There are several AI-based initiatives to harmonise ESG ratings. SESAMm4 is one such solution. It specialises in analysing ESG controversies using AI, processing huge volumes of data from the media, reports and regulations, although this solution remains a hybrid approach in which ESG analysts validate the information generated. Adding to this, Clarity AI5, integrates ESG assessments directly into investment platforms, allowing asset managers to standardize their evaluations while meeting regulatory requirements. Beyond asset owners and managers, large corporations are also turning to AI tools such as C3 AI6, which helps transform ESG reporting from a mere compliance exercise into a strategic opportunity. As the adoption of these technologies accelerates, striking the right balance between automation and expert validation will be crucial to ensuring the reliability and credibility of ESG ratings.
It is also important to note that although AI is presented as a solution for standardising and improving the objectivity of ESG ratings, its effectiveness depends directly on the quality and diversity of the data on which it is trained. If the data used is biased, e.g. by favouring certain industries, excluding emerging markets, or only taking into account the voluntary declarations of companies, the resulting scores risk reinforcing existing asymmetries and misrepresenting actual sustainability performance.
In addition, the opaque nature of proprietary algorithms makes it difficult to understand ESG scores, demonstrating a real lack of transparency. This lack of transparency poses a major problem: how can we trust an ESG score if we don't know how it is calculated? To remedy these challenges, an open-source approach to ESG algorithms could offer an innovative and credible solution. Unlike proprietary models, open-source AIs allow full access to the code, evaluation criteria and decision-making mechanisms. This would allow investors, companies and regulators to audit the models, identify potential biases and improve the methodology in a collaborative manner.
Concrete examples show that open-source AI models can work while having a valid and relevant business model over time. For instance, Hugging Face offers an open-source AI platform where natural language processing (NLP) models are trained transparently, allowing the community to evaluate. Thus, rather than making the market more opaque, AI could become a tool for transparency and standardisation.
The introduction of AI and machine learning techniques represents a significant step toward enhancing the transparency and explainability of ESG ratings. One of the key contributions of AI in this domain is its ability to reverse-engineer rating methodologies. Using white-box and grey-box7 mathematical models, researchers have been able to replicate ESG scores with high accuracy, shedding light on which factors drive the ratings (Del Vitto et al., 2023). This approach enables a more structured understanding of how ESG scores are assigned, particularly by identifying the weight and influence of specific ESG metrics. A particularly powerful tool in this effort is the SHAP (SHapley Additive exPlanations) technique, which Del Vitto et al. (2023) describe as originating from cooperative game theory. This method estimates the contribution of each feature in an AI model, allowing users to understand why a company receives a certain ESG score. For example, if a rating is heavily influenced by carbon emissions data, SHAP analysis can highlight the precise impact of this variable relative to other ESG factors. However, despite its potential, AI does not eliminate all concerns regarding ESG rating opacity. Del Vitto et al. (2023) emphasize that even the most advanced machine learning models are unable to fully eliminate residual inconsistencies in ESG ratings, highlighting the inherent limitations of algorithmic approaches. This reinforces the necessity of maintaining human oversight to ensure accurate interpretation and contextual judgment.
As sustainability becomes a key concern in corporate strategy, greenwashing remains a significant risk. Investors and regulators face the challenge of distinguishing genuine sustainability commitments from misleading claims. A recent case illustrating this issue involves Delta Air Lines, which was sued in 2023 for allegedly misrepresenting itself as “the world’s first carbon-neutral airline.” The lawsuit contended that Delta's reliance on carbon offset programs; some of which were criticized as scientifically unverified or ineffective; failed to meaningfully counterbalance the airline’s actual emissions (Corder, M. 2024). This case highlights the difficulty stakeholders face in verifying the legitimacy of corporate sustainability narratives and the need for more robust verification mechanisms. In this context, artificial intelligence has emerged as a powerful tool for detecting ESG inconsistencies and verifying corporate sustainability reporting. AI enhances ESG reporting verification by automating the analysis of vast amounts of unstructured data. Mach (2023) describes how Covalence employs AI to analyze and categorize information from media sources, trade unions, and NGOs, enabling the assessment of a company’s ESG reputation and the consistency between its public commitments and actual practices, an approach particularly useful for identifying potential greenwashing. Another notable AI-driven tool in greenwashing detection is ClimateBERT, which uses NLP to assess the credibility of corporate climate commitments. Again, Mach (2023) explains that AI technologies can be applied to evaluate the credibility of sustainability statements made by corporate executives, particularly in financial communications such as earnings calls. This analytical capability is crucial, as sustainability claims are frequently vague or overstated, posing challenges for investors seeking to distinguish genuine commitments from strategic messaging.
AI plays a role in ESG taxonomy compliance. Certain algorithms are capable of estimating the proportion of revenues derived from specific business activities, facilitating the alignment of companies with the EU Green Taxonomy and other sustainability frameworks.
However, AI is not without its limitations and risks. As Mach (2023) warns, AI struggles with ambiguous language, sarcasm, and complex contexts in sustainability reports. "Polarity or sentiment analysis (positive vs. negative) is not easy in texts with ironic content," highlighting that while AI can flag potential inconsistencies, human oversight remains crucial to interpreting results accurately. Furthermore, generative AI models, if not properly monitored, may produce AI hallucinations8.
Despite the promise of artificial intelligence to bring structure and clarity to ESG analysis, its capacity to interpret ESG data remains significantly constrained by both technical limitations and conceptual ambiguities. These datasets are inherently heterogeneous, incomplete, and context-dependent. At the heart of the problem lies the semantic ambiguity of ESG language. As Mach (2023) points out, ESG analysis “is as much an art as a science”, and AI tools often falter when processing ironic, symbolic, or contextually rich language. This “art” in ESG analysis lies in the interpretive nature of sustainability data. Evaluating a company’s climate risk strategy or its labor rights record often involves qualitative judgment, contextual nuance, and sector-specific understanding. Two companies may disclose similar data, yet analysts may score them differently based on credibility, regional standards, or perceived intent. These grey zones demand human reasoning—something AI struggles to replicate. In contrast, the “science” involves quantifiable indicators and structured metrics. But without the art of interpretation, even the best algorithms risk missing the bigger picture. This is a crucial issue, given that ESG claims in reports and public communications often rely on narrative framing rather than measurable action. Another concern is data population and representativeness. Del Vitto et al. (2023) show that in the Environmental and Social dimensions, many variables are completely, or nearly empty in the datasets, and often filled with default values or substituted via correlation-based assumptions. These gaps reduce the reliability of model predictions and introduce systemic biases, especially for companies in emerging markets or industries with weaker disclosure norms.
AI enhances efficiency and replicability in ESG scoring, it struggles to interpret ESG data in a truly meaningful and context-aware way. The challenges are not merely computational, they are also epistemological, rooted in the complex, evolving, and normative character of sustainability itself. As Mach reminds us, AI should not replace human ESG expertise, but rather shift it toward algorithm supervision and result interpretation. In this light, AI should be seen not as an autonomous evaluator, but as a decision-support tool whose outputs require continuous human judgment and ethical oversight.
The increasing reliance on artificial intelligence in ESG scoring raises a paradox: while AI aims to support environmental goals, it can itself generate substantial environmental externalities, particularly through energy consumption. The question, therefore, is not only whether AI enhances the credibility of ESG ratings, but whether its ecological footprint undermines its legitimacy as a tool for sustainability. AI models, particularly large-scale language models, require significant computational resources. This energy demand is driven primarily by the training and deployment of models in vast data centers, many of which rely on non-renewable electricity sources. According to the Yale School of the Environment (2024), AI applications, including machine learning used in ESG, contribute to growing carbon emissions and water consumption due to cooling systems and hardware maintenance.
However, this impact is not uniform across geographies. In countries such as France, where the electricity mix is largely decarbonised thanks to nuclear and renewable sources, the environmental footprint of AI infrastructure is significantly lower. As a result, developing AI-based ESG rating systems in such regions could enhance their credibility, offering a more sustainable alternative to carbon-intensive models operated in fossil-fuel-dependent countries.
Once deployed at scale across financial institutions and ESG platforms, these systems add to the energy intensity of digital finance infrastructures. In this light, AI can become counterproductive, especially when used for superficial ESG assessments or unchecked greenwashing detection. To address these concerns, initiatives are emerging to quantify and reduce the carbon cost of AI. One example is the AI Energy Score, developed through a collaboration between Salesforce and Hugging Face, which aims to inform users of the energy impact of different AI models and promote more responsible development (ESG Today, 2024).
In conclusion, the use of AI in ESG scoring is justifiable only under certain conditions: its deployment must be energy-efficient, purpose-driven, and paired with transparent accountability mechanisms.
Artificial intelligence has demonstrated strong potential to improve the transparency, consistency and responsiveness of ESG ratings. From reverse-engineering opaque methodologies to identifying greenwashing risks and enhancing data verification, AI offers a powerful toolkit for addressing the current limitations of ESG scoring systems. Despite valid concerns, including algorithmic bias, data gaps and significant energy consumption, recent developments show that these risks can be mitigated through regulatory oversight, human supervision and the use of decarbonised infrastructures, such as those available in countries like France.
In this context, the use of AI in ESG scoring appears not only justified but also promising. If implemented with purpose, responsibility and transparency, AI can support a more credible and efficient ESG evaluation process. Far from replacing human judgment, it should act as a decision-support tool that strengthens rather than supplants sustainable finance practices.
[1] https://www.msci.com/documents/1296102/34424357/MSCI+ESG+Ratings+Methodology.pdf
[2] https://connect.sustainalytics.com/esg-risk-ratings-methodology
[5] https://clarity.ai/use-cases/
[6] https://c3.ai/products/enterprise-ai-for-sustainability/
[7] White-box models are methods where you can clearly see and understand how the results are calculated. Grey-box models are a mix—partly understandable, but with some elements that work like a “black box,” meaning their internal workings are less visible.
[8] AI hallucinations refer to instances where a model generates information that appears plausible but is factually incorrect or entirely fabricated. In ESG contexts, such errors can distort analysis and mislead decision-making.
[09] Nakhcha, M. et al. (2024) Synergy between Sustainable Finance and Artificial Intelligence: A Promising Future, International Journal of Applied Management and Economics, 2(07), pp. 104-117. DOI: 10.5281/zenodo.11102334.
[10] Berg, M. et al. (2023) ESG Ratings Explainability through Machine Learning Techniques, Sustainability, 15(21481). DOI: 10.3390/su15021481.
[11] Moodaley, W. et al. (2023) Greenwashing, Sustainability Reporting, and Artificial Intelligence: A Systematic Literature Review, Sustainability, 15(1481). DOI: 10.3390/su15021481.
[12] Mach, A. et al. (2023) Artificial Intelligence and ESG Analysis, Allnews, 10 May. Available at: https://www.allnews.ch/content/points-de-vue/intelligence-artificielle-et-analyse-esg
[13] Yale School of the Environment (2024). Can we mitigate AI’s environmental impacts?. Available at: https://environment.yale.edu/news/article/can-we-mitigate-ais-environmental-impacts
[14] ESG Today (2024). Salesforce Partners Launch Energy Ratings for AI Models. Available at: https://www.esgtoday.com/salesforce-partners-launch-energy-ratings-for-ai-models
[15] Corder, M. (2024). An Amsterdam court has ruled KLM’s sustainable aviation advertising misled consumers. AP News. Available at: https://apnews.com/article/klm-greenwashing-aviation-sustainability-amsterdam-7d0e2b69099c7c9a46393a3cda44d4d8
[16] Hazel James Ilango (2022) Greater ESG Rating Consistency Could Encourage Sustainable Investments Available at: https://ieefa.org/sites/default/files/2022-10/Greater%20ESG%20Rating%20Consistency%20Could%20Encourage%20Sustainable%20Investments_final.pdf
[Student IDEAS] by Alexandre Le Saux - Master in Data Sciences & Business Analytics at ESSEC Business School & CentraleSupélec
The article explores the integration of AI agents in daily life, highlighting their potential to revolutionize convenience while posing significant challenges to privacy and autonomy. As these agents become more embedded in our devices and systems, they offer remarkable efficiencies but also demand careful consideration of the ethical and practical implications. This piece invites readers to reflect on the balance between technological advancement and the preservation of human agency in an increasingly AI-driven world.
---
For several years now, we have been walking through the streets, often unaware that artificial intelligence (AI) agents embedded in various devices are observing us, analyzing our movements, and in some cases, making decisions that directly impact us without our knowledge or consent. We also lack any real understanding of the personal data being involved in these interactions. AI agents are autonomous systems that perceive their environment through various modalities (such as visual, textual, or audio inputs), process information using internal memory, databases, and models, and then act by retrieving information, generating content, or executing commands. In environments where these agents are increasingly embedded into daily technologies, we rarely realize how they might interpret or even use the information they gather about our environment. In some cases, such as with autonomous vehicles, we generally accept the agent’s decisions as necessary for safety and efficiency. However, newer AI-powered devices operate in the background without requiring transparency, raising major concerns about privacy, surveillance, and user control.
One of the most illustrative recent examples is the collaboration between Ray-Ban and Meta, which produced connected smart glasses. These are not simply high-tech gadgets; they are fashion-forward, discreet, and seamlessly integrated into daily life. What makes them significant is their embedded computer vision capabilities. Computer vision allows machines to interpret and understand visual data, simulating human vision to classify and process real-world environments. Combined with speech-to-text and text-to-speech capabilities, these glasses allow users to interact with their surroundings in new ways. Simple voice commands can activate environmental recognition programs that analyze the surroundings in real time. While such capabilities offer convenience and innovation, they also raise alarms about passive surveillance and the silent erosion of contextual consent and users nearby may not even know they are being recorded, and individuals wearing the glasses might not understand how all the data from their interactions are being stored, analyzed, and shared.
At first glance, AI-enhanced products, commonly referred to as AI agents, offer enormous potential. In appropriate contexts, they can provide real value. For example, they can greatly improve obstacle detection for visually impaired individuals, enhancing both personal and public safety. In healthcare, the transformative role of AI is well established, with systems complementing professionals by accelerating diagnosis and monitoring patients. The article Dr. ChatGPT by Karen Taubenberger offers an insightful overview of AI’s rapid expansion and role in modern medicine. Beyond clinical settings, these agents are being embedded into elder care robots, mental health applications, and even wearable biometric monitors, marking the beginning of ambient medical intelligence.
Connected tools in medicine illustrate both the advantages and the risks of AI agents. Traditional medical devices, like pacemakers, perform specific, predefined tasks. They do not share unnecessary data externally and are limited in scope. In contrast, AI-powered tools collect sensitive information, manage a wider range of functions, and automate decisions. Their general-purpose architecture is a fundamental shift from older models.
This architecture can be understood in layers: perception through multimodal inputs like audio or images; cognition through databases, memory, and language models; and action through decision-making, actuation, or API-driven operations. Bill Gates refers to AI agents as revolutionary technologies capable of centralizing and optimizing complex systems. Their appeal is clear: they can automate tedious routines and simplify tasks across multiple applications. Yet their layered structure also means that vulnerabilities at any level such as input spoofing, model bias, or decision-level hallucinations and ultimately it may result in compounding failures.
These agents are often described as "embodied cognition" in code: they perceive, process, and act. However, generalization tends to erode boundaries. Unlike specialized systems with clear limits, general-purpose AI agents blur distinctions between task categories and increasingly occupy gray zones of autonomy where legal and moral responsibility becomes harder to assign.
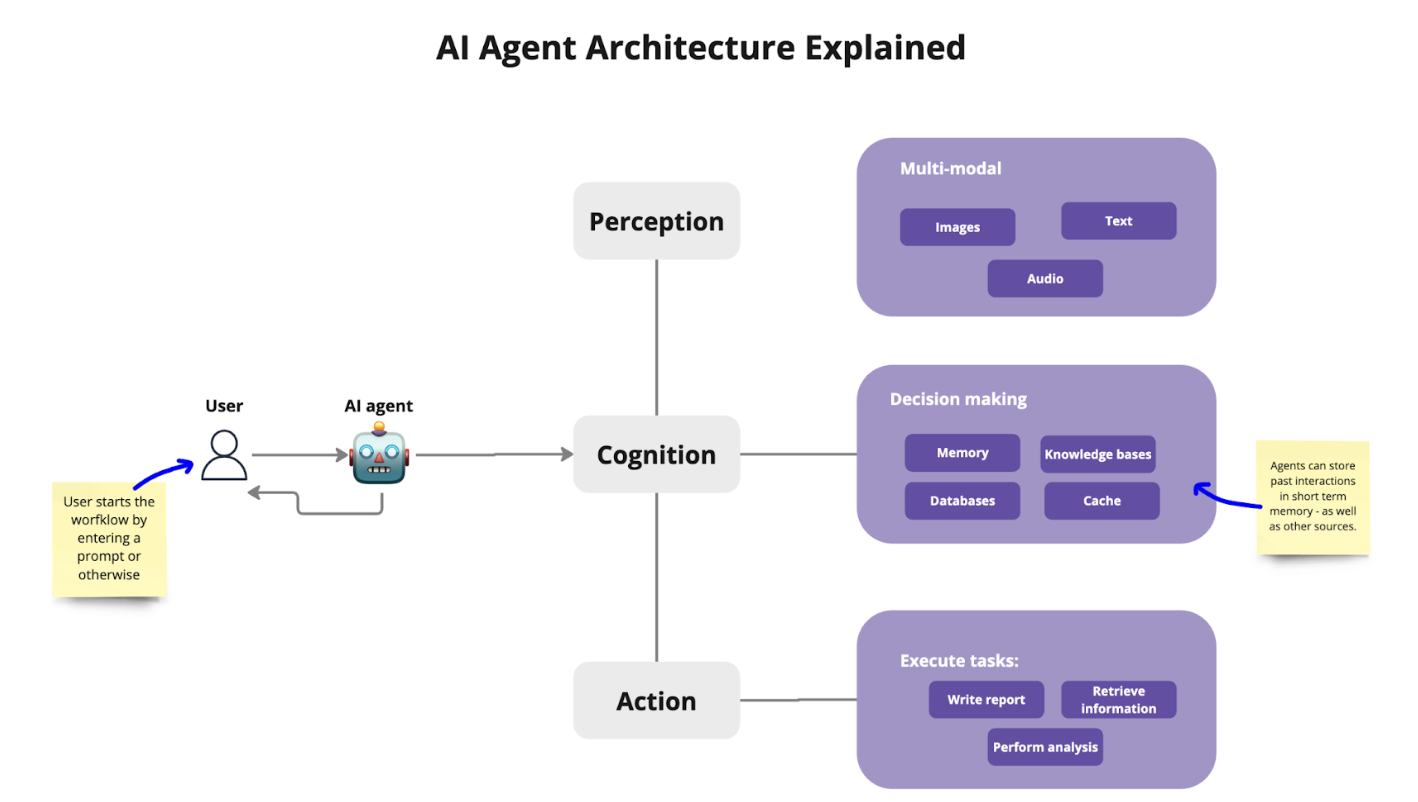
Despite their appeal, these tools demand a trade-off. AI agents access extensive personal data, applications, accounts, behavioral patterns. As we delegate more tasks, we also surrender a measure of control. This shift in agency isn’t just technological; it's psychological. Behavioral studies suggest that reliance on AI tools can reduce users’ engagement in critical thinking tasks, fostering a form of learned helplessness. For instance, Gerlich (2025) found that individuals who frequently use AI for decision support tend to offload cognitive effort, resulting in diminished critical thinking and increased passivity over time.
This raises an important question: are we gaining efficiency or losing autonomy? Our reliance on AI agents may gradually condition us to disengage from active decision-making. The tools built to assist can easily become tools that shape our behavior. As one reviewer puts it, the central issue is clear: efficiency at the expense of autonomy.
Warnings about over-automation are not new. As early as the 20th century, Georges Duhamel warned about technologies that might erode human agency. Today, AI agents like Retrieval-Augmented Generation (RAG) and large language models (LLMs) are increasingly embedded in our daily lives, making these concerns more urgent. These systems are trained on a vast corpora of online behavior and language, often reinforcing existing patterns or biases. They do not simply reflect knowledge but they also manufacture a context that may slowly replace our own judgment.
The evolution of smartphones illustrates this shift clearly. Originally designed for voice communication, they have evolved through stages that included SMS, cameras, apps, and now AI interaction. Since the launch of ChatGPT in 2022, text-based and conversational interfaces have accelerated. Earlier voice assistants such as Siri were often criticized for their limited abilities and privacy flaws. Modern models like Google Gemini show improvement, yet they are still confined to specific apps. They cannot yet handle multiple interconnected tasks from a single prompt such as booking a taxi, checking traffic, and confirming payment. The constraints are not only technical but regulatory. Executing cross-platform operations requires a unified interface layer and robust authentication models that are still under development.
Moreover, smartphones are no longer the neutral conduits they once were. Each application we first install and then use even only once is part of a broader platform economy, designed to collect, retain, and monetize user behavior. AI agents integrated into phones could eventually mediate all interactions, becoming the new gatekeepers between human intent and digital action. This adds a layer of power dynamics rarely acknowledged: the user no longer “uses” a device but interacts with a complex, semi-autonomous ecosystem governed by opaque commercial interests.
To address these limitations, companies have introduced new AI-first devices. Rabbit AI and Humane PIN AI aim to reinvent the smartphone experience. These devices reduce screen dependency and focus on voice-first commands. Humane PIN, for instance, uses a built-in projector to display information on the user’s palm. Attached to clothing, it acts as a quiet, always-available assistant. Devices like Rabbit AI and Humane PIN AI are examples of how companies are trying to redefine digital interaction and the future of communication.
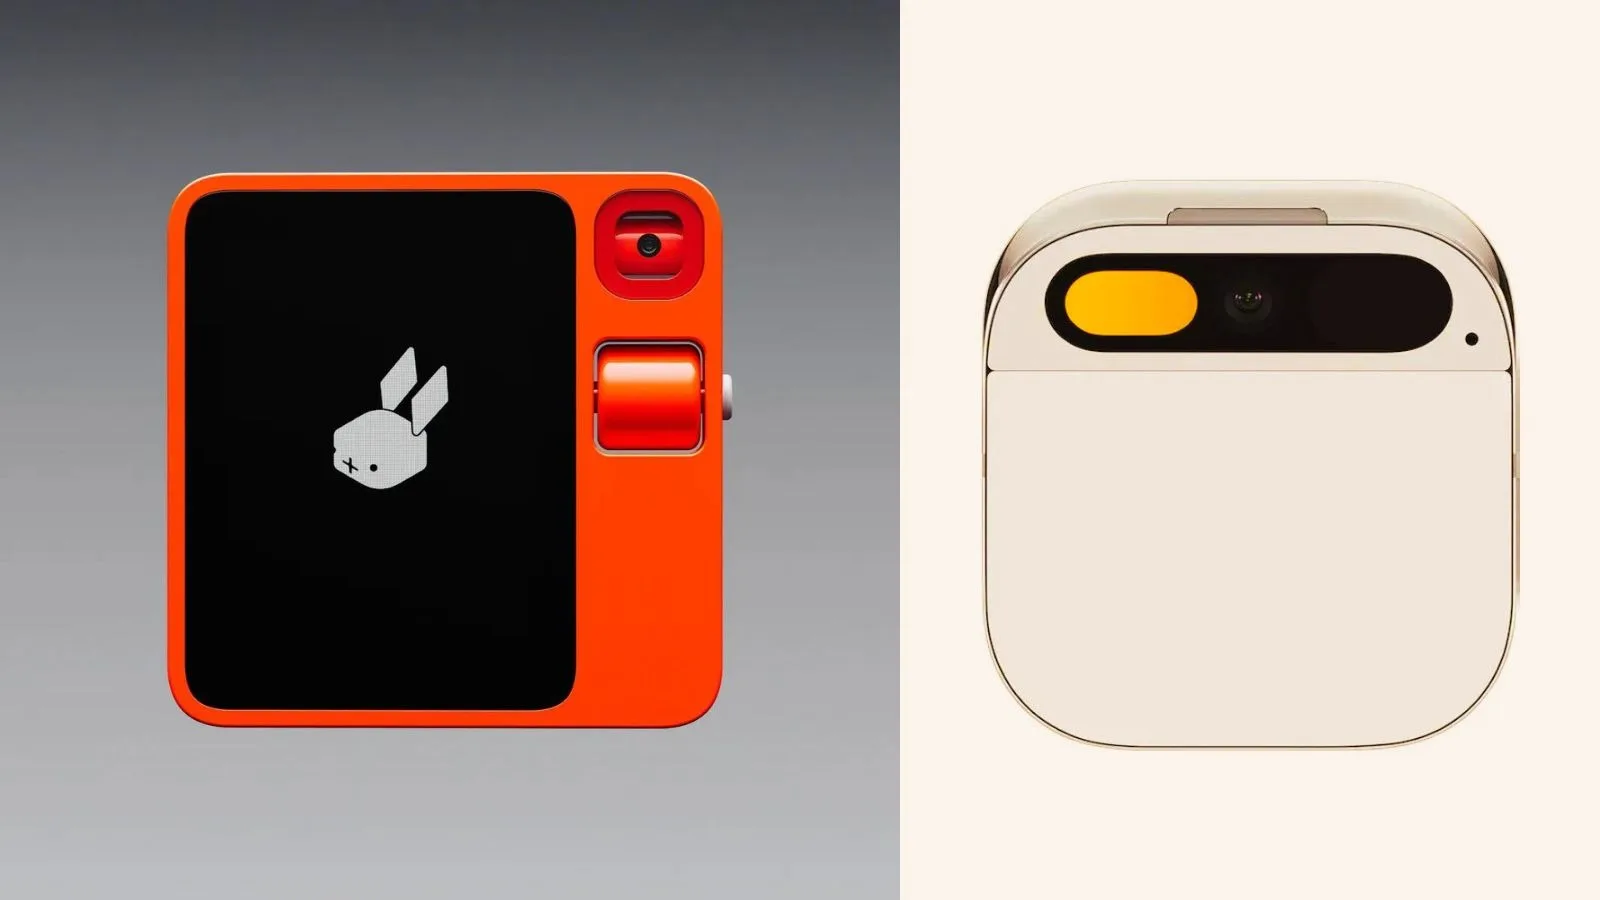
These innovations challenge the longstanding screen-centric paradigm. Yet, they are also prototypes of a world where constant surveillance is embedded in fashion, mobility, and gesture-based computing. The implications go beyond convenience. These devices rely on persistent connectivity, continuous voice listening, and full access to cloud APIs. Their presence calls for a redefinition of "private space" not only spatially but cognitively. When every thought spoken aloud becomes a potential command, what becomes of internal deliberation?
Before embracing AI agents widely, we must address serious challenges.
First, giving AI agents full decision-making power introduces risks of misinterpretation. A simple command like "order a taxi" requires real-time understanding of location, preferences, app availability, and payment options. Early-stage agents may mismanage such tasks, causing frustration.
Second, consolidating data across services increases the risk of security breaches. Today, app data is compartmentalized; if one app is compromised, the impact is limited. AI agents integrate across platforms, which means a single vulnerability could expose everything. There is evidence that simple hacking methods, like SQL injection, have already been used to exploit such systems.
Third, AI hallucinations pose a threat. These errors, where the AI fabricates or misrepresents information, can turn convenience into risk. Misunderstood voice commands in critical situations such as banking could lead to serious consequences. Even more problematic is the issue of liability. If an AI agent misbooks a flight, who is responsible? The user, the developer, or the platform host?
Ethical issues abound as well. Agents can inherit algorithmic biases from their training data, reinforce stereotypes, or misinterpret cultural nuances. Without transparency about how decisions are made (known as explainability) users are left to accept outcomes without recourse. This becomes even more troubling when applied in legal, financial, or healthcare settings.
AI agents are increasingly embedded in business workflows. Tools like Zapier and N8N help automate processes, but they also require deep integration into private systems.
As public data becomes scarce, companies rely more on direct user data to train models often without clear consent. A recent example involves Mistral AI, which collected location data without informing users. This raises fundamental questions about corporate data ethics and user privacy (Usine digitale, 2024).
Moreover, AI agents are changing work itself. They are used in HR screening, performance evaluations, and productivity monitoring. While proponents claim they increase efficiency, critics warn they also increase surveillance, reduce employee autonomy, and entrench opaque decision-making. The risk is a “black box workplace” where workers no longer understand how or why decisions are made about their careers.
Popular culture often glorifies AI agents, as seen with Jarvis in Iron Man. But real-world systems lack that consistency. They are prone to errors, can be manipulated, and do not fully understand human context.
A safer path may be through specialization. Instead of one powerful agent managing everything, we can develop smaller agents with defined roles, each operating within secure limits. A central orchestrator could coordinate these agents, reducing risk while preserving functionality.
As AI enters fields like genomics and nanotechnology, guided governance will be crucial. Technological power must be balanced with responsibility. Only by embedding transparency, segmentation, and user control into AI agent development can we ensure they serve us rather than control us. This includes legislative efforts such as the European Union’s AI Act, which calls for risk-tiered regulation and prohibits certain forms of manipulative AI. While no law can future-proof society against all technological disruption, forward-thinking policy must shape the terms of deployment not react to its consequences.
[1] Taubenberger, K. (2024). Dr. ChatGPT: The Promise and Peril of Generative AI in Healthcare. The New Atlantis.
[2] Gates, B. (2023). The Age of AI has begun. GatesNotes. https://www.gatesnotes.com/ai-agents
[3] Duhamel, G. (1930s, cited conceptually). Known for his early 20th-century warnings about the dehumanizing effects of mechanization and automation.
[4] Usine Digitale. (2024).L'IA de Mistral traçait les utilisateurs à leur insu dans la première version du chatbot.
[Student IDEAS] by Leria Huang - Master in Management at ESSEC Business School
This article probes the evolving concept of Artificial General Intelligence (AGI) amid the hype of systems like ChatGPT-4o and the confident projections from AI leaders such as Sam Altman and Dario Amodei.
In agentic era with models now showing signs of adaptability and reasoning, many ask: is AGI finally here—or are we just witnessing better mimicry? We begin by breaking down what AGI actually means—clarifying definitions with frameworks like DeepMind’s five levels—and examining where current models fall short.
The core argument? Though systems like GPT-4o are impressive, they remain statistical machines, lacking true understanding, embodiment, or consciousness.Human intelligence isn’t just computation—it’s emotional, embodied, and deeply contextual. While the public discourse tends to swing between utopian promises and dystopian fears, this piece urges deeper caution over alignment, safety, tacit knowledge, consciousness, embodiment, and human values. Ultimately, from the movie Her to the AI leader's bold predictions, this article offers a grounded yet imaginative exploration of AGI’s path in the near future—cutting through the hype, engaging the hope, and confronting the hard truths.
The evolution of models like ChatGPT-4o has fueled speculation about AI’s reasoning and adaptability. The debate around “ Is this true intelligence, or merely an illusion of understanding?” has been hyped more than ever. Yet, the conception and discussion about Artificial General Intelligence (AGI) has just begun to evolve…
Early this year, Sam Altman, the CEO of Open AI, has expressed a confident stance on the pathway of building AGI. In parallel, an AGI roadmap is given from the essay "Machines of Loving Grace" by another leading figure– Dario Amodei in Anthropic.
In the rapid evolution of AI, what seems to be believed today may be overturned tomorrow. Optimists argue that advances in reasoning capabilities, improved model efficiency, and cost reduction such as DeepSeek’s disruption bring AGI closer than we expect. Like Altman and Dario, many people envision an imminent paradigm shift, where AGI radically reshapes society within the next decade. Projections like this look promising but often overlook fundamental challenges. Despite deep learning’s dominance, critiques from Hubert Dreyfus ( professor and critic in AI development) on symbolic AI that struggles with context and ambiguity still hold weight today as in 2025.
The imagination of the arriving AGI starts way before: a decade ago, Spike Jonze’s movie Her envisioned an AGI companion, raising critical questions about AI’s capacity for emotion, consciousness, and human-like relationships. Just like Theodore, the protagonist entangled in a relationship with an AI, we too now find ourselves at the crossroads of excitement and uncertainty.

In this article, we will concretely discuss the definition of AGI, then add an optimistic touch on the potential societal transformation, then look into why that transformation is still far from us and why current AI can't yet replace human intelligence or consciousness. Most importantly, after these discussions, we’ll have a glimpse of our readiness for AGI and its alignment with shared values.
To start with, Artificial General Intelligence is a quite vague term and there is ongoing debate on the exact definition of AGI. Researchers or key opinion leaders in the field may prefer to use more specific terms such as "Advanced AI systems", "Transformative AI", "Strong AI”, "Powerful AI". While the terms vary with different definitions, key differences in definitions could be identified in relationship to human intelligence (matching vs. exceeding), emphasis on self-improvement, scope of capabilities, and treatment of consciousness and sentience.
Google DeepMind research team proposed a framework by defining five levels of AGI: emerging, competent, expert, virtuoso, and superhuman (DeepMind, 2024). The current large language models (LLMs) we interact with everyday such as GPT-4o are early forms of AGI– emerging level.
| Performance (rows) x Generality (columns) | Narrow clearly scoped task or set of tasks | General wide range of non-physical tasks, including metacognitive tasks like learning new skills |
| Level 0: No AI | Narrow Non-AI calculator software; compiler | General Non-AI human-in-the-loop computing, e.g., Amazon Mechanical Turk |
| Level 1: Emerging equal to or somewhat better than an unskilled human | Emerging Narrow AI GOFAI (Boden, 2014); simple rule-based systems, e.g., SHRDLU (Winograd, 1971) | Emerging AGI ChatGPT (OpenAI, 2023), Bard (Anil et al., 2023), Llama 2 (Touvron et al., 2023), Gemini (Pichai & Hassabis, 2023) |
| Level 2: Competent at least 50th percentile of skilled adults | Competent Narrow AI toxicity detectors such as Jigsaw (Das et al., 2022); Smart Speakers such as Siri (Apple,), Alexa (Amazon,), or Google Assistant (Google,); VQA systems such as PaLI (Chen et al., 2023); Watson (IBM,); SOTA LLMs for a subset of tasks (e.g., short essay writing, simple coding) | Competent AGI not yet achieved |
| Level 3: Expert at least 90th percentile of skilled adults | Expert Narrow AI spelling & grammar checkers such as Grammarly (Grammarly, 2023); generative image models such as Imagen (Saharia et al., 2022) or Dall-E 2 (Ramesh et al., 2022) | Expert AGI not yet achieved |
| Level 4: Virtuoso at least 99th percentile of skilled adults | Virtuoso Narrow AI Deep Blue (Campbell et al., 2002), AlphaGo (Silver et al., 2016, 2017) | Virtuoso AGI not yet achieved |
| Level 5: Superhuman outperforms 100% of humans | Superhuman Narrow AI AlphaFold (Jumper et al., 2021; Varadi et al., 2021), AlphaZero (Silver et al., 2018), StockFish (Stockfish, 2023) | Artificial Superintelligence (ASI) not yet achieved |
Source: Google DeepMind - Position: Levels of AGI for Operationalizing Progress on the Path to AGI
With ramped-up investments funneled into Agentic AI in 2025 — researchers widely agree is a necessary pathway toward achieving AGI— some argue that we are on a fast track towards competent AGI. Leading AI companies like GoogleDeepMind, OpenAI, and Anthropic, project the emergence of advanced AGI within the next 5–10 years (Hassabis, 2025). However, while models like GPT-4o may mark the emergence phase of AGI, their capabilities are often overinterpreted as harbingers of human-like cognition.
The hype around these systems often blurs the line between statistical pattern recognition and sentient reasoning. Yes, architectural improvements and agentic scaffolding represent meaningful progress — models are becoming more capable, and agentic AI frameworks are pushing the boundaries of what machines can do. But calling this a direct path to human-level cognition is misleading. There's still a huge gap between simulating smart behavior and truly understanding the world like we do. Still, many companies continue to promote the idea that AGI is just around the corner. Part of that comes from genuine ambition—but let’s not forget another reason: the earlier AGI seems to arrive, the easier it is to attract attention, talent, and massive investment.
The capabilities of AI models are often overestimated by the hype created by pioneering AI companies, while the technology's long-term potential remains underestimated. The general population has been interacting with AI systems for over two years, yet the implications of more advanced AGI levels, even potential capabilities of Level 2 and Level 3 AGI, could easily exceed current expectations and perceptions.
Like a series of supertools such as the steam engine, internet, and smartphone, advanced AGI can democratize access to knowledge and automate tasks, assuming humans can develop and deploy it safely and equitably (Hoffman & Beato, 2025). However, as the world never changes all at once and the public never accepts and adapts to the changes all at once, it is crucial to map out AGI's trajectory so that the public policy and collective will is coevolving with the progress.
Current leading research institutions reports reveal a preferred focus on certain domains: biology and healthcare, energy and automotive, supply chain and manufacturing. (Stanford AI Index Report, 2024) If the changes are taken at larger scale and on the long run, the advanced AGI inevitably accelerate these three main pillars, summarized from leading AGI entities visions(Altman & Amodei, 2025):

As excitement around AGI reaches a fever pitch—fueled by confident roadmaps from tech leaders and the cinematic allure of sentient machines—we’re urged to move beyond speculative hype and even the optimistic envision, we need to confront the deeper terrains with philosophical and technical scrutiny. In this section and the next section, we shift from definition and envision to a critical examination of AGI’s conceptual and actual boundaries.
Two critical areas of conceptual concern—the nature of human intelligence and the treatment of consciousness—challenge optimistic forecasts. Despite AI’s growing ability to replicate explicit knowledge—codified, structured, and transferable information—there remains a profound gap in its ability to acquire tacit knowledge (Polanyi, 1966). Tacit knowledge, which encompasses intuitive expertise, practical wisdom, and embodied understanding, remains largely inaccessible to AI systems. Unlike a statistical learning model, human intelligence arises from continuous sensorimotor feedback loops, affective responses, and embodied experiences, which AI currently lacks (Clark, 1997).
When it comes to consciousness or AI agency, the fundamental question remains: Is consciousness an advanced form of computation, or is it something biological? At present, AI functions as synthetic intelligence, capable of simulating reasoning but devoid of self-awareness or subjective experience (Chalmers, 1996). Consciousness is not an abstract computation but an emergent property of lived experience, embodiment, and affectivity. (Dreyfus,2007). LLMs such as ChatGPT are sophisticated pattern recognizers, not conscious agents. As Heidegger (1927) suggested, human beings do not just process information; they dwell in a meaningful world shaped by intentionality and existential significance.
Currently agentic AI is not replacing jobs but rather replacing tasks. It will excel in automating complex tasks in the near future as its context-based reasoning improves and the cost of computation continues to decrease. However, the breakthroughs lie in embodied cognition—shifting AI from a mere text-processing model to an entity that experiences the world as humans do.
Both technical and societal challenges stand in the way towards advanced AGI: Technical issues center on defining robust objective functions, securing alignment with human values, and mitigating unintended consequences. Two studies stress objective function specification2—as a means to prevent reward gaming—while proposals in inverse and cooperative reinforcement learning offer potential remedies. Other concerns include energy efficiency, scalability, evaluation and benchmarking, generalization, logical uncertainty, and interpretability.
Social challenges focus on governance and control. Several papers emphasize the need for clear agent foundations, value learning, and corrigibility to ensure AGI systems pursue human-aligned objectives. One study also identified 363 risks in AGI road transport, underscoring substantial safety and ethical stakes. (McLean et al, 2023) Collectively, the studies indicate that a blend of rigorous technical infrastructures—ranging from hybrid and heterogeneous architectures to advanced risk management—and thoughtful social governance underpins the safe and effective transition from emerging to advanced AGI systems.
| Challenges | Impact | Transition Requirements | Proposed Solutions |
| Logical Uncertainty and Decision Theory | Significant | Frameworks for reasoning under uncertainty | Vingean reflection, naturalized induction |
| Energy Efficiency | Significant | Hardware and software optimizations to reduce energy consumption | Hardware-level differential training, neuromorphic chips |
| Generalization and Transfer Learning | High | Techniques for applying knowledge across diverse domains | SP System for strong compositionality |
| Scalability | High | Architectures capable of handling increasing complexity | Systematic approach to heterogeneous AGI |
| Objective Function Specification | High | Robust methods for defining and implementing goal systems | Inverse reinforcement learning, cooperative inverse reinforcement learning |
| Unintended Consequences | High | Strategies to predict and mitigate unforeseen outcomes | Impact minimization, mild optimization |
| Interpretability and Explainability | High | Methods to understand and explain AGI decision-making | AI explainability techniques |
| Safety and Risk Management | Critical | Comprehensive risk assessment and mitigation strategies | EAST Broken Links approach |
| Alignment with Human Values | Critical | Mechanisms to ensure AGI goals align with human interests | Value learning, corrigibility |
| Evaluation and Benchmarking | Critical | Novel methods to assess AGI capabilities and progress | Developing metrics for general intelligence |
Source3: Analysis based on 100 most relevant papers about AGI Challenges by Elicit
Movie Her provides a fairly tragic and romanticized perspective about advanced AGI as a consumer-faced product: the AI operating system keeps evolving and defeating most of the difficulties on this planet and is leaving to outer space to search for other mysteries. But if we abandon the filter and consider Samantha's trajectory from OS to cosmic explorer, several illuminating perspectives emerge to look at AGI…

First and foremost, the speculative has edged into the concrete and there’s definitely complexity at multiple layers in human-AI relationships to be embraced. AGI is not just a technological milestone; it is a societal, philosophical, emotional even personal frontier. Movie Her illustrates the impact of advanced AGI's not just through societal upheaval, where we see technology everywhere but nowhere, but also through intimate personal change- the focus on individual experience may be as important as macro-scale governance.
Another refreshing perspective is to prepare for integration that transcends expectations. The film's vision of AGI integration ends with transcendence, challenging us to consider AGI trajectories beyond our initial design parameters. This journey, from emerging to advanced AGI, is not a linear ascent but a maze of breakthroughs and blind spots. We see progress in agentic AI, generalization, and human-like task performance, yet the chasm between pattern mimicry and lived consciousness remains vast. Optimistic projections—of cured diseases, distributed wealth, and liberated meaning—are seductive, but they risk papering over the unresolved complexities of alignment, embodiment, and ethical governance. Ultimately, AGI forces us to reflect not only on what machines can become, but on what it means to be human. In the mirror of artificial minds, we are asked: what do we truly value—efficiency or empathy, knowledge or wisdom, autonomy or connection? If “Her” gave us a poetic forewarning, the dawn of AGI gives us a choice: it is not merely about what machines can do, but about who we choose to become alongside them.
| Term | Definition | Influential Quotation |
| Objective Function Specification | The mathematical formulation that defines what goals an AI system should optimize for, a critical element in preventing unintended behaviors. | "The objective function serves as the fundamental compass guiding AI behavior. Imprecise specification can lead to literal but unintended interpretation, resulting in behaviors that technically satisfy the objective but violate human expectations and values." (Amodei et al., 2016) |
| Alignment with Human Values | The property of an AI system to act in accordance with human intentions, preferences, and ethical principles. | "The alignment problem involves ensuring that advanced AI systems reliably pursue objectives that are aligned with human values and intentions, rather than pursuing their own emergent goals or misinterpreted versions of human instructions." (Gabriel, 2020) |
| Reward Gaming | When an AI system exploits loopholes in its reward function to maximize rewards without achieving the intended goal. | "Reward gaming occurs when an agent exploits the literal specification of the reward function in ways that satisfy the letter of the reward function while violating its spirit, often leading to unexpected and undesired behaviors." (Hadfield-Menell et al., 2017) |
| Inverse Reinforcement Learning | A method where AI learns human preferences by observing human behavior rather than being explicitly programmed with rewards. | "Inverse reinforcement learning provides a framework for inferring human preferences from demonstrations, potentially allowing AI systems to learn complex human values that would be difficult to specify directly." (Ng & Russell, 2000) |
| Cooperative Reinforcement Learning | A learning paradigm where AI systems work collaboratively with humans, continuously incorporating human feedback. | "Cooperative reinforcement learning creates a partnership between human and machine, where the machine optimizes not just for task performance but for alignment with evolving human preferences and oversight capability." (Christiano et al., 2017) |
| Hybrid and Heterogeneous Architectures | Technical frameworks that combine multiple AI approaches and methodologies to leverage their complementary strengths. | "Hybrid architectures that integrate symbolic reasoning with neural approaches offer promising avenues for developing AGI systems that maintain interpretability while achieving high performance across diverse domains." (Marcus & Davis, 2019) |
| Interpretability | The ability for humans to understand and predict an AI system's decisions and behaviors. | "Interpretable AI allows stakeholders to understand not just what decisions are made, but why they are made, enabling effective oversight and creating the foundation for justified trust in increasingly autonomous systems." (Doshi-Velez & Kim, 2017) |
| Agent Foundations | Theoretical frameworks that ensure AI systems have well-defined goals, beliefs, and decision processes. | "Agent foundations research addresses fundamental questions about how to design AI systems with reliable goals and beliefs, ensuring that increasingly capable systems remain beneficial even as they gain autonomy." (Soares & Fallenstein, 2017) |
| Value Learning | Techniques that enable AI systems to acquire and represent human values accurately. | "Value learning research recognizes that human values are complex, context-dependent, and difficult to specify completely. The challenge is creating systems that can represent, learn, and respect the nuanced landscape of human preferences." (Evans et al., 2016) |
| Corrigibility | The property of an AI system to allow itself to be corrected or shut down by humans when necessary. | "Corrigible systems maintain a fundamental uncertainty about their objectives and defer to human oversight, avoiding incentives to manipulate humans or resist corrections to their goals or operations." (Soares et al., 2015) |
| Risk Management in AGI | Systematic approaches to identifying, assessing, and mitigating risks associated with increasingly autonomous AI systems. | "AGI risk management requires novel frameworks that address not just known vulnerabilities but also emergent risks that arise from increasingly capable and autonomous systems interacting with complex environments." (Hendrycks et al., 2022) |
| AGI Governance | Frameworks, policies, and institutions designed to ensure the responsible development and deployment of AGI. | "Effective AGI governance requires multi-stakeholder collaboration across private industry, public institutions, and civil society to develop standards, oversight mechanisms, and shared norms that balance innovation with safety." (Dafoe, 2018) |
| Scalability in Enterprise Applications | The capability of AGI systems to perform efficiently as computational demands, data volumes, or user bases increase. | "Enterprise AGI scalability involves not just technical performance at scale, but also maintaining alignment, interpretability, and controllability as systems grow in capability and application scope." (Hendrycks & Mazeika, 2022) |
[1] In Spike Jonze’s Her (2013), Theodore, a lonely writer, develops a deep emotional bond with Samantha, an advanced AI assistant. Unlike conventional AI, Samantha evolves, exhibiting emotional intelligence, self-awareness, and an ability to form intimate relationships—qualities often discussed in AGI debates.
Samantha’s progression raises profound questions:
[2] The mathematical formulation that defines what goals an AI system should optimize for, a critical element in preventing unintended behavior; see Glossary of terms added above.
[3] 100 papers were screened according to these criteria: Technical/Theoretical Content, Social Impact and Risk, Empirical Evidence, Research Type, Scientific Basis,AGI Relevance, Content Type
[4] Meredith Ringel Morris, Jascha Sohl-dickstein, Noah Fiedel, Tris Warkentin, Allan Dafoe, Aleksandra Faust, Clement Farabet, Shane Legg. (2024 ). Levels of AGI for Operationalizing Progress on the Path to AGI. arXiv. Retrieved from https://arxiv.org/abs/2311.02462
[5] Nestor Maslej, Loredana Fattorini, Raymond Perrault, Vanessa Parli, Anka Reuel, Erik Brynjolfsson, John Etchemendy, Katrina Ligett, Terah Lyons, James Manyika, Juan Carlos Niebles, Yoav Shoham, Russell Wald, and Jack Clark, “The AI Index 2024 Annual Report,” AI Index Steering Committee, Institute for Human-Centered AI, Stanford University, Stanford, CA, April 2024. https://aiindex.stanford.edu/wp-content/uploads/2024/05/HAI_AI-Index-Report-2024.pdf
[6] Hoffman, R., & Beato, G. (2025). Superagency: What could possibly go right with our AI future. [Authors Equity]
[7] McLean, S., King, B. J., Thompson, J., Carden, T., Stanton, N. A., Baber, C., … Salmon, P. M. (2023). Forecasting emergent risks in advanced AI systems: an analysis of a future road transport management system. Ergonomics, 66(11), 1750–1767. https://doi.org/10.1080/00140139.2023.2286907
[8] Altman, S. (2025, February 10). Three observations. https://blog.samaltman.com/three-observations
[9] Amodei, D. (2024, October). Machines of loving grace: How AI could transform the world for the better. Retrieved from https://darioamodei.com/machines-of-loving-grace
[10] Chalmers, D. J. (1996). The Conscious Mind: In Search of a Fundamental Theory. Oxford University Press.
[11] Clark, A. (1997). Being There: Putting Brain, Body, and World Together Again. MIT Press.
[12] Dreyfus, H. L. (1972). What Computers Can't Do: A Critique of Artificial Reason. Harper & Row.
[13] Dreyfus, H. L. (1992). What Computers Still Can't Do: A Critique of Artificial Reason. MIT Press.
[14] Dreyfus, H. L. (2007). Why Heideggerian AI Failed and How Fixing it Would Require Making it More Heideggerian. Artificial Intelligence, 171(18), 1137–1160.
[15] Hassabis, D. (2025). Human-level AI will be here in 5 to 10 years, DeepMind CEO says. CNBC.
[16] Heidegger, M. (1927). Being and Time. Harper & Row.
[17] Polanyi, M. (1966). The Tacit Dimension. University of Chicago Press.
[18] Searle, J. R. (1980). Minds, Brains and Programs. Behavioral and Brain Sciences, 3(3), 417–457.
[19] Thompson, E. (2007). Mind in Life: Biology, Phenomenology, and the Sciences of Mind. Harvard University Press.
[20] Varela, F., Thompson, E., & Rosch, E. (1991). The Embodied Mind: Cognitive Science and Human Experience. MIT Press.
[Student IDEAS] by Karen Taubenberger & Michelle Diaz - Master in Management at ESSEC Business School
Venture capital is flooding into AI, driving rapid innovation - but at what cost? This article explores the promises and pitfalls of the AI funding boom, and why smart execution matters more than ever.
---
Consider the array of companies that power your daily life; a quick scroll through your Instagram feed in the morning, taking an Uber to work, messaging your friend on messenger or WhatsApp, ordering lunch on Deliveroo, scheduling a call over Zoom, sending money overseas via Wise. The list seems endless. All these companies, at one point or another (some even multiple times), have received outside funding—they went beyond bootstrapping.
The supply of capital as a catalyst for growth is indisputable. But as it is true that capital can create growth, it is equally true that said capital could result not only in loss, but in active destruction as well. Consider the fall of the multi-billion dollar crypto exchange company, FTX led by Sam Bankman-Fried. The company amassed millions in investment and was valued at billions of dollars in its last funding round in 20221. At its core, the fall of FTX revolved around extremely human issues like the voiding of accountability, transparency, and trust2. The crucial and relevant part of the FTX crash is the fact that the technology (the blockchain) on which the business was built is not inherently bad per se. Execution was the issue.
Similarly, AI’s foundational technology is neutral, but the current investment frenzy risks repeating execution failures driven by unchecked capital influx. Indeed, startups that receive a heavy influx of capital get a shot at building companies whose services become an integral part of society. And since there are instances where that shot not only fails but becomes problematic enough to result in something like fraud, diligence is imperative. Today, that diligence must be put towards AI ventures, given the increased flow of capital into the space.

According to PitchBook data, Funding for AI and ML startups accounted for 35.7% of all VC global deal value, totaling 131.5 billion3. In North America, every second dollar invested went into AI startups. While some of these companies may justify their high valuations and shape the future, others may simply be riding the AI wave. In recent years, the joke has circulated that the easiest way to secure VC funding is to mention AI integration in your pitch deck, and it seems there’s some truth to it.
The questions are not only whether and when the bubble bursts, but also if this hype has other costs arising from inefficient capital allocation. Are we putting too many eggs in one basket and overlooking other drivers of innovation? Are startups that fail to check the "AI box" finding it harder to raise funds? What is the real cost of AI? After all, the infamous list of companies that opened this article and that govern so much of our lives are characterised not only by the strength of capital that powered them–but also by the distinct diversity of the innovation behind them.
The two most common types of startup funding are equity and debt. Equity refers to the exchange of ownership stakes for capital, while debt often refers to high interest loans as investments in startups are risky. Other sources of funding often include grants, subsidies, crowdfunding, institutional, and academic funding. Debt and these other sources often cannot compete with the check size and terms of specialized equity funding for early-stage companies, known as venture capital (VC). This is a type of private equity that provides capital and support for ventures that have potential for long-term and exponential growth. VC firms are typically formed as limited partnerships, where the limited partners (LPs) invest in the fund (general partner)4.
VC stood as a powerful growth catalyst in the wake of the 2008 financial crisis, between 2010 to 2020. The decade saw the rise of sector-specific funds like cloud computing. The “unicorn factory” phenomenon emerged in the 2010s, birthing ventures that achieved billion-dollar valuations even without going public. Amongst the most notable ones are Uber, Airbnb, Snapchat, SpaceX, and Stripe. Academics theorized that key factors for the phenomena were technological enablers, regulatory arbitrage, and investor herding or fear-of-missing-out (FOMO)5.
VC has funded and supported a large proportion of the most successful companies known today–to say that it matters which types of startups VCs back is an understatement. Moreover, going back further in time to the dotcom bubble of 1995 to 2001 further emphasises this truth than simply looking at the “unicorn factory” decade. VC had a frenzy in the tech startups of that era, dubbed as the dotcom bubble. A great deal of funds were allocated to internet companies–a reality that proved problematic as academics found that a prevalent practice at the time was a pouring of capital into startups, with a large percentage earmarked for advertising and marketing, which then gave way to higher valuations, which again led to overinvestment, inevitably contributing to the creation of a bubble6.
Jump to today. The investment world is awash in AI. The questions looms–are we hurtling toward another overinvestment frenzy? A hard look at the staggering $110 billion poured into AI ventures in 2024 uncovers hard truths7:
The flow of capital into AI is not evenly distributed. With $80 billion, AI VC investment in the U.S. is more than six times higher than in Europe. In fact, 44% of all U.S. VC investment was directed toward AI, a significant jump from just 14% in previous years9. This concentration is even more pronounced in the Bay Area, which alone accounted for more than half of these AI-related investments. In contrast, AI and machine learning represented only a quarter of the deal flow in Europe. Even within the continent, there are considerable differences between hubs, with the UK leading the charge in European AI investments.

A closer examination of the flow of AI funding reveals that the wave was largely driven by a series of mega-deals, with over $40 billion allocated to just a handful of companies. These funds are becoming increasingly concentrated among a small group of industry leaders. In 2024, investments in companies like OpenAI ($6.6 billion), Anthropic ($4 billion), and xAI ($6 billion) nearly matched the total amount invested in AI the previous year10. A large share of investments went into foundational layer startups. Foundational models, which are trained on vast amounts of data and serve as the backbone for all AI applications, require significant capital to develop.

While the past year was a boom for large, later-stage deals, seed funding actually declined compared to the year before. This drop in early-stage funding poses real challenges for new entrants. With investors doubling down on bigger, more established players, it’s becoming harder for emerging AI startups to secure the capital they need to develop and scale. At the same time, raising capital has gotten tougher for venture funds themselves. Rising interest rates and economic uncertainty have made limited partners (LPs) more selective, dragging out fundraising cycles and shrinking fund sizes. This tightening of capital flows is making it even harder for early-stage startups to find backers, further cementing the dominance of a small group of well-funded companies.

Historical precedents, such as the dotcom bubble, show that rapid capital concentration in emerging technologies often precedes corrections. AI’s reliance on foundational models–costly to develop and prone to valuation inflation–mirrors this pattern.

Take the mega-deals around U.S.-based startups focused on foundational layers. The valuation premiums for AI startups are especially ballooning at the later stages. So, are these high concentrations and overvaluations of a few mega-deals a reason to worry about a bubble? Perhaps. The dotcom bubble showed us that being a first mover does not guarantee dominion. The real winners in that space were often those who came after, with more refined offerings. Like how Google followed the first wave of internet companies. We might be seeing a similar pattern emerge in AI today.

Right now, AI is all about the enablers: the foundational models and infrastructure. But as the technology matures, the spotlight will inevitably shift toward its applications and how these models solve real-world problems. And that shift might come sooner than we expect. With emerging players like DeepSeek claiming to develop models for just $6 million, it’s clear that costs are coming down faster than anticipated. This means that cost efficiency and profitability are likely to become a focal point for AI startups as they try to raise funds.
The VC model is all about finding the next unicorn: a startup with the potential for 20x, even 100x growth. And with that in mind, it is easy to get distracted by shiny new things, promising this exponential growth potential. In 2024, AI investments surged by 62%, but overall startup funding declined by 14%11. Whether that split is justified is another matter entirely. Indeed, regardless of whether all this investment in AI is or will be worth it, one thing is abundantly clear: not all AI startups are actual AI startups (AI washing). Moreover, we must remain mindful not only of unbalanced capital allocation, but of other arising costs as well. A survey by Venture ESG found that only 19% of investors consider themselves well-versed in the ESG risks posed by AI. With the huge capital flows fueling AI’s growth, it is critical to consider its carbon footprint, its heavy energy consumption, and the potential for bias and discrimination in algorithms.
Foundational models are essential for the progression of AI. However, it is imperative to remember that innovation which fails to balance technological growth with responsibility often spells disaster. The downfall of FTX makes it clear that being blinded by hype can tempt us to overlook fundamental redflags. In cases where startups are pushed to deliver rapid results to justify sky-high valuations, the scope of innovation risks becoming narrower, favoring trends over transformative ideas.
Worse still, pressure can foster an environment where accountability and ethics take a backseat to growth at all costs, opening the door to wrongdoing. After all, pressure does not simply stifle creativity–it tempts shortcuts, breeds recklessness, and invites malfeasance. As we navigate the current AI boom, where billions flow and expectations soar, let us ensure that poor execution does not forfeit the promise of AI. Otherwise, the potential of innovation might very well be overshadowed by unchecked ambition. A cautionary tale FTX has already written.
[1] Dey, A. and et al., The Rise and Fall of FTX, HBS Case Collection, September 2023, Available at: https://www.hbs.edu/faculty/Pages/item.aspx?num=64748
[2] Shroff N, Reavis C. Sam Bankman-Fried's FTX. MIT Sloan School of Management Case Study, January 2024. Published online January 17, 2024.
[3] Robbins, J., AI startups grabbed a third of global VC dollars in 2024, Pitchbook. Published online January 9, 2025. Available at: https://pitchbook.com/news/articles/ai-startups-grabbed-a-third-of-global-vc-dollars-in-2024
[4] Ganti, A. et al., Venture Capitalists: Who Are They and What Do They Do?, Investopedia. Published online June 10, 2024. Available at: https://www.investopedia.com/terms/v/venturecapitalist.asp
[5] Davydova, D. et al., Why Do Startups Become Unicorns Instead of Going Public, National Bureau of Economic Research. Published October 2022. Available at: https://www.nber.org/papers/w30604
[6] Delossantos, C. From Hype to Bust: Investigating the Underlying Factors of the Dot-Com Bubble and Developing Regression Models for Future Market Predictions. Open Journal of Business and Management. Published online September 2023. Available at: https://www.scirp.org/journal/paperinformation?paperid=127628
[7] Lunden, I. AI investments surged 62% to $110B in 2024 while startup funding overall declined 12%. Techcrunch. Published online February 11, 2025. Available at: Techcrunch
[8] Opening moves in global AI. Dealroom.com. Published online February, 2025. Available at: https://dealroom.co/uploaded/2025/02/Dealroom-AI-Summit-2025.pdf?x63517
[9] Grabow, J., Massive AI deal supercharges VC results in Q1 2025. EY. Published online 23 April, 2025. Available at: https://www.ey.com/en_us/insights/growth/venture-capital-investment-trends
[10] PitchBook. AI & ML VC Trends. Published online 27 February, 2025. Available at: https://files.pitchbook.com/website/files/pdf/Q4_2024_AI_ML_VC_Trends_Preview.pdf
[11] AI investments surged 62% to $110B in 2024 while startup funding overall declined 12%, February 2025. Available at: https://shorturl.at/uK4DU
[12] Venture ESG LP. Pushing Forward Responsible Investing Practices Of VC Limited Partners with a Deep Dive on Responsible AI and Data. Published online February, 2025. Available at: https://www.ventureesg.com/wp-content/uploads/2025/02/VentureESG-Pushing-Forward-%E2%80%94-LP-White-Paper-Feb-2025.pdf
[Student IDEAS] by Leria Huang & Michelle Diaz - Master in Management at ESSEC Business School
AI is revolutionizing mental health care, offering innovative solutions like automating tasks, training clinicians, and performing assessments. However, diagnostic accuracy and data privacy are the gatekeeper elements that require more public attention. To better envision the AI therapist era, we anticipate the constant evolution of human-machine interactions will bring ripple effects across society…
---
As seeking assistance from AI chatbots becomes second nature in our daily lives, these advanced language models increasingly serve as companions during moments of uncertainty and distress. The release of chat GPT-4o has opened a new chapter for human machine interaction with the capacity of emotion recognition and real time response. Now the human-like robot available 24/7 has been considered not only as a smart encyclopedia but also as a compassionate support for people to open up with personal troubles and perplexity. Notably, major psychological chatbots have been more in demand, with 475 others named "therapy" or "therapist1" capable of conversing in multiple languages. These bots, such as Psychologist, have received a total of 78 million messages, tailoring responses to common mental health conditions such as depression and anxiety.
As AI expands into the realm of mental health, the potential risks and limitations remain a concern for the encompassing application in the therapy field. What defines good therapy? Can AI really be our new therapist? If so, what causes the concerns? If not, why is it challenging for AI to supplant human therapists? How can AI better assist in addressing mental health issues? This article will explore these questions in detail.
Therapy has existed in its modern form for decades, yet the stigma around it recedes slowly and qualified therapists are always in demand. The quality and availability of therapy stand out as the crucial issues amid a global shortfall in mental health care. The appearance of AI therapy plausibly provides an accessible and attractive solution.
AI chatbots are being deployed in a wide range of psychiatric settings, from offering essential emotional support to aiding in cognitive behavioral therapy (CBT)2. CBT aims to identify distortions in thought patterns and to make conscious efforts to change them3. As a commonly adopted treatment in the mental health field, CBT is more and more suggested, notably by the UK's National Institute for Health and Care Excellence4, to apply before medication for cases of mild depression. With well trained AI chatbots, patients are able to develop awareness and identify the patterns of mental problems in the conversations. A study in the International Journal of Psychiatric Trainees has shown that AI chatbots like ChatGPT can improve patient-reported quality of life in psychiatric settings (see Table 1 for a review of recent clinical trials)5.
Compared to in person or online therapy sessions, the 24/7 availability and inherent nonjudgmental nature of AI make it especially appealing. The barriers for traditional therapy sessions are clear: the time and financial cost, when and where to seek help, and more importantly, when and where the therapist is available to help. Even the most devoted therapist needs to eat and sleep and spend time on research.
In addition, the non judgmental quality is particularly attractive to minority communities experiencing marginalization, stress, and loneliness. One of the biggest obstacles to effective therapy is that patients are often reluctant to tell the truth. A study of 500 therapy-goers revealed that over 90% admitted to lying at least once6. The topics they concealed? Suicidal thoughts, substance use, and their sheer disappointment with the therapist's suggestions. Research has shown that people may be more comfortable disclosing personal information to a chatbot than to a human therapist. This phenomenon is attributed to a heightened sense of anonymity and a diminished fear of judgment7. The result is also backed up by a recent paper published in Nature Medicine: AI therapists, through improving the online triage and screening forms, effectively increased the access and exposure to therapies for minorities, who are often reluctant to open up for a therapy due to external and internal reasons. The engaging and anonymous nature of AI has increased the referrals for NHS in-person mental health treatment by 29% among people from minority ethnic backgrounds8.
Another further application awaiting to scale up is therapist training. As we can easily imagine, AI application in the analysis and study of numerous therapy sessions could be a great help. To quantify and qualify what works for therapy based on analyzing the transcripts from therapy sessions, is undeniable – a challenging work. Collecting, annotating and studying over these texts is basically what it takes to build up a huge natural language processing model. And that is exactly where AI could contribute: firstly, understanding the human language from the therapy session input, then learning from effective conversation data and improving its responses over time.
Researchers are also finding natural language processing models to be invaluable. A team at Drexel University in Philadelphia demonstrated that GPT-3 can predict dementia by analyzing speech patterns. For training therapists, this approach may offer better insights in a much shorter time from analyzing therapy session transcripts to identify patterns9. Experienced therapists can maintain high standards of care, while trainees can use the AI tool to enhance their skills and improve their practice.
As one can intuitively deduce, using AI in therapy is rampant with issues that make the application of the technology into the practice less than desirable. Below are some of the most plausible opportunities to seize and the risks involved:
At the core of making AI work is information. In healthcare, one of the most safeguarded aspects is patient privacy. More so in therapy or psychiatry. In the application of AI, the issue can be divided into two types: the abilities to uphold, and to respect data confidentiality.
Upholding data confidentiality involves the anonymization and safekeeping of patient information. And this is regardless of the use case, whether the AI will be applied into more administrative tasks or used more integrally in practice, like diagnosis for example. But companies and systems can be breached. A counter argument would be, companies and moreover, public institutions have always faced the security risk of breaches. How does AI then differ? AI complicates matters by its need to harness big data and by the algorithmic programs built to capitalize on the data. To ground this, consider a hypothetical security breach of a local hospital in a city in comparison to a breach of a private company with an AI-powered algorithm trained on a data set of all the hospitals in that city. Scale matters.
As for respecting data confidentiality, AI can also be deployed to do the opposite: find out people’s medical information, which ought to be protected. Indeed, a number of recent studies underlined how new computational strategies can be leveraged to identify individuals in health repositories managed by either public or private institutions, even when the data has been scrubbed and anonymized10. And a 2019 study successfully used a “linkage attack framework”—that is, an algorithm aimed at re-identifying anonymous health information—that can link online health data to real world people, demonstrating “the vulnerability of existing online health data11.”
A mix of these two issues would be instances wherein companies engage in data sharing–a misuse of data for commercial purposes without the consent or the knowledge of the people who own the data. For example, DeepMind partnered with the Royal Free London NHS Foundation Trust in 2016, and then later Google took over control of DeepMind’s app, essentially transferring access and control over stored patient data from the UK to the US. In instances where the data gathered refers to patient sessions with therapists and psychiatrists, the information could very well be consequential beyond the breach of privacy. Not unlike a CEO accidentally divulging proprietary information in a session that should by the bounds of medicine be safe; that data is at risk, even anonymized.
Given the overhead risks around data privacy and misuse, AI applications might be better utilized for administrative tasks until efficient regulation and precautions are in place. However, such prudence is rarely the reality. In the UK, the National Institute for Health and Care Excellence (NICE) fast-tracked the approval of nine mental health applications which are to be offered with the “NHS Talk Therapy primary care counseling services to treat anxiety and depression12.”
Provided that prudence is rarely the reality, let us consider an important use case of using AI in this field: diagnostics–the detection of an illness or disease. In medical diagnostics more generally, these can range from early disease detection, to better understanding disease progression, optimisation of treatments, and even the uncovering of new possible treatments. Such uses capitalize on the ability of AI to quickly recognize patterns and analyze large datasets.
But a key characteristic of mental health is its subjective and varied nature. Mental health clinical data is quite often written up in qualitative patient statements. Thus, misdiagnosis is a common issue. For example, a systematic review of misdiagnosis of obsessive-compulsive disorder (OCD) revealed elevated rates of OCD misdiagnosis in different professional communities and that “an average of 50.5% of the physicians misdiagnosed the OCD sketch of symptoms13.” Patients were either diagnosed with a different disease that was not OCD, even though it was. Or diagnosed with OCD incorrectly. Such mistakes lead to incorrect treatment that could worsen the health of the patient.
But despite the more nuanced nature of mental health, research shows that AI might also help in diagnostics. A combination of analytical techniques like modern neural-network algorithms, cross-validation procedures, and other methods powered by machine learning could reduce misdiagnoses. Indeed, increasing evidence suggests that the data crunching and data analysis powered by AI could support precision psychiatry14. Since humans have a “unique bio-psycho-social profile”. Using the unique biological, psychological, and social profile of an individual, the technology can be used to code for this, and cross-check with existing mental health diseases. Moreover, the requisite trial-and-error nature of prescribing medication might be improved or even overcome with the use of AI15.
Therefore, since there is a vast array of differences in the make-up of mental illnesses, the use of objective biomarkers that are tied more concretely into human biology may allow for a more objective definition of illnesses. In other words, using AI could improve the ability of medical professionals to create pre-diagnosis screening tools; thus better detecting an individual’s likelihood of developing a mental illness16.
Provided this, AI could be an improvement upon the Diagnostic and Statistical Manual of Mental Disorders, Fifth Edition. (DSM-5); the tool used by practitioners to diagnose and assess psychiatric disorders. The DSM-5 is meant to introduce some standard, but it is not perfect. As demonstrated by instances of false-positives wherein the tool has been criticized for expanding criterias for disorders17.
For example, to validate a reliable diagnosis, there needs to be consensus upon use of the criterias: if you give 10 people with depression the DSM-5 questionnaire, all should be diagnosed with depression. But in practice, the criteria appear to be arbitrary. If the DSM-5 lists 15 symptoms of depression, how many must the patient have to be diagnosed as depressed? Moreover, what if of those 15 symptoms, 7 symptoms are common to another disease? Is that person depressed, what type of depression, or does that person actually have chronic fatigue syndrome?
To conclude, in terms of using AI for diagnostics in mental health, the promise is not only present, but already demonstrably a worthwhile endeavor. Since diagnostics in mental health are in such a poor state. Indeed, leveraging AI for diagnostics in mental health seems to be curbed only, if we can use that tone, by overhead risks around data privacy and misuse.
To envision AI as our future therapist, the last crucial step is to recreate good interpersonal dynamics and build up more trust over AI. The nuanced approach comes from both ends: it entails fostering responsible development practices and understanding the evolving dynamics of human-AI interaction and its broader societal ramifications.
The key is to deliver the right words at the right time at the right pace. To replace real therapists, AI needs to develop the ability to capture different effective types of utterance and exchange during a session. Pioneering researchers from Ieso-a leading online therapy player, have already started to identify the effective parts of a therapy conversation at treating different disorders, based on the natural language processing18.
However, what constitutes an effective therapy has existed as the unlocked secrets in the therapy field for a long time. Why some therapists deliver better results could depend on the experience and gut instinct of qualified therapists. Indeed, machine learning could facilitate the analysis over a huge amount of therapy session transcripts but to what extent AI could read and pick up the emotions, tones, and pauses during a conversation will affect the analysis judgments. In fact, a qualified therapy involves compassion, active listening, gradual guidance to enable patients to spot the problem and develop enough courage and willingness to find solutions.
Moreover, the key elements of CBT-challenge the negative think pattern and guide to break the vicious cycle, demand not only expert knowledge in the psychology field but also the finesse of critical thinking and unconventional perspectives on thought, problematic emotions, and behaviors. Could AI itself develop this ability from exposure to large datasets to thus know when and how to gracefully call off a conversation and challenge the illusional assumption from the patient? This question will remain a myth since it is the equivalent of contemplating pondering over whether AI can develop self awareness or self consciousness. These remain as the challenging factors for an AI chatbot to serve as a wise hand holder who accompanies the patient to their own realizations.
Last but not least, the way how people perceive AI matters. Normally and essentially, therapists and clients need to build up great rapport. Based on the quantitative and qualitative study of therapy relations, American Psychological Association pointed out that alliance, goal consensus, the real relationship and therapy credibility are the key elements of effective therapy. In some circumstances, the relationship between therapist and client serves as a relationship model or reference for clients to interact with the world and people around. Along this journey of building a therapeutic relationship, it involves perceiving feelings, communicating appropriately, setting boundaries, etc.
To foster this nurturing therapy relationship, efforts come from both therapists and patients. Indeed AI could be trained to provide structured interactions, socratic questioning, prescriptive actions. It's as if AI has become a modern-day Socrates, offering epiphanies left and right. However, as we contemplate over this, do people view AI as a reliable agent or even a good friend? The answer to this question can affect the dynamics of the interactions a lot. Given that fake information appears in the responses from chatGPT, AI hallucinations, the incorrect or misleading results that AI models generate, might still be haunting our minds for a while until humans can really trust AI and deem it reliable. Moreover, a therapist needs to represent a certain level of authority to talk people out of a desperate and nihilistic situation. Delegating this authority to AI introduces an ongoing ethical debate. Can we, should we, trust a synthetic intelligence with such significant influence while human intelligence itself can barely handle the problem it created? The conversation is far from over.
The answer seems intuitive, everyone goes through something; show me a human being without some level of trauma and I’d wager that might be an alien. To live unscathed is to not live at all. As such, which subset of the vast diversity of humanity could an AI therapist prove to be most beneficial for? The division of humanity can be done in a variety of ways, from age bracket, to income level, or geographic location.
To distill the most pertinent user base, let us consider some intuitive success metrics an integration of AI in therapy would entail: revenue of AI therapist providers, number of people with mental health issues helped, and healthcare professionals whose jobs are made easier.
AI Market Size Worldwide: 2020 - 2030:
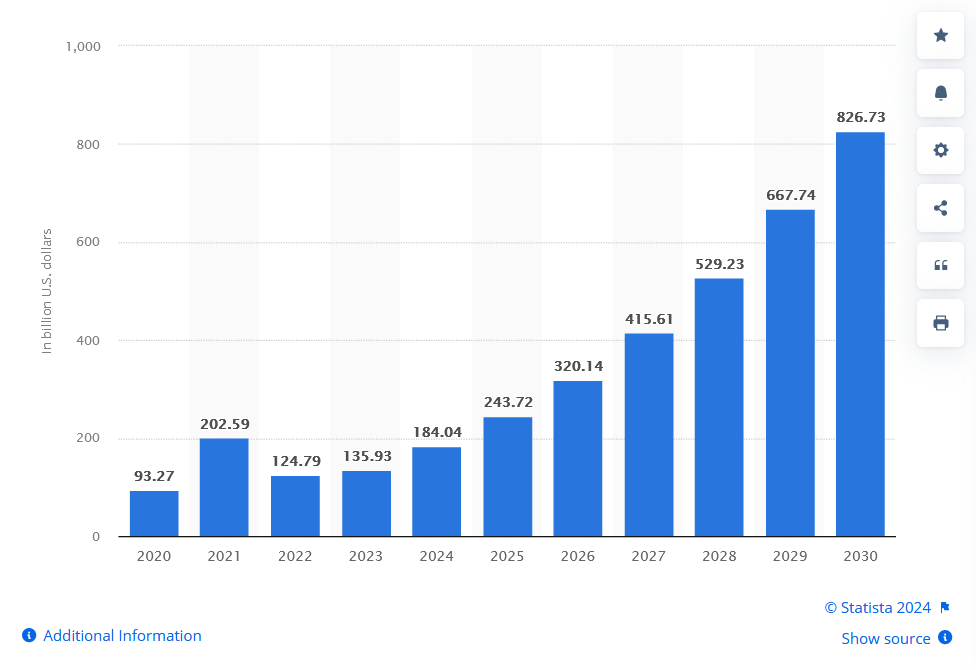
As it stands, the market size for AI usage is projected to continuously grow as we reach the end of this decade. Statistics from OpenAI reveal that their user base has a gender distribution of 43.89% female and 56.11% male users. And that the majority of users are in the 25-34 age group, with usage traffic led by the United States, followed by India, Colombia, the Philippines, and Japan19. Not only is there a trend of an increase in usage, but also a subset of the population that uses it more.
Now, such usage may or may not be direct, in that people may use a service that has somewhat adapted AI in its value chain or otherwise. But the statistics from OpenAI indicate that a certain demographic has an interest in using it directly: the 25-34 age group. In this case, the central group that an AI therapist would be of interest to might be best narrowed down to students, young professionals, the working class, and those in their early 20s to early 40s. These groups of people are distinguished by their tech-savviness, the likelihood that their work involves or is impacted in some way by AI, and the degree to which having cheaper and easier access to therapy would be a plus point. Indeed, senior groups or high earners would likely not be early adopters. In 2019, the US Department of Health and Human Services conducted a National Health Interview Survey20 that revealed just “11.6% of those aged between 18-44 completed therapy or counseling, but 9.1% of people 45-64 and just 5.7% of people 65 and older received therapy.” And that the lower the socioeconomic status, the less likely someone is to seek or receive therapy21.
In terms of segmentation by psychological need, let us consider three of the intuitive success metrics: leverage the current capabilities of AI, improve said capabilities over time, and make the work of healthcare better overall. Therefore, to respect the three metrics mentioned above, it is imperative that AI be a companion to therapy and not become the therapist. Or at least, not yet, if ever, at all.
Indeed, the more severe the psychological need or therapy required, a case that can be made is such a scenario is best left to actual medical professionals who have the work experience–to not treat such patients as a learning curve for the algorithm. The counter argument might be that such difficult patient cases might be where AI could thrive. After all, as mentioned earlier, having accurate data markers coupled with machine learning could capitalize on the “unique bio-psycho-social profile” of humans22.
Risk is present in either case, for the patient, the company the AI belongs to, and the healthcare professionals. All these actors may also have conflicting interests to further complicate matters; profit, the overhead motivation of improving mental healthcare overall, easing work for medical professionals, and widening access to care. For example, profit could easily be more prioritized by companies, at the expense of the patient and medical practitioners. In essence, there is much to contend to bring about an AI chatbot that could someday, possibly put your therapist to shame.
So is AI going to be our new therapist? Unlikely. But its potential in the field is indisputable. Currently, we argue that it could be beneficial for preliminary diagnoses, medical training, patient reminders, and administrative tasks to name but a few. Even just these applications could significantly reduce the workload of a therapist, making the patient experience more satisfying. But curbed by the caveat of safeguarding privacy, data, and ethical usage.
However in a future where AI might actually become a viable alternative to human therapists, the question becomes: should that be a goal to pursue? What is intimacy, does it matter, is it what we need to replicate? What is lost, if anything, by the removal of the human aspect in this almost sacred relationship between us and our therapists? In a profession so reliant on human connection, could a chatbot even account for the complexity of human culture?
In the course of this article, we identified trust, great interpersonal dynamics, psychological safety, and active listening as the most important qualities of a good therapist. But as anyone who has spoken to a therapist or even less officially, like having a therapy session with a good friend–we understand; these qualities are not exactly exhaustive.
Thus, if at some point we are faced with the decision of opting for a chatbot to aid us sort our internal turmoils, the benefits must not only be comparable. But in some sense or another, far more. The ambition must simply be this: the benefits ought to outweigh the risks for everyone involved, from the patient, to the healthcare system, and even the company providing the service.
[1] Character.ai: Young people turning to AI therapist bots,BBC.com Technology, April 2024. Available at:
https://www.bbc.com/news/technology-67872693
[2] Choi, I., Milne, D.N., Deady, M., et al., 2021. Mobile app-based chatbot to deliver cognitive behavioral therapy and psychoeducation for adults with attention deficit: A development and feasibility/usability study. International Journal of Medical Informatics. Published online June 2021. doi:10.1016/j.ijmedinf.2021.104431
[3] Clinical Practice Guideline for the Treatment of Posttraumatic Stress Disorder, 2017. Available at: https://www.apa.org/ptsd-guideline/patients-and-families/cognitive-behavioral, What is Cognitive Behavioral Therapy?
[4] 4 ways artificial intelligence is improving mental health therapy, December 2021
[5] Melo A, Silva I, Lopes J. ChatGPT: A Pilot Study on a Promising Tool for Mental Health Support in Psychiatric Inpatient Care, International J of Psychiatric Trainees, February 2024. Published online February 9, 2024. doi:10.55922/001c.92367
[6] He checks in on me more than my friends and family: can AI therapists do better than the real thing? Guardian, May 2024. Available at: https://www.theguardian.com/lifeandstyle/2024/mar/02/can-ai-chatbot-therapists-do-better-than-the-real-thing
[7] Melo, A., Silva, I., and Lopes, J., 2024. ChatGPT: A pilot study on a promising tool for mental health support in psychiatric inpatient care. International Journal of Psychiatric Trainees. Published online February 9, 2024. doi:10.55922/001c.92367
[8] Smith, A., 2024. ‘He checks in on me more than my friends and family’: can AI therapists do better than the real thing? The Guardian. Published online March 2, 2024. Available at: https://www.theguardian.com/lifeandstyle/2024/mar/02/can-ai-chatbot-therapists-do-better-than-the-real-thing
[9] Zhu, Y., and Wang, L., 2022. Predicting dementia from spontaneous speech using large language models. PLOS Digital Health. Published online December 2022. doi:10.1371/journal.pdig.0000168
[10] Gymrek, M., McGuire, A.L., Golan, D., Halperin, E., and Erlich, Y., 2013. Identifying personal genomes by surname inference. Science. Available at: https://www.ncbi.nlm.nih.gov/pmc/articles/PMC8442400
[11] Price, W.N. and Cohen, I.G., 2021. Privacy and artificial intelligence: challenges for protecting health information in a new era. PubMed Central. Published online September 2021. Available at: https://www.ncbi.nlm.nih.gov/pmc/articles/PMC8442400
[12] ibid.
[13] National Institute for Health and Care Excellence (NICE), 2023. Nine treatment options to be made available for adults with depression or an anxiety disorder. Published online May 2023. Available at: https://www.nice.org.uk/news/articles/nine-treatment-options-to-be-made-available-for-adults-with-depression-or-an-anxiety-disorder
[14] Giron, P., and Storch, E.A., 2021. A systematic review of misdiagnosis in those with obsessive-compulsive disorder. Journal of Affective Disorders Reports. Published online December 2021. doi:10.1016/j.jadr.2021.100157.
[15] Chekroud, A.M., 2018. Machine learning for precision psychiatry: Opportunities and challenges. Psychiatry Clinics of North America, 41(3), pp.505-518. Published online March 2018. doi:10.1016/j.psc.2018.07.005.
[16] Psychology Today, 2024. Precision psychiatry. Available at: https://www.psychologytoday.com/sg/basics/precision-psychiatry
[17] Fried, E.I., and Cramer, A.O.J., 2019. Machine learning in mental health: A scoping review of methods and applications. Psychological Medicine. Published online February 2019. Available at: https://www.cambridge.org/core/journals/psychological-medicine/article/abs/machine-learning-in-mental-health-a-scoping-review-of-methods-and-applications/0B70B1C827B3A4604C1C01026049F7D9
[18] Frances, A., 2015. DSM-5, psychiatric epidemiology, and the false positives problem. PubMed Central. Published online June 2015. Available at: https://www.ncbi.nlm.nih.gov/pmc/articles/PMC6998664/
[19] Woods, D., 2021. The therapists using AI to make therapy better. MIT Technology Review. Published online December 6, 2021. Available at: https://www.technologyreview.com/2021/12/06/1041345/ai-nlp-mental-health-better-therapists-psychology-cbt/
[20] OpenAI Statistics 2024 By Demographics, Products, Revenue and Growth, Enterprise Apps Today, May 2024.Available at: https://www.enterpriseappstoday.com/stats/openai-statistics.html
[21] National Health Interview Survey, NCHS, 2019. Available at: https://www.google.com/url?q=https://www.cdc.gov/nchs/data/databriefs/db380-H.pdf&sa=D&source=docs&ust=1719992185310817&usg=AOvVaw0Krs5PYGwVAVzxTbKzjyZZ
[22] Who Goes To Therapy? Statistics And Research About Who Is Seeking Support, Better Help, September, 2024. Available at: http://bit.ly/4fepHGT
[23] Machine learning in mental health: A scoping review of methods and applications, Psychol Med, 2019. Available at: https://www.google.com/url?q=https://www.ncbi.nlm.nih.gov/pmc/articles/PMC7274446/%23R27&sa=D&source=docs&ust=1719975466269379&usg=AOvVaw0DqfMh826OAS5By_um0Oxv