Mis en avant

Created in 2020 to support the rise of Artificial Intelligence and examine its societal impact, ESSEC Business School’s Metalab Institute is expanding its scope to fully integrate the business dimension, becoming the ESSEC Institute for AI & Business.
Designed to serve as a leading hub for impact—championing ethical, responsible AI that creates value for both business and society—the Institute operates under the Directorate of Institutes, Development, and Impact, led by Félix Papier. For the start of the new academic year, ESSEC is pleased to announce three appointments within its Institute for AI & Business: Constance Mickiewicz as Executive Director, Raoul V. Kübler as Academic Director, and Christoph Mueller-Bloch as Associate Academic Director.

Having previously worked alongside Anne Bouverot during her mandate as Special Envoy of the President of the French Republic for AI, Constance joins ESSEC with extensive expertise in multilateral diplomacy, international development, and AI policy coordination across major global forums.
In 2025, she oversaw the diplomatic track of the AI Action Summit under the high patronage of the President of the French Republic, where she served as lead negotiator for the Heads of State Declaration. Prior to that, she was a Digital Policy Advisor for the G7 and G20 international summits at the French Ministry for Europe and Foreign Affairs. Her international career also includes serving as Government Partnerships Officer at the United Nations World Food Programme in Rome (2018–2021) and as an Analyst at Palladium, an international development consulting firm based in London.
Constance holds a Master’s degree in International Development from University College London (UCL) and a Master in Management (Grande École program) from NEOMA Business School.
“My ambition for the ESSEC Institute for AI & Business is to establish it as a leading ‘control tower’ for ethical, responsible, and value-creating AI for organizations. In a fiercely competitive global AI landscape dominated by China and the United States, Europe must make its voice heard. ESSEC intends to place itself at the heart of this challenge by championing a resolutely humanist approach. Positioned at the crossroads of academic research, tangible economic impact, and public debate on governance and ethics, the ESSEC Institute for AI & Business will equip today’s and tomorrow’s leaders with the keys to navigating the societal and geopolitical stakes of AI.”
— Constance Mickiewicz

Raoul V. Kübler is a Professor of Marketing at ESSEC and a recognized expert in artificial intelligence, digital transformation, data analytics, and digital marketing.
Since 2018, he has consistently ranked among the top 10% of business administration researchers in the German-speaking world. His research on AI-driven transformation, user-generated content, and natural language processing (NLP) has been published in leading academic journals and has received numerous distinctions, notably from the Academy of Marketing Science, the Marketing Science Institute, and the European Marketing Academy. His current work explores how generative AI and agentic AI are reshaping businesses and society.
He holds a PhD in Marketing from Kiel University (Germany), earned in 2012. Before joining ESSEC in 2022, he served as Assistant Professor of Marketing at Özyeğin University in Istanbul, and subsequently as a Junior Professor Chair at the University of Münster. Prior to his academic career, he spent over a decade working in the advertising industry.
“We are witnessing a new wave of digital transformation. Generative AI is challenging, reshaping, and enriching long-established business practices. Unlike the first wave, this one comes with immense public expectations; how society and businesses respond when these expectations collide with inevitable setbacks will shape the future. At the Institute for AI & Business, our goal is to help decision-makers navigate this transition: separating hype from empirical evidence, building sustainable, value-creating business models, and managing disruption so that our partners emerge as leaders rather than followers—or worse, casualties of these shifts.”
— Raoul V. Kübler

Christoph Mueller-Bloch holds a PhD in Information Systems from the IT University of Copenhagen, a Master of Science in Business Administration and Information Systems from Copenhagen Business School, and a Bachelor of Science in Business Administration from the University of Göttingen.
He joined the ESSEC faculty in 2021 as an Assistant Professor in the Department of Information Systems, Decision Sciences and Statistics. His research and teaching focus on the management of digital technologies, including artificial intelligence, blockchain, and social media.
“I am delighted to take on my new role within the Institute. Artificial intelligence is arguably the most transformative technology since the advent of the Internet, and we have a unique opportunity to shape its impact on business and society. I look forward to further developing the Institute as a platform for value co-creation with our stakeholders—whether by offering learning pathways that empower students to reach their full potential, or by fostering an environment where faculty can pursue projects with genuine real-world impact.”
— Christoph Mueller-Bloch
ESSEC Executive Community Evening 2026 | November 19, 2026 — Institut du Monde Arabe, Paris
Bringing together nearly 300 ESSEC Executive Education alumni, senior executives, and institutional partners at the Institut du Monde Arabe in Paris, the 2026 ESSEC Executive Community Evening explores how artificial intelligence and data are reshaping leadership and organizational strategy.
Designed to move beyond technical demonstrations and focus on concrete strategic choices, the evening opens with a masterclass by Professor Raoul Kübler (Professor of Marketing and Academic Director of the ESSEC Institute for AI & Business) on turning AI capabilities and data insights into measurable business value.
Moderated by Constance Mickiewicz (Executive Director of the ESSEC Institute for AI & Business), the executive roundtable brings together senior leaders from consulting, industry, tech, and public diplomacy to examine three core challenges:
This October, the ESSEC Institute for AI & Business actively contributed to major discussions shaping the future of artificial intelligence - both in transforming higher education and in advancing international AI governance. Here is a look back at two landmark events.
On October 13, 2026, the Institute partnered with Onepoint for the Métamorphose(s) de l'Éducation event in Paris. Hosting a dedicated booth in the innovation showroom, the Institue for AI & Business team presented its vision for the future of learning and showcased concrete solutions designed for the age of artificial intelligence. The event provided a valuable platform to connect and exchange perspectives with researchers, educators, entrepreneurs, and decision-makers driving educational transformation.
The Institute also co-organized a high-level roundtable on the occasion of the Paris visit of Amit Shukla, Joint Secretary (Cyber Diplomacy) at the Ministry of External Affairs of India. Bringing together leading voices from academia and research—including Pablo Rice (Paris Peace Forum), Nicolas Miailhe (AI Safety Connect), Aurélie Simard (Inria), and Raoul Kübler (ESSEC Business School) - the session was moderated by Constance Mickiewicz (Executive Director, ESSEC Institute for AI & Business).
Tracing the international roadmap from the AI Action Summit in Paris (2025) to the AI Impact Summit in Delhi (2026) and ahead to the Geneva Summit (2027), participants explored French and Indian perspectives on AI governance, technological sovereignty, and model security.
Through these two initiatives, the ESSEC Institute for AI & Business continues to fulfill its core mission: fostering an AI ecosystem that is both technologically sovereign and ethically responsible.
[Student IDEAS] by Hugo Jalet - Graduate of the Global BBA at ESSEC Business School
Artificial intelligence is fundamentally altering the statistical nature of cyber risk in finance, shifting it from an isolated, firm-specific operational threat into a correlated, fat-tailed financial variable. By moving attack vectors from network perimeters to training data and foundation models—and with high market concentration across a few cloud and AI providers—AI-driven threats introduce heavy-tailed loss severity, accelerated industry-wide propagation, and extended detection lags where malicious interventions hide as ordinary "model drift." Because existing financial pricing, capital buffers, and board governance remain calibrated to pre-AI historical data, institutions are running an unpriced tail risk that threatens equity financing, liquidity, and balance sheet stability; addressing this requires integrating cyber and AI governance, stress-testing for multi-day operational outages, and sizing capital against third-party concentration.
---
In early 2024, a finance employee at the British engineering firm Arup joined what looked like a routine video call with her chief financial officer (CFO) and several colleagues. By the end of it, she had authorised fifteen transfers totalling roughly $25 million to accounts in Hong Kong. Weeks later, the firm discovered that every participant on the call, CFO included, was a deepfake: a hyper-realistic fake video and voice, generated by artificial intelligence (AI), that impersonates a real person.1 The story made headlines for a few days, then faded. It should not have. By mid-2025, deepfake-enabled fraud alone had driven close to $900 million in reported losses globally, with more than $410 million concentrated in the first half of the year, already exceeding the total for all of 2024.2
The Arup incident is usually told as a story about weak verification protocols and the need for better employee training. That framing is not wrong, but it is far too narrow. Arup lost money on a single wire; the underlying phenomenon is something finance has not yet priced. Artificial intelligence is quietly reshaping what cyber risk looks like as a statistical object. Losses are becoming less idiosyncratic and more correlated, tails are fatter, detection is slower, and propagation across firms is faster, largely because banks, insurers, and asset managers increasingly share the same foundation models, training data, and cloud vendors.
This matters because finance has, for more than a decade, treated cyber as primarily an operational and compliance issue: a cost line, a maturity score, an audit-committee bullet. That mental model was already strained, and in an AI-driven system, it quietly breaks. Cyber resilience is no longer a sidebar; it is a financial variable whose distribution has shifted, and which neither markets nor most institutions have repriced. The practical question for boards, chief risk officers (CROs), and investors is therefore not "how much more should we spend on security?" but "how must we redesign governance, capital planning, and disclosure once the tail of cyber losses has moved?"
To see why the familiar playbook no longer fits, it is worth being precise about what is genuinely new.
The past decade of digital transformation in finance mostly expanded what cyber risk could affect: more systems online, more data in motion, more third parties in the chain. Artificial intelligence does something different. It shifts four properties of the loss distribution itself, and each of these shifts quietly erodes the "perimeter plus patch" mental model (the assumption that security means defending a network boundary with firewalls and access controls, then closing known software flaws with timely patches) that still governs most cyber budgets.
The attack surface moves from code and credentials to data and models. Classical cyber defence is organised around code, infrastructure, and identities: firewalls, segmentation, access controls, patch cycles. An AI system is a different object. It can be compromised by corrupting the training data itself, before a single credential is ever stolen. Yerlikaya and Bahtiyar (2022) show how quickly this matters. They study data poisoning, which means deliberately corrupting part of the training data, the data used to teach and build a model. Across four datasets (spam, botnet, malware, and medical diagnostics) and six standard algorithms, the researchers deliberately altered the correct classifications in a quarter of the training data (labelling spam as legitimate, for instance). This alone cut classification accuracy by 15 to 40 percentage points, and when half of the training data was corrupted, model performance collapsed in several configurations. Transposed to finance, this is a structurally new threat: a well-placed intervention in the training pipeline (the process that collects, prepares, and feeds data into a model while it is being built) of a credit-scoring model, a transaction-monitoring engine, or an algorithmic pricing system does not need to breach the firewall to cause losses.
These threats target two distinct stages in the life of an AI system. At training time, while the model is being built, data poisoning and training-set contamination corrupt what it learns. At inference time, when the trained model is being used to make real decisions, attackers exploit it through prompt injection (hiding malicious instructions in the text or data the model reads) and model manipulation (feeding it carefully crafted inputs, or tampering with the model itself, so that it produces the outputs the attacker wants). Both bypass the controls built for the old perimeter: neither needs to breach a firewall or steal a credential, because the vulnerability lives in the data and the model itself, not at the network boundary. They now sit beside ransomware and phishing on the threat list.
Detection lag lengthens because model failure looks like drift. Traditional cyber incidents are largely binary. A system is down, an account is drained, a file is encrypted. AI failures are probabilistic. A poisoned fraud model does not stop working; it simply scores certain transactions a little more leniently. A manipulated credit model does not crash; it tilts approvals in a subtle direction. These incidents are easily reinterpreted as "model drift", an accepted, almost decorative feature of machine-learning (ML) models in production. The result is that the time between occurrence, discovery, and recognition stretches. Even without AI, the problem is already acute: using cross-country operational-loss data from seventy banks over sixteen years, Aldasoro et al. (2023) document an average lag of more than a year between when an operational loss occurs and when it is finally booked (formally recorded as a loss in the accounts), with a long-tailed distribution in which a meaningful share of events remain unaccounted for after two years. Layer on the probabilistic opacity of AI systems and one should expect that distribution to stretch further, not tighten. For capital and liquidity planning, the implication is unpleasant: by the time a model-level compromise is formally recognised, much of its damage may already have been absorbed into the balance sheet.

Timeline of an operational loss event. Source: Aldasoro et al. (2023). Three dates structure every loss event: occurrence, discovery, and recognition. AI-driven incidents stretch t₁ (occurrence → discovery) because probabilistic failures resemble model drift.
Propagation accelerates through shared models, shared data, and concentrated cloud providers. The novelty is blunt: banks, insurers, and asset managers no longer need to do business with each other to share cyber exposure; they only need to rely on the same foundation model, the same training corpus, or the same hyperscale cloud provider, so a single compromise can reach firms with no direct contractual link. This is a different transmission channel from the one finance is used to.
In the pre-AI cyber world, contagion travelled mainly through explicit economic linkages: interbank exposures, counterparty relationships, payment networks. The pre-mortem analysis of Fedwire by Eisenbach, Kovner and Lee (2022) already showed how powerful that channel alone could be. The impairment of any one of the five largest U.S. banks spills over to an average of 38% of the network. A shock concentrated on a single third-party service provider common to several large institutions does even more damage: it pushes the weighted share of impaired institutions to roughly 60%, with potential forgone payment activity reaching more than 2.5 times daily gross domestic product (GDP) once banks start hoarding liquidity.
That shared layer is no longer hypothetical. In the 2024 survey by the Bank of England and the Financial Conduct Authority (FCA), 75% of UK financial firms reported already using AI, up from 58% two years earlier, though adoption remains uneven: many firms are still standing up data pipelines or running a general-purpose chat assistant for back-office work, while a smaller set already embeds foundation models directly into credit, fraud, and trading decisions. Foundation models account for 17% of all use cases, and a third of use cases now run on third-party implementations (Bank of England and FCA, 2024).
That third-party supply is strikingly concentrated: the three most-cited providers account for 73% of all named cloud providers, 44% of model providers, and 33% of data providers. Concentration on that scale means many institutions are exposed, without any direct link to one another, to the same handful of upstream failures, which is why the same survey ranks cybersecurity as the highest perceived systemic risk and critical third-party dependencies as the fastest-growing one. This is precisely the concern the EU's Digital Operational Resilience Act (DORA) attempts to address through its oversight regime for "critical" third-party information and communication technology (ICT) providers, which formally recognises for the first time that cloud and model concentration is a systemic variable, not a purely commercial one (Kun, 2024).

The figure shows the distribution of the network impact for the scenario with a disruption originating from a third-party service provider. “Share” represents the unweighted percent of institutions that become impaired. “Weighted share” represents the percent of institutions that become impaired, weighted by asset size. “Net weighted share” refers to the percent of institutions that become impaired, net of the shocked institutions.
Loss tails fatten because one compromise now hits many pipelines at once. The combination of the first three shifts has a direct statistical consequence: the severity distribution of cyber losses becomes heavier in the right tail. If a single poisoned dataset or compromised model feeds credit decisioning, fraud scoring, and trading signals across multiple institutions, a single event generates correlated losses across several profit-and-loss (P&L) lines and several firms simultaneously. Aldasoro et al. (2023) already find that although cyber events are still rare relative to other operational losses, cyber risk can account for up to a third of a bank's total operational value-at-risk, with most of that contribution concentrated in the tail. A 2025 panel of chief information security officers (CISOs) and board directors convened by McKinsey and the National Association of Corporate Directors (NACD) captures the shift in blunt terms, with one participant noting that under AI-fuelled threats, the "variability and severity are so drastic" that traditional maturity scores carry little signal (McKinsey & Company, 2025).
Taken together, these four shifts describe a cyber risk that is less idiosyncratic, less binary, more correlated across firms, and slower to surface than the one the industry has built tools for. The governance model inherited from the last decade (a CISO who patches systems, an audit committee that tracks maturity scores, and an insurer who prices firm-level history) was not designed for this object. The question is what happens once this new distribution is properly recognised, first in prices and capital, then in governance and disclosure.
A shift in the cyber loss distribution only matters financially to the extent that it travels into the numbers that boards, creditors, and markets actually look at. And on current evidence, much of that journey has not yet happened.
Inside the firm. The most visible channel is the earnings hit. Operational losses from remediation, incident response, customer notification, legal fees, and regulatory fines feed directly into quarterly results. Using a cross-country panel of roughly seventy large banks over sixteen years, Aldasoro et al. (2023) estimate that operational risk capital varies between 1% and 7.5% of gross income depending on the calibration method used, and that cyber-specific capital can account for up to a third of that total. Franco et al. (2024) argue that even those figures underestimate firm-level exposure for the median institution because they remain rooted in probability-based simulations rather than observed real-world loss data; their Real Cyber Value at Risk (RCVaR) framework is designed precisely to close that gap by estimating costs directly from industry incident reports.
A second channel is the balance sheet. Remediation spending, accelerated information-technology investments, and litigation reserves erode capital buffers over the quarters that follow an incident, which changes how firms finance themselves. Liu, Luo & Yawson (2025), using a U.S. sample running from 2005 to 2019, find that attacked firms become 56% to 61% less likely than matched non-attacked firms to undertake a seasoned equity offering (SEO), that is, a new share issue by an already-listed company, over the three years after the attack, with SEO proceeds dropping in parallel. The mechanism they document is not a shortage of capital need but an excess of capital cost: reputation loss raises the adverse-selection premium that equity investors demand, and firms rationally shrink their equity issuance. The effect also spills over to industry peers who were not themselves attacked, whose SEO probability falls by roughly 18% to 20% of its baseline and whose SEO proceeds decline by about 13.5%, suggesting that markets treat a single cyber event as information about a sector's underlying cyber risk, not just about the target firm.
The third and most underappreciated channel is liquidity. Eisenbach, Kovner & Lee (2022) show that a successful cyber attack on any one of the top-5 U.S. wholesale payment banks impairs on average 38% of the network, and that once uninfected banks begin hoarding liquidity defensively, forgone payment activity can reach more than 2.5 times daily GDP within a few days. This matters particularly in AI-driven finance because authentication, payments, trade settlement and fraud routing all increasingly depend on ML-based systems. A model-level compromise does not only hit the targeted firm's P&L; it can disable a counterparty's ability to send or receive, which is a classical liquidity event wearing an AI costume. What looks operational becomes financial the moment confidence in settlement is shaken.
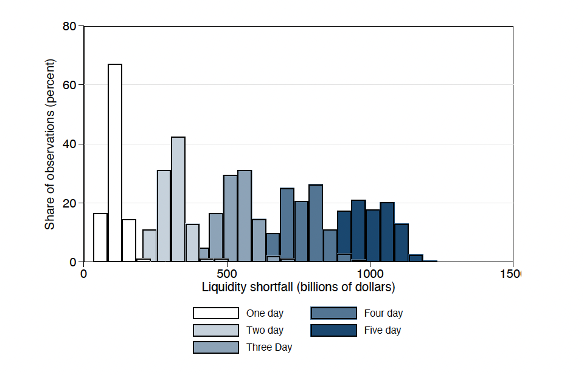
The figure shows the distribution of aggregate liquidity shortfall resulting from an attack that lasts from 1 to 5 days, averaged across the top-5 scenarios.
In markets. Do equity and credit markets price any of this? Partially. The existence of a cyber risk premium is by now empirically documented: firms with higher cyber exposure trade at a discount and face measurably higher costs of external financing after incidents (Jiang et al., 2024; Liu, Luo & Yawson, 2025). But the size of that premium is calibrated to the pre-AI tail. It reflects the historical distribution of cyber events as rare, largely firm-specific, and usually reversed within a few quarters. It does not yet reflect the four shifts described above: correlated incidents across firms that share a foundation model or a cloud region, slow-maturing damage from poisoned training sets, and losses that simultaneously hit credit decisioning, fraud scoring, and trading signals. The useful question is therefore not "is cyber risk priced?", but "is the post-AI tail priced?". On current evidence the answer is largely no.
Why not? Four structural frictions keep the post-AI tail out of prices.
Opacity. Cyber events are systematically under-reported. Aldasoro et al. (2023) document an average lag of more than a year between the occurrence of an operational loss and its recognition on the balance sheet, with a meaningful share of events still unaccounted for after two years. Markets cannot price what they cannot see, and as long as AI-related incidents hide inside "model drift" or "performance degradation", the signal does not reach them.
Externalities. Vendor and model concentration is a public bad. An institution that chooses a hyperscale cloud provider or a dominant foundation model captures private benefits (cost, performance, speed) but imposes a systemic risk that its own funding spread does not internalize. Kun (2024) argues that this is exactly the gap DORA's oversight regime for critical ICT providers was introduced to fill: firm-level risk management cannot price a shared-infrastructure externality, which is why a public authority has to look at concentration directly.
Rare-event neglect. Fat-tailed distributions are hard to estimate from short histories, especially when the underlying generating process has recently changed. The pre-AI cyber loss series is neither long enough nor stationary enough to calibrate a post-AI tail, and market participants (like most people) tend to under-weight tail risks they have not personally lived through.
Correlation blindness. Markets price firms, not shared-infrastructure clusters. There is no traded instrument whose payoff depends on whether ten banks share the same credit-scoring model, the same transaction-monitoring vendor, or the same cloud region. Until such an instrument exists, or until supervisors require concentration disclosure, correlated tail risk remains diversified on paper but concentrated in reality, which is the worst of both worlds for holders of the equity and debt of such firms.
The cumulative effect of these four frictions is that funding spreads, valuation multiples, and cyber insurance pricing continue to reflect a distribution that has already moved. Institutions whose capital planning, liquidity stress tests, and board-level risk dashboards rest on those same prices are therefore running a hidden short position on the post-AI tail. The rest of the article asks what changes (in governance, in disclosure, and in the practical work of CROs, CFOs, boards, and investors) once that short position is properly acknowledged.
If the post-AI tail is not yet in prices, the governance question is where the adjustment should come from. No single actor can close the gap: CROs and CFOs need to rebuild the quantitative plumbing, boards need to govern AI and cyber as one integrated risk, and investors and supervisors need to replace narrative assurance with credible tests. Institutions that move first stand to gain more than safety: the evidence discussed above suggests they may also fund themselves more cheaply and earn greater counterparty trust.
For CROs and CFOs: rebuild the quantitative plumbing. Three moves matter. First, model cyber losses at the tail, not at the mean. Franco et al. (2024) argue explicitly that most existing cyber capital models remain rooted in probability-based simulations calibrated on thin historical samples, exactly the wrong posture when the generating process has changed; their RCVaR framework estimates costs from observed industry data and makes the gap between expected loss and the 95th percentile explicit. Aldasoro et al. (2023) provide an independent benchmark: operational risk capital varies between 1% and 7.5% of gross income depending on calibration, with cyber-specific capital reaching a third of that. A capital plan sitting near the lower bound of those ranges is making an implicit bet that the post-AI tail will look like the pre-AI one.
Second, add authentication and payment outages to liquidity stress tests. Eisenbach, Kovner and Lee (2022) show that a five-day payment impairment at one of the five largest U.S. banks produces aggregate system liquidity shortfalls rising from roughly $122 billion on day one to around $1 trillion by day five, and that at the individual-bank level the 95th-percentile shortfall can reach 5% of risk-weighted assets or 37% of tier-1 capital.

Distribution of liquidity shortfall across impaired banks, relative to risk-weighted assets (left) and tier-1 capital (right). Source: Eisenbach, Kovner & Lee (2022). The tail is long: at the 95th percentile, shortfalls reach roughly 5% of risk-weighted assets and 37% of tier-1 capital. Capital buffers calibrated to the mean of this distribution leave the firm materially exposed to the tail.
Most internal liquidity frameworks still do not include a scenario in which the firm's ability to authenticate customers or send payments is disabled for several business days. Adding such scenarios, and sizing contingent buffers accordingly, is the single most concrete change a CFO can make.
Third, calibrate capital buffers to vendor concentration, not only firm-level history. The Bank of England's 2020 survey, cited by Kun (2024), finds that over 70% of U.K. banks and 80% of insurers use only two cloud providers for infrastructure services. Eisenbach et al. (2022) quantify the systemic side: a shock to a third-party service provider common to several large institutions impairs roughly 60% of the network by assets. CROs therefore need a vendor-concentration metric that feeds directly into capital buffer sizing, alongside a single risk register integrating model, data, and infrastructure exposures.
What makes such a test different from current ones is the unit of analysis. A conventional stress test breaches one firm at a time; a vendor-concentration test shocks the shared provider, not the firm, and asks how much of the book fails with it. In practice, it maps each critical AI dependency (foundation model, cloud region, data vendor) to the lines of business that rely on it, and identifies where the same provider silently underpins supposedly independent functions such as credit scoring, fraud detection, and trading. It then measures the correlated loss when that one provider goes down, and sets it against how many direct competitors share the same dependency. Given that three providers already account for the bulk of cloud and model relationships, those overlaps are the rule, not the exception.
For boards: govern AI and cyber as one integrated risk. The McKinsey and NACD (2025) panel of CISOs and directors is blunt that "the era when cybersecurity was a separate, isolated function at organizations is over" and that AI-fuelled threats require what one panellist calls "air-to-ground coverage" across the institution. In practice, this means moving cyber out of the audit-committee sidebar into a standalone risk or technology committee with genuine technical fluency, and changing the metrics boards track. Generic maturity scores were designed for a world where cyber was firm-specific and procedural; they do not capture the post-AI tail. The metrics that do are operational: credible recovery time objectives for AI-dependent services under adversarial conditions, vendor and model-concentration exposure, and the credibility of the firm's scenario library. Concretely, a post-AI tail metric is not a maturity score but a small set of tail-sensitive quantities tracked over time: a concentration ratio (the share of AI-dependent critical services running on the firm's single largest external model, cloud, or data provider, and how that compares with peers); an independently tested recovery-time objective for each AI-dependent service under adversarial, not benign, failure; and a tail gap, the distance between the firm's modelled expected cyber loss and its 95th-percentile loss, with capital sized to the latter. Each of these moves with the actual loss distribution; a maturity score does not. As Marco Maiurano of First Citizens Bank puts it in the panel, the variability and severity are now so drastic that single-point maturity scores carry little signal.
For investors and supervisors: replace narrative assurance with concrete tests. Investors should make vendor and model concentration a standard due-diligence item: which foundation models, cloud regions, and third-party data vendors does the firm depend on, and how many of its direct competitors share those dependencies? This is more than a checklist item: it is one of the few mechanisms through which correlated tail risk can become visible in prices at all. No single firm's disclosure can reveal that ten competitors depend on the same model or cloud region; only a party comparing across firms can see it. Concentration is therefore a classic collective-action problem that markets cannot solve unaided, which is the substantive case for supervisory concentration testing rather than another maturity questionnaire. Kun (2024) argues this is precisely the gap DORA's oversight regime for critical ICT third-party providers was designed to fill at the supervisory level. Supervisors, for their part, should test recovery credibly rather than accept qualitative reporting: Aldasoro et al. (2023) find that better supervisory quality is empirically associated with roughly 11% faster recognition of operational losses. Applied to AI-driven finance, this argues for system-wide cyber stress exercises and independent audits of recovery time objectives rather than another layer of disclosure.
Once the tail has shifted, continuing to govern cyber risk with pre-AI tools is itself a strategic choice. It shows up first in the cost of capital: Liu, Luo and Yawson (2025) document that attacked firms and their peers face measurably higher equity financing costs after incidents, and Jiang et al. (2024) show that firms with higher cyber risk exposure pay a persistent premium. As markets learn to price the post-AI tail, those premia may widen for institutions that cannot credibly demonstrate tail-sensitive governance. It shows up next in counterparty trust: firms that cannot show credible recovery metrics are likely to be dealt with on less favourable terms long before they are breached.
The competitive frontier in AI-driven finance is not "best security" in the traditional sense. It is lowest uncertainty around service continuity under fat-tailed, correlated disruption. On a calm day, that looks like a cost line. On a bad day, it looks like the only institutions still open for business.
The Arup deepfake was told as a fraud story. It was really a preview. The same mechanism, scaled up, reaches training pipelines, credit models, authentication layers, and cloud regions shared across the industry. Cyber risk in AI-driven finance is no longer a compliance sidebar. It is a tail-sensitive, liquidity-relevant, correlation-heavy financial variable whose distribution has moved, and whose new shape is not yet in prices, capital, or boardroom dashboards.
None of this requires waiting for the next major incident. The data already exist. The shift is documented, the propagation channels are mapped, the pricing gap is measurable, and the regulatory direction of travel, from DORA onward, is set. What is missing is the governance layer that turns those inputs into capital plans, stress tests, and disclosures calibrated to the post-AI tail rather than the pre-AI one.
That gap is not neutral to wait on. Repricing the post-AI tail is likely to be a source of advantage, and one that compounds over time. The evidence does not yet prove this directly, but it points in that direction. If markets already charge a premium for observable cyber exposure (Jiang et al., 2024; Liu, Luo and Yawson, 2025), an institution that quantifies its cyber-and-AI tail, sizes capital and liquidity to it, and can disclose it credibly should be well placed to fund itself more cheaply and to be dealt with on better terms, with savings that would accrue quarter after quarter. An institution that does not is not standing still; it is quietly accumulating an invisible liability, a hidden short position on the post-AI tail whose premium it collects in good quarters and whose true size it discovers only when the distribution moves against it. The longer the two paths run, the wider the distance between them. The hidden variable is unlikely to stay hidden forever, and when it surfaces, the firms that priced it early may well find themselves years ahead.
[1] CNN. (2024, February). Finance worker pays out $25 million after video call with deepfake ‘chief financial officer’. CNN.
[2] Surfshark Research. (2025, July). Deepfake fraud losses near $900 million by mid-2025. Surfshark, using data from the AI Incident Database and Resemble.AI.
[3] Eisenbach, T. M., Kovner, A., & Lee, M. J. (2022). Cyber risk and the U.S. financial system: A pre-mortem analysis. Journal of Financial Economics, 145(3), 802–826.
[4] Franco, M. F., Künzler, F., von der Assen, J., Feng, C., & Stiller, B. (2024). RCVaR: An economic approach to estimate cyberattacks costs using data from industry reports. Computers & Security, 139, 103737.
[5] Jiang, H., Khanna, N., Yang, Q., & Zhou, J. (2024). The Cyber Risk Premium. Management Science, 70(12), 8791–8817.
[6] Kun, E. (2024). Challenges in regulating cloud service providers in EU financial regulation: From operational to systemic risks, and examining challenges of the new oversight regime for critical cloud service providers under the Digital Operational Resilience Act. Computer Law & Security Review, 52, 105931.
[7] Liu, X., Luo, J., & Yawson, A. (2025). Equity offering following cyberattacks. Journal of Corporate Finance, 91, 102710.
[8] Yerlikaya, F. A., & Bahtiyar, Ş. (2022). Data poisoning attacks against machine learning algorithms. Expert Systems with Applications, 208, 118101.
[9] McKinsey & Company, Risk & Resilience Practice. (2025, August). Competitive advantage through cybersecurity: A board-level perspective.
[10] Bailey, T., Del Miglio, A., & Richter, W. (2014, May). The rising strategic risks of cyberattacks. McKinsey & Company.
[11] Aldasoro, I., Gambacorta, L., Giudici, P., & Leach, T. (2023). Operational and Cyber Risks in the Financial Sector. International Journal of Central Banking, 19(5), 341–402.
[12] Bank of England & Financial Conduct Authority. (2024, November). Artificial intelligence in UK financial services - 2024. Bank of England.
[Student IDEAS] by Hugo Jalet - Graduate of the Global BBA at ESSEC Business School
Artificial intelligence is fundamentally altering the statistical nature of cyber risk in finance, shifting it from an isolated, firm-specific operational threat into a correlated, fat-tailed financial variable. By moving attack vectors from network perimeters to training data and foundation models—and with high market concentration across a few cloud and AI providers—AI-driven threats introduce heavy-tailed loss severity, accelerated industry-wide propagation, and extended detection lags where malicious interventions hide as ordinary "model drift." Because existing financial pricing, capital buffers, and board governance remain calibrated to pre-AI historical data, institutions are running an unpriced tail risk that threatens equity financing, liquidity, and balance sheet stability; addressing this requires integrating cyber and AI governance, stress-testing for multi-day operational outages, and sizing capital against third-party concentration.
---
In early 2024, a finance employee at the British engineering firm Arup joined what looked like a routine video call with her chief financial officer (CFO) and several colleagues. By the end of it, she had authorised fifteen transfers totalling roughly $25 million to accounts in Hong Kong. Weeks later, the firm discovered that every participant on the call, CFO included, was a deepfake: a hyper-realistic fake video and voice, generated by artificial intelligence (AI), that impersonates a real person.1 The story made headlines for a few days, then faded. It should not have. By mid-2025, deepfake-enabled fraud alone had driven close to $900 million in reported losses globally, with more than $410 million concentrated in the first half of the year, already exceeding the total for all of 2024.2
The Arup incident is usually told as a story about weak verification protocols and the need for better employee training. That framing is not wrong, but it is far too narrow. Arup lost money on a single wire; the underlying phenomenon is something finance has not yet priced. Artificial intelligence is quietly reshaping what cyber risk looks like as a statistical object. Losses are becoming less idiosyncratic and more correlated, tails are fatter, detection is slower, and propagation across firms is faster, largely because banks, insurers, and asset managers increasingly share the same foundation models, training data, and cloud vendors.
This matters because finance has, for more than a decade, treated cyber as primarily an operational and compliance issue: a cost line, a maturity score, an audit-committee bullet. That mental model was already strained, and in an AI-driven system, it quietly breaks. Cyber resilience is no longer a sidebar; it is a financial variable whose distribution has shifted, and which neither markets nor most institutions have repriced. The practical question for boards, chief risk officers (CROs), and investors is therefore not "how much more should we spend on security?" but "how must we redesign governance, capital planning, and disclosure once the tail of cyber losses has moved?"
To see why the familiar playbook no longer fits, it is worth being precise about what is genuinely new.
The past decade of digital transformation in finance mostly expanded what cyber risk could affect: more systems online, more data in motion, more third parties in the chain. Artificial intelligence does something different. It shifts four properties of the loss distribution itself, and each of these shifts quietly erodes the "perimeter plus patch" mental model (the assumption that security means defending a network boundary with firewalls and access controls, then closing known software flaws with timely patches) that still governs most cyber budgets.
The attack surface moves from code and credentials to data and models. Classical cyber defence is organised around code, infrastructure, and identities: firewalls, segmentation, access controls, patch cycles. An AI system is a different object. It can be compromised by corrupting the training data itself, before a single credential is ever stolen. Yerlikaya and Bahtiyar (2022) show how quickly this matters. They study data poisoning, which means deliberately corrupting part of the training data, the data used to teach and build a model. Across four datasets (spam, botnet, malware, and medical diagnostics) and six standard algorithms, the researchers deliberately altered the correct classifications in a quarter of the training data (labelling spam as legitimate, for instance). This alone cut classification accuracy by 15 to 40 percentage points, and when half of the training data was corrupted, model performance collapsed in several configurations. Transposed to finance, this is a structurally new threat: a well-placed intervention in the training pipeline (the process that collects, prepares, and feeds data into a model while it is being built) of a credit-scoring model, a transaction-monitoring engine, or an algorithmic pricing system does not need to breach the firewall to cause losses.
These threats target two distinct stages in the life of an AI system. At training time, while the model is being built, data poisoning and training-set contamination corrupt what it learns. At inference time, when the trained model is being used to make real decisions, attackers exploit it through prompt injection (hiding malicious instructions in the text or data the model reads) and model manipulation (feeding it carefully crafted inputs, or tampering with the model itself, so that it produces the outputs the attacker wants). Both bypass the controls built for the old perimeter: neither needs to breach a firewall or steal a credential, because the vulnerability lives in the data and the model itself, not at the network boundary. They now sit beside ransomware and phishing on the threat list.
Detection lag lengthens because model failure looks like drift. Traditional cyber incidents are largely binary. A system is down, an account is drained, a file is encrypted. AI failures are probabilistic. A poisoned fraud model does not stop working; it simply scores certain transactions a little more leniently. A manipulated credit model does not crash; it tilts approvals in a subtle direction. These incidents are easily reinterpreted as "model drift", an accepted, almost decorative feature of machine-learning (ML) models in production. The result is that the time between occurrence, discovery, and recognition stretches. Even without AI, the problem is already acute: using cross-country operational-loss data from seventy banks over sixteen years, Aldasoro et al. (2023) document an average lag of more than a year between when an operational loss occurs and when it is finally booked (formally recorded as a loss in the accounts), with a long-tailed distribution in which a meaningful share of events remain unaccounted for after two years. Layer on the probabilistic opacity of AI systems and one should expect that distribution to stretch further, not tighten. For capital and liquidity planning, the implication is unpleasant: by the time a model-level compromise is formally recognised, much of its damage may already have been absorbed into the balance sheet.
Timeline of an operational loss event. Source: Aldasoro et al. (2023). Three dates structure every loss event: occurrence, discovery, and recognition. AI-driven incidents stretch t₁ (occurrence → discovery) because probabilistic failures resemble model drift.
Propagation accelerates through shared models, shared data, and concentrated cloud providers. The novelty is blunt: banks, insurers, and asset managers no longer need to do business with each other to share cyber exposure; they only need to rely on the same foundation model, the same training corpus, or the same hyperscale cloud provider, so a single compromise can reach firms with no direct contractual link. This is a different transmission channel from the one finance is used to.
In the pre-AI cyber world, contagion travelled mainly through explicit economic linkages: interbank exposures, counterparty relationships, payment networks. The pre-mortem analysis of Fedwire by Eisenbach, Kovner and Lee (2022) already showed how powerful that channel alone could be. The impairment of any one of the five largest U.S. banks spills over to an average of 38% of the network. A shock concentrated on a single third-party service provider common to several large institutions does even more damage: it pushes the weighted share of impaired institutions to roughly 60%, with potential forgone payment activity reaching more than 2.5 times daily gross domestic product (GDP) once banks start hoarding liquidity.
That shared layer is no longer hypothetical. In the 2024 survey by the Bank of England and the Financial Conduct Authority (FCA), 75% of UK financial firms reported already using AI, up from 58% two years earlier, though adoption remains uneven: many firms are still standing up data pipelines or running a general-purpose chat assistant for back-office work, while a smaller set already embeds foundation models directly into credit, fraud, and trading decisions. Foundation models account for 17% of all use cases, and a third of use cases now run on third-party implementations (Bank of England and FCA, 2024).
That third-party supply is strikingly concentrated: the three most-cited providers account for 73% of all named cloud providers, 44% of model providers, and 33% of data providers. Concentration on that scale means many institutions are exposed, without any direct link to one another, to the same handful of upstream failures, which is why the same survey ranks cybersecurity as the highest perceived systemic risk and critical third-party dependencies as the fastest-growing one. This is precisely the concern the EU's Digital Operational Resilience Act (DORA) attempts to address through its oversight regime for "critical" third-party information and communication technology (ICT) providers, which formally recognises for the first time that cloud and model concentration is a systemic variable, not a purely commercial one (Kun, 2024).
The figure shows the distribution of the network impact for the scenario with a disruption originating from a third-party service provider. “Share” represents the unweighted percent of institutions that become impaired. “Weighted share” represents the percent of institutions that become impaired, weighted by asset size. “Net weighted share” refers to the percent of institutions that become impaired, net of the shocked institutions.
Loss tails fatten because one compromise now hits many pipelines at once. The combination of the first three shifts has a direct statistical consequence: the severity distribution of cyber losses becomes heavier in the right tail. If a single poisoned dataset or compromised model feeds credit decisioning, fraud scoring, and trading signals across multiple institutions, a single event generates correlated losses across several profit-and-loss (P&L) lines and several firms simultaneously. Aldasoro et al. (2023) already find that although cyber events are still rare relative to other operational losses, cyber risk can account for up to a third of a bank's total operational value-at-risk, with most of that contribution concentrated in the tail. A 2025 panel of chief information security officers (CISOs) and board directors convened by McKinsey and the National Association of Corporate Directors (NACD) captures the shift in blunt terms, with one participant noting that under AI-fuelled threats, the "variability and severity are so drastic" that traditional maturity scores carry little signal (McKinsey & Company, 2025).
Taken together, these four shifts describe a cyber risk that is less idiosyncratic, less binary, more correlated across firms, and slower to surface than the one the industry has built tools for. The governance model inherited from the last decade (a CISO who patches systems, an audit committee that tracks maturity scores, and an insurer who prices firm-level history) was not designed for this object. The question is what happens once this new distribution is properly recognised, first in prices and capital, then in governance and disclosure.
A shift in the cyber loss distribution only matters financially to the extent that it travels into the numbers that boards, creditors, and markets actually look at. And on current evidence, much of that journey has not yet happened.
Inside the firm. The most visible channel is the earnings hit. Operational losses from remediation, incident response, customer notification, legal fees, and regulatory fines feed directly into quarterly results. Using a cross-country panel of roughly seventy large banks over sixteen years, Aldasoro et al. (2023) estimate that operational risk capital varies between 1% and 7.5% of gross income depending on the calibration method used, and that cyber-specific capital can account for up to a third of that total. Franco et al. (2024) argue that even those figures underestimate firm-level exposure for the median institution because they remain rooted in probability-based simulations rather than observed real-world loss data; their Real Cyber Value at Risk (RCVaR) framework is designed precisely to close that gap by estimating costs directly from industry incident reports.
A second channel is the balance sheet. Remediation spending, accelerated information-technology investments, and litigation reserves erode capital buffers over the quarters that follow an incident, which changes how firms finance themselves. Liu, Luo & Yawson (2025), using a U.S. sample running from 2005 to 2019, find that attacked firms become 56% to 61% less likely than matched non-attacked firms to undertake a seasoned equity offering (SEO), that is, a new share issue by an already-listed company, over the three years after the attack, with SEO proceeds dropping in parallel. The mechanism they document is not a shortage of capital need but an excess of capital cost: reputation loss raises the adverse-selection premium that equity investors demand, and firms rationally shrink their equity issuance. The effect also spills over to industry peers who were not themselves attacked, whose SEO probability falls by roughly 18% to 20% of its baseline and whose SEO proceeds decline by about 13.5%, suggesting that markets treat a single cyber event as information about a sector's underlying cyber risk, not just about the target firm.
The third and most underappreciated channel is liquidity. Eisenbach, Kovner & Lee (2022) show that a successful cyber attack on any one of the top-5 U.S. wholesale payment banks impairs on average 38% of the network, and that once uninfected banks begin hoarding liquidity defensively, forgone payment activity can reach more than 2.5 times daily GDP within a few days. This matters particularly in AI-driven finance because authentication, payments, trade settlement and fraud routing all increasingly depend on ML-based systems. A model-level compromise does not only hit the targeted firm's P&L; it can disable a counterparty's ability to send or receive, which is a classical liquidity event wearing an AI costume. What looks operational becomes financial the moment confidence in settlement is shaken.
The figure shows the distribution of aggregate liquidity shortfall resulting from an attack that lasts from 1 to 5 days, averaged across the top-5 scenarios.
In markets. Do equity and credit markets price any of this? Partially. The existence of a cyber risk premium is by now empirically documented: firms with higher cyber exposure trade at a discount and face measurably higher costs of external financing after incidents (Jiang et al., 2024; Liu, Luo & Yawson, 2025). But the size of that premium is calibrated to the pre-AI tail. It reflects the historical distribution of cyber events as rare, largely firm-specific, and usually reversed within a few quarters. It does not yet reflect the four shifts described above: correlated incidents across firms that share a foundation model or a cloud region, slow-maturing damage from poisoned training sets, and losses that simultaneously hit credit decisioning, fraud scoring, and trading signals. The useful question is therefore not "is cyber risk priced?", but "is the post-AI tail priced?". On current evidence the answer is largely no.
Why not? Four structural frictions keep the post-AI tail out of prices.
Opacity. Cyber events are systematically under-reported. Aldasoro et al. (2023) document an average lag of more than a year between the occurrence of an operational loss and its recognition on the balance sheet, with a meaningful share of events still unaccounted for after two years. Markets cannot price what they cannot see, and as long as AI-related incidents hide inside "model drift" or "performance degradation", the signal does not reach them.
Externalities. Vendor and model concentration is a public bad. An institution that chooses a hyperscale cloud provider or a dominant foundation model captures private benefits (cost, performance, speed) but imposes a systemic risk that its own funding spread does not internalize. Kun (2024) argues that this is exactly the gap DORA's oversight regime for critical ICT providers was introduced to fill: firm-level risk management cannot price a shared-infrastructure externality, which is why a public authority has to look at concentration directly.
Rare-event neglect. Fat-tailed distributions are hard to estimate from short histories, especially when the underlying generating process has recently changed. The pre-AI cyber loss series is neither long enough nor stationary enough to calibrate a post-AI tail, and market participants (like most people) tend to under-weight tail risks they have not personally lived through.
Correlation blindness. Markets price firms, not shared-infrastructure clusters. There is no traded instrument whose payoff depends on whether ten banks share the same credit-scoring model, the same transaction-monitoring vendor, or the same cloud region. Until such an instrument exists, or until supervisors require concentration disclosure, correlated tail risk remains diversified on paper but concentrated in reality, which is the worst of both worlds for holders of the equity and debt of such firms.
The cumulative effect of these four frictions is that funding spreads, valuation multiples, and cyber insurance pricing continue to reflect a distribution that has already moved. Institutions whose capital planning, liquidity stress tests, and board-level risk dashboards rest on those same prices are therefore running a hidden short position on the post-AI tail. The rest of the article asks what changes (in governance, in disclosure, and in the practical work of CROs, CFOs, boards, and investors) once that short position is properly acknowledged.
If the post-AI tail is not yet in prices, the governance question is where the adjustment should come from. No single actor can close the gap: CROs and CFOs need to rebuild the quantitative plumbing, boards need to govern AI and cyber as one integrated risk, and investors and supervisors need to replace narrative assurance with credible tests. Institutions that move first stand to gain more than safety: the evidence discussed above suggests they may also fund themselves more cheaply and earn greater counterparty trust.
For CROs and CFOs: rebuild the quantitative plumbing. Three moves matter. First, model cyber losses at the tail, not at the mean. Franco et al. (2024) argue explicitly that most existing cyber capital models remain rooted in probability-based simulations calibrated on thin historical samples, exactly the wrong posture when the generating process has changed; their RCVaR framework estimates costs from observed industry data and makes the gap between expected loss and the 95th percentile explicit. Aldasoro et al. (2023) provide an independent benchmark: operational risk capital varies between 1% and 7.5% of gross income depending on calibration, with cyber-specific capital reaching a third of that. A capital plan sitting near the lower bound of those ranges is making an implicit bet that the post-AI tail will look like the pre-AI one.
Second, add authentication and payment outages to liquidity stress tests. Eisenbach, Kovner and Lee (2022) show that a five-day payment impairment at one of the five largest U.S. banks produces aggregate system liquidity shortfalls rising from roughly $122 billion on day one to around $1 trillion by day five, and that at the individual-bank level the 95th-percentile shortfall can reach 5% of risk-weighted assets or 37% of tier-1 capital.
Distribution of liquidity shortfall across impaired banks, relative to risk-weighted assets (left) and tier-1 capital (right). Source: Eisenbach, Kovner & Lee (2022). The tail is long: at the 95th percentile, shortfalls reach roughly 5% of risk-weighted assets and 37% of tier-1 capital. Capital buffers calibrated to the mean of this distribution leave the firm materially exposed to the tail.
Most internal liquidity frameworks still do not include a scenario in which the firm's ability to authenticate customers or send payments is disabled for several business days. Adding such scenarios, and sizing contingent buffers accordingly, is the single most concrete change a CFO can make.
Third, calibrate capital buffers to vendor concentration, not only firm-level history. The Bank of England's 2020 survey, cited by Kun (2024), finds that over 70% of U.K. banks and 80% of insurers use only two cloud providers for infrastructure services. Eisenbach et al. (2022) quantify the systemic side: a shock to a third-party service provider common to several large institutions impairs roughly 60% of the network by assets. CROs therefore need a vendor-concentration metric that feeds directly into capital buffer sizing, alongside a single risk register integrating model, data, and infrastructure exposures.
What makes such a test different from current ones is the unit of analysis. A conventional stress test breaches one firm at a time; a vendor-concentration test shocks the shared provider, not the firm, and asks how much of the book fails with it. In practice, it maps each critical AI dependency (foundation model, cloud region, data vendor) to the lines of business that rely on it, and identifies where the same provider silently underpins supposedly independent functions such as credit scoring, fraud detection, and trading. It then measures the correlated loss when that one provider goes down, and sets it against how many direct competitors share the same dependency. Given that three providers already account for the bulk of cloud and model relationships, those overlaps are the rule, not the exception.
For boards: govern AI and cyber as one integrated risk. The McKinsey and NACD (2025) panel of CISOs and directors is blunt that "the era when cybersecurity was a separate, isolated function at organizations is over" and that AI-fuelled threats require what one panellist calls "air-to-ground coverage" across the institution. In practice, this means moving cyber out of the audit-committee sidebar into a standalone risk or technology committee with genuine technical fluency, and changing the metrics boards track. Generic maturity scores were designed for a world where cyber was firm-specific and procedural; they do not capture the post-AI tail. The metrics that do are operational: credible recovery time objectives for AI-dependent services under adversarial conditions, vendor and model-concentration exposure, and the credibility of the firm's scenario library. Concretely, a post-AI tail metric is not a maturity score but a small set of tail-sensitive quantities tracked over time: a concentration ratio (the share of AI-dependent critical services running on the firm's single largest external model, cloud, or data provider, and how that compares with peers); an independently tested recovery-time objective for each AI-dependent service under adversarial, not benign, failure; and a tail gap, the distance between the firm's modelled expected cyber loss and its 95th-percentile loss, with capital sized to the latter. Each of these moves with the actual loss distribution; a maturity score does not. As Marco Maiurano of First Citizens Bank puts it in the panel, the variability and severity are now so drastic that single-point maturity scores carry little signal.
For investors and supervisors: replace narrative assurance with concrete tests. Investors should make vendor and model concentration a standard due-diligence item: which foundation models, cloud regions, and third-party data vendors does the firm depend on, and how many of its direct competitors share those dependencies? This is more than a checklist item: it is one of the few mechanisms through which correlated tail risk can become visible in prices at all. No single firm's disclosure can reveal that ten competitors depend on the same model or cloud region; only a party comparing across firms can see it. Concentration is therefore a classic collective-action problem that markets cannot solve unaided, which is the substantive case for supervisory concentration testing rather than another maturity questionnaire. Kun (2024) argues this is precisely the gap DORA's oversight regime for critical ICT third-party providers was designed to fill at the supervisory level. Supervisors, for their part, should test recovery credibly rather than accept qualitative reporting: Aldasoro et al. (2023) find that better supervisory quality is empirically associated with roughly 11% faster recognition of operational losses. Applied to AI-driven finance, this argues for system-wide cyber stress exercises and independent audits of recovery time objectives rather than another layer of disclosure.
Once the tail has shifted, continuing to govern cyber risk with pre-AI tools is itself a strategic choice. It shows up first in the cost of capital: Liu, Luo and Yawson (2025) document that attacked firms and their peers face measurably higher equity financing costs after incidents, and Jiang et al. (2024) show that firms with higher cyber risk exposure pay a persistent premium. As markets learn to price the post-AI tail, those premia may widen for institutions that cannot credibly demonstrate tail-sensitive governance. It shows up next in counterparty trust: firms that cannot show credible recovery metrics are likely to be dealt with on less favourable terms long before they are breached.
The competitive frontier in AI-driven finance is not "best security" in the traditional sense. It is lowest uncertainty around service continuity under fat-tailed, correlated disruption. On a calm day, that looks like a cost line. On a bad day, it looks like the only institutions still open for business.
The Arup deepfake was told as a fraud story. It was really a preview. The same mechanism, scaled up, reaches training pipelines, credit models, authentication layers, and cloud regions shared across the industry. Cyber risk in AI-driven finance is no longer a compliance sidebar. It is a tail-sensitive, liquidity-relevant, correlation-heavy financial variable whose distribution has moved, and whose new shape is not yet in prices, capital, or boardroom dashboards.
None of this requires waiting for the next major incident. The data already exist. The shift is documented, the propagation channels are mapped, the pricing gap is measurable, and the regulatory direction of travel, from DORA onward, is set. What is missing is the governance layer that turns those inputs into capital plans, stress tests, and disclosures calibrated to the post-AI tail rather than the pre-AI one.
That gap is not neutral to wait on. Repricing the post-AI tail is likely to be a source of advantage, and one that compounds over time. The evidence does not yet prove this directly, but it points in that direction. If markets already charge a premium for observable cyber exposure (Jiang et al., 2024; Liu, Luo and Yawson, 2025), an institution that quantifies its cyber-and-AI tail, sizes capital and liquidity to it, and can disclose it credibly should be well placed to fund itself more cheaply and to be dealt with on better terms, with savings that would accrue quarter after quarter. An institution that does not is not standing still; it is quietly accumulating an invisible liability, a hidden short position on the post-AI tail whose premium it collects in good quarters and whose true size it discovers only when the distribution moves against it. The longer the two paths run, the wider the distance between them. The hidden variable is unlikely to stay hidden forever, and when it surfaces, the firms that priced it early may well find themselves years ahead.
[1] CNN. (2024, February). Finance worker pays out $25 million after video call with deepfake ‘chief financial officer’. CNN.
[2] Surfshark Research. (2025, July). Deepfake fraud losses near $900 million by mid-2025. Surfshark, using data from the AI Incident Database and Resemble.AI.
[3] Eisenbach, T. M., Kovner, A., & Lee, M. J. (2022). Cyber risk and the U.S. financial system: A pre-mortem analysis. Journal of Financial Economics, 145(3), 802–826.
[4] Franco, M. F., Künzler, F., von der Assen, J., Feng, C., & Stiller, B. (2024). RCVaR: An economic approach to estimate cyberattacks costs using data from industry reports. Computers & Security, 139, 103737.
[5] Jiang, H., Khanna, N., Yang, Q., & Zhou, J. (2024). The Cyber Risk Premium. Management Science, 70(12), 8791–8817.
[6] Kun, E. (2024). Challenges in regulating cloud service providers in EU financial regulation: From operational to systemic risks, and examining challenges of the new oversight regime for critical cloud service providers under the Digital Operational Resilience Act. Computer Law & Security Review, 52, 105931.
[7] Liu, X., Luo, J., & Yawson, A. (2025). Equity offering following cyberattacks. Journal of Corporate Finance, 91, 102710.
[8] Yerlikaya, F. A., & Bahtiyar, Ş. (2022). Data poisoning attacks against machine learning algorithms. Expert Systems with Applications, 208, 118101.
[9] McKinsey & Company, Risk & Resilience Practice. (2025, August). Competitive advantage through cybersecurity: A board-level perspective.
[10] Bailey, T., Del Miglio, A., & Richter, W. (2014, May). The rising strategic risks of cyberattacks. McKinsey & Company.
[11] Aldasoro, I., Gambacorta, L., Giudici, P., & Leach, T. (2023). Operational and Cyber Risks in the Financial Sector. International Journal of Central Banking, 19(5), 341–402.
[12] Bank of England & Financial Conduct Authority. (2024, November). Artificial intelligence in UK financial services - 2024. Bank of England.
[Student IDEAS] by Chirag Patel - MSc in Hospitality Management (IMHI) at ESSEC Business School
Digital transformation in hospitality is rapidly shifting from operational efficiency to experience design. While the industry has traditionally viewed technology as a means to automate processes or cut costs, upscale and lifestyle hotels are pioneering a new paradigm: using digital touchpoints to orchestrate emotional flows across the guest journey. Focusing on three critical phases—booking, arrival, and in-stay—this article explores how thoughtful digital integration eliminates friction, empowers autonomy, and turns routine service moments into lasting brand value. Through real-world case studies including CitizenM, The Hoxton, and Mama Shelter, we examine how technology can complement rather than replace human care, transforming digital touchpoints into the primary sites of modern hospitality.
---
The hospitality industry is undergoing a structural transformation driven by the rapid integration of digital technologies across the guest journey. Travellers today are getting influenced by content on social platforms to choose the destinations and hotels they want to visit. 94% of industry executives have cited mobile traffic as the most important acquisition channel1, signalling that the guest journey increasingly begins within algorithm-driven and mobile-first digital ecosystems rather than through traditional hotel discovery pathways. However, digital discovery does not erase the inherent value of physical location. Prime locations, exceptional views, and transport connectivity remain enduring sources of competitive advantage, which technology can amplify. Over the past decade, the proliferation of mobile applications, contactless interfaces, messaging platforms, and data-driven personalisation tools has fundamentally reshaped how guests interact with hotel brands. What was once a predominantly physical and human-led service environment is now increasingly mediated through digital touchpoints that influence perception, decision-making, and experience even before a guest sets foot on property. Industry reports highlight this shift clearly. Digital maturity in hospitality is no longer a differentiator but a baseline expectation, particularly among younger and more design-conscious travellers.
Despite this evolution, much of the industry continues to frame technology primarily as an operational tool aimed at productivity gains, cost reduction, or labour replacement. This perspective often overlooks the experiential dimension of digital interactions and reinforces a mutually exclusive narrative between high-tech and high-touch service. As of 2025, only 3% of customer data is fully integrated2, highlighting a major contradiction within hospitality digitalisation: while hotels increasingly interact with guests across multiple digital touchpoints, most still lack the unified data ecosystems required to create genuinely coherent personalised journeys. However, emerging evidence suggests that digital interfaces can play a far more nuanced role by shaping emotional states, reducing friction, and enabling a sense of control and reassurance throughout the guest journey. This calls for a reframing of digital tools not as peripheral systems, but as central components of experience design.
To understand this shift, it is useful to introduce the concept of critical moments within the guest journey3. These are specific phases where guest expectations are heightened and emotional responses are particularly sensitive to service design. This article focuses on three such moments: booking, arrival, and in-stay4. Unlike routine service interactions, critical moments disproportionately shape how guests remember and evaluate an entire stay. These moments often involve emotional vulnerability, uncertainty, anticipation, or heightened expectations, making them particularly influential in forming brand perception and emotional attachment. Predominantly, the booking phase is characterised by anticipation, trust formation, and a need for reassurance. Guests evaluate not only price and product but also credibility, clarity, and convenience. The arrival moment introduces a different emotional dynamic, often involving uncertainty, fatigue, and a desire for orientation and recognition. The in-stay phase shifts towards comfort, autonomy, and responsiveness, where guests seek both control over their experience and timely support when needed. Across these moments, the design of digital touchpoints can either ease or amplify friction, directly influencing guests’ experience. Today, we have the advantage of pre-determining the emotional responses in each phase.
This article argues that upscale and lifestyle hotels are moving from managing operational touchpoints to orchestrating emotional flows across the guest journey, where digital interactions increasingly function as invisible yet primary sites of hospitality. Unlike luxury hotels, where human interaction remains the dominant signal of service quality, or midscale properties where efficiency often takes precedence, upscale and lifestyle hotels operate within a hybrid expectation space. Guests in this segment value aesthetic elements, speed, and autonomy alongside true engagement. As a result, digital interfaces are not just supportive tools but integral elements of brand positioning and guest experience.
Traditionally, digital technologies are viewed as operational facilitators in the hospitality industry. Much of the prevailing research continues to frame technology as a set of tools deployed to improve operational efficiency, reduce labour dependency, or automate repetitive processes. While these outcomes are important, this narrow framing underestimates the broader transformation underway and obscures the role of digital systems as active shapers of the guest experience. Technology, in its fuller sense, is not merely a collection of tools but a combination of systems, processes, and organisational practices that evolve together. The industry also tends to approach digital transformation as a linear enhancement of existing processes rather than a reconfiguration of the guest journey. For example, mobile check-in is often implemented as a digital replication of the front desk, rather than an opportunity to rethink the arrival experience entirely. This reflects a broader pattern where technology is layered onto existing service models instead of being used to redesign them.
The emergence of agentic AI, systems capable of autonomously making recommendations, comparisons, and travel decisions on behalf of users, signals a structural shift in how guests discover and interact with hospitality brands. Rather than travellers actively browsing hotel websites or online travel agencies, AI-driven assistants may increasingly curate options, personalise itineraries, and even make booking decisions based on behavioural preferences and contextual data. This changes the role of digital touchpoints fundamentally. Hotels are no longer designing only for direct human interaction, but also for algorithmic visibility and machine-readable experiences. In this context, digital touchpoints become critical not only for guest engagement, but also for how brands are interpreted, prioritised, and recommended within emerging AI-driven travel ecosystems.
Interactions during a hotel stay are not experienced as a continuous flow, but as a series of emotional spikes and transitions, starting from booking till post-stay. It is within these fragmented moments that perception is formed, expectations are tested, and brand meaning is embraced.
The booking stage is primarily defined by anticipation, reassurance, and trust formation. At this point, the guest has not yet experienced the physical product and relies entirely on mediated representations of the brand through websites, platforms, reviews, and content. The emotional state is forward-looking but fragile. Guests seek clarity, credibility, and confidence in their decision. Any friction in navigation, ambiguity in information, or inconsistency in messaging can introduce doubt and increase the likelihood of abandonment. Conversely, a well-designed booking experience can heighten anticipation and establish an early emotional connection with the brand.
The arrival moment marks a transition from expectation to reality and is often characterised by anxiety, fatigue, and a need for orientation. Guests may be navigating an unfamiliar environment, managing time pressure, or arriving after long journeys. At this stage, the desire for recognition and ease becomes central. The guest is subconsciously assessing whether the hotel understands their needs and whether the experience aligns with prior expectations. Small frictions such as waiting time, unclear processes, or lack of guidance can disproportionately impact perception. Equally, moments of smooth transition, intuitive navigation, and personalised acknowledgement can create immediate reassurance and a sense of belonging.
The in-stay phase shifts towards comfort, autonomy, and responsiveness. Once settled, guests seek to exercise control over their environment while expecting seamless access to services. The emotional expectation evolves from reassurance to empowerment. Guests want to personalise their experience, make requests effortlessly, and receive timely responses without unnecessary effort. Interruptions, delays, or rigid service structures can disrupt this sense of comfort, while intuitive systems and responsive service enhance perceived quality and satisfaction.
In upscale and lifestyle segments, where differentiation is often subtle and brand identity plays a central role, the design of these moments becomes a strategic lever for positioning and loyalty creation. What differentiates upscale and lifestyle hotels is not the presence of technology, but how intentionally it is used to choreograph emotion, identity, and control across the journey. In these segments, technology must move beyond convenience to become a subtle curator of experience.
For guests booking a lifestyle hotel, it is less about selecting a room and more about expressing a travel identity. Guests are not simply comparing price points but aligning themselves with a brand’s aesthetic, social energy, and cultural positioning. Technology, therefore, can move beyond filters and sorting logic to enable more interpretive and immersive pathways.
Instead of asking “What room do you want?”, digital interfaces can explore “What kind of stay are you seeking?” by translating intent into curated options. This could include mood-led journeys, socially driven recommendations, or even time-sensitive narratives that reflect what is happening in and around the hotel. In doing so, technology reduces the cognitive burden of choice while strengthening emotional alignment with the brand.
More uniquely, booking can become socially embedded. Integrations with social media platforms and review ecosystems can allow guests to see how others experience the property in real time, making the decision feel less isolated and more participative.
Arrival is often treated as a logistical checkpoint, yet in reality it is the first physical validation of the brand promise. In upscale and lifestyle hotels, where design and atmosphere are central, technology can be used to choreograph this transition rather than manage it.
Instead of focusing on speed alone, technology can shape the rhythm of arrival. For example, staggered digital arrivals, pre-configured room readiness, or adaptive queuing systems can eliminate the sense of crowding or waiting without removing human presence.
A more distinctive approach lies in “soft recognition” where guests feel acknowledged without explicit formalities. Subtle cues such as personalised in-room readiness, curated welcome content, or context-aware notifications can replace traditional check-in rituals. The role of staff then shifts from gatekeepers of process to enhancers of experience, engaging where it adds emotional value rather than operational necessity. Yet the pursuit of frictionless arrival also has its limits, as technologies such as facial recognition raise questions around privacy, consent, and regulatory acceptance.
During the stay, the expectation in this segment is not constant service, but the ability to shape one’s own experience fluidly. Technology can enable this by acting as an underlying layer that adjusts to guest behaviour rather than requiring active management.
Rather than offering a menu of services, digital systems can modulate the experience in real time. This could include dynamically adjusting recommendations based on time of day, guest movement, or past interactions, or enabling seamless transitions between work, leisure, and social engagement within the same space.
Importantly, technology can also redefine responsiveness. Instead of guests needing to initiate requests, systems can anticipate moments where intervention may be needed, while still preserving a sense of control. In lifestyle hotels especially, where guests value independence, this balance between anticipation and non-intrusion becomes critical.
The ongoing debate in hospitality has often centred on how much technology should be integrated into the guest experience, positioning digital and human interaction as competing forces. Technology, when applied thoughtfully, can play a pivotal role in shaping the critical moments by complementing rather than replacing human interaction. Taken together, the strategic integration of digital and human touchpoints across these critical moments allows hotels to move beyond the traditional high-tech versus high-touch dichotomy.
The critical question is not the quantity of technology deployed, but the precision with which it is applied across the guest journey. Technology becomes a means of enhancing emotional experience, reducing friction, and enabling a more coherent and responsive guest journey. In the upscale and lifestyle hotels, this often means making technology less visible, more contextual, and deeply aligned with the brand’s identity and rhythm. This often translates into highly specific, context-driven applications. For instance, instead of generic pre-arrival emails, guests may receive dynamically curated city guides aligned with their travel intent or previous behaviour, creating a sense of relevance before arrival. During arrival, rather than a standard digital check-in, room readiness notifications paired with personalised pathways, such as directing a guest straight to a rooftop bar or lounge before accessing their room, can reshape first impressions.
Today, guests do not experience hotel technology in isolation, but in comparison to the digital ecosystems they engage with daily, from streaming platforms to ride-hailing apps and social media. As a result, hospitality brands must redesign the guest journey not as a series of one-way digital offerings, but as an extension of these existing habits and expectations. The opportunity lies in embedding technology into natural guest behaviours rather than asking guests to adapt to new systems. This also brings renewed relevance to previously overlooked or “dead” touchpoints. Elements such as Wi-Fi login pages, in-room TVs, QR codes, digital signage, or even elevator screens can evolve into meaningful micro-moments of engagement, whether through personalised recommendations, contextual storytelling, or real-time service access. In this approach, value is in embedding technology where it naturally enhances flow, relevance, and discovery.
In upscale and lifestyle contexts, guests do not necessarily perceive digital convenience and emotional care as contradictory. A seamless arrival, intuitive recommendation, or context-aware interaction can generate feelings of attentiveness and comfort traditionally associated with human service. The question therefore is no longer whether technology reduces hospitality, but whether digital experiences themselves can become a new expression of hospitality.
CitizenM has positioned digital interaction at the centre of its guest journey by designing around speed, autonomy, and minimal friction. Self check-in kiosks replace the traditional reception-heavy arrival process, while guests can control room features such as lighting, blinds, and entertainment through integrated digital systems. Rather than using technology as an add-on, CitizenM redesigns the experience around independent travellers who value efficiency and flexibility. The result is a hospitality model where technology supports comfort and control without removing the social energy of shared spaces.
The Hoxton adopts a more understated approach to digital hospitality by using technology to facilitate local immersion and convenience rather than overt automation. They enhanced the pre-arrival touchpoint by including curated neighbourhood recommendations and culturally relevant content that extends the experience beyond the hotel itself. Messaging platforms and seamless booking interfaces reduce formality while maintaining responsiveness. In this model, technology quietly supports the brand’s emphasis on locality, creativity, and informal hospitality without becoming the focal point of the experience.
Mama Shelter blends digital interaction with a socially vibrant and informal hospitality model. Guests interact with playlists, live events, nightlife programming, and food experiences through social media and mobile-first communication before and during the stay. Technology supports the brand’s community-oriented positioning rather than acting purely as a service utility.
Ace Hotel differentiates itself by integrating cultural programming directly into the digital discovery and booking journey. Guests often engage first with playlists, events, artist collaborations, or community content before interacting with the room product itself. In this case, booking becomes linked to participation in a cultural ecosystem rather than simply purchasing accommodation.
As this article has demonstrated, the most meaningful opportunities for digital transformation in upscale and lifestyle hotels lie not in maximising automation, but in intentionally redesigning critical moments where emotions, expectations, and perceptions are most heightened. Booking, arrival, and in-stay interactions each carry distinct emotional dynamics, requiring different balances of convenience, reassurance, autonomy, and human connection.
In upscale and lifestyle segments especially, where guests increasingly seek fluidity, individuality, and culturally relevant experiences, technology becomes most valuable when it is embedded subtly into the rhythm of the stay. Whether through personalised discovery pathways, frictionless arrivals, or context-aware in-stay interactions, the role of technology is shifting from visible functionality towards invisible orchestration. In doing so, hospitality is gradually moving from a model built around fixed physical touchpoints towards one shaped by dynamic and digitally mediated interactions. Simultaneously, entirely new touchpoints are emerging through Wi-Fi portals, messaging interfaces, algorithmic recommendations, social media engagement, and app-based interactions that previously held little relevance within the guest journey.
Beyond guest satisfaction, the quality of the digital journey can also influence the economic performance of the hotel. By reducing booking friction, strengthening direct relationships and encouraging repeat behaviour, well-designed digital touchpoints can contribute to customer lifetime value, Average Daily Rates (ADR) and, ultimately, the Net Operating Income (NOI) of the hotel asset. This positions digital guest journey design not only as a service, marketing or technology decision, but as a broader commercial and asset-management consideration.
As guest behaviour becomes increasingly shaped by mobile ecosystems, algorithmic discovery, and digitally conditioned expectations, hotels may need to rethink not only service delivery but the very architecture of the guest journey itself. The future competitive advantage of hospitality brands may therefore lie less in the visible performance of service, and more in their ability to quietly remove friction, anticipate behaviour, and create experiences that guests barely need to think about, yet distinctly remember. In this evolving landscape, an important question remains: as hospitality shifts from managing stays to designing emotional flows across journeys, will guests ultimately redefine what they perceive as service and care?
[1] Adobe: State of customer experience in travel and hospitality in an AI-driven world, business.adobe.com, 2025. Available at: https://business.adobe.com/assets/pdfs/resources/sdk/state-of-cx-travel-hospitality/state-of-customer-experience-in-travel-hospitality-in-an-ai-driven-world.pdf
[2] Ibid.
[3] Sanmartín Antolín G. Interactions and touchpoints along the hotel guest journey: an approach to experience management. Ara: Journal of Tourism Research. 2024;14(1):38-59. doi:10.1344/ara.v14i1.45870
[4] Lemon KN, Verhoef PC. Understanding customer experience throughout the customer journey. Journal of Marketing. 2016;80(6):69-96. doi:10.1509/jm.15.0420
[Student IDEAS] by Dan Xiao - Master in Management at ESSEC Business School
As Big Tech dominates foundation models, software is shifting to the application layer with Systems of Action (SOA)—autonomous software that targets global professional labor spend by executing end-to-end outcomes. Led by capital-efficient second movers, vertical AI startups are building defensible moats through a four-step execution stack: cost-optimized model routing, proprietary Retrieval-Augmented Generation (RAG), agentic workflows, and outcome-based pricing. By turning regulatory compliance like the EU AI Act into trust barriers and mastering deep domain edge cases, specialized application-layer platforms are redefining value capture beyond brute-force compute.
---
As Big Tech bundles good enough AI into every existing seat, how can a software startup survive the gravity of the giants?
The answer is simple: if you are still using AI just to draft emails or fix typos, you are missing the forest for the trees. While the masses use AI for these simple tasks, a fundamental transition is occurring in the corporate world: the narrative of AI is shifting from what it says to what it does. We are witnessing a fundamental transition: the focus is moving from the Foundational Layer to the Application Layer. In this new era, AI is reshaping the very concept of SaaS (Software as a Service), shifting the value proposition from managing data to executing outcomes.
Let’s review how SaaS has evolved1.
As highlighted in NEA’s 2025 analysis2, while traditional SaaS captures a share of the $500 billion enterprise software sector, AI “Systems of Action” are now targeting the $11 trillion global professional services labor spend.
The disruption is both localized and surgical. A group of second-mover3 startups are quietly dominating entire industries with narrow, high-margin AI services, intentionally avoiding the massive capital demands of the model race. While this efficiency movement is global, European founders have emerged as its primary architects. They are turning the EU AI Act4 into a form of regulatory sovereignty, creating a home-field advantage in high-stakes sectors where trust is currency.
According to a recent report by Goldman Sachs5 US giants are bleeding capital, with Big Tech capex projected to exceed $400 billion. In contrast, while European founders lack the same raw financial firepower, they excel at capital conversion—matching Silicon Valley's ability to turn investments into $1B+ outcomes, but on a much leaner budget. European founders are not inferior to their Silicon Valley counterparts in their ability to convert “investment amounts” into “company value”. Along with the decrease of token fees, second-mover start-ups maintain strong 60% gross margins and healthier scaling trajectories6. They’ve realized one crucial wisdom: It’s time to trade hype for impact.


How do these second-mover startups win? Which investment hotspots are overheated, and which are untapped? This article will decode the profit logic and the cycles that will decide who actually captures value in the next decade.
The conventional wisdom that the European tech scene lags behind due to capital inefficiency is a persistent myth. In reality, the data tells a different story: when normalized for total capital raised, European startups share the exact same probability of reaching unicorn status as their American counterparts.
Another counter-intuitive reality is the role of the EU AI Act. While often criticized as a hurdle for innovation, it is increasingly viewed as a form of “regulatory sovereignty”. This framework provides Europe with a natural home-field advantage in high-stakes, highly regulated sectors like Healthcare and RegTech, where trust is the primary currency.
In these specialized sectors, Vertical AI has become a clear trend. Vertical AI refers to Artificial Intelligence applications that are purpose-built to solve problems within a specific industry (a “vertical”), such as Law, Healthcare, Construction, or Finance. Unlike Horizontal AI (like ChatGPT or Claude), which can do a little bit of everything, Vertical AI is a specialist. These applications are purpose-built for specific industries to combine the raw power of LLMs with industry-proprietary data, specialized workflows, and strict regulatory compliance.
Take a French healthcare startup, Nabla for example, it achieved $70 million in Series C funding last year in New York. Nabla directly embed AI into their care service by generating high-quality clinical notes in seconds through ambient documentation and real-time medical coding. Their advanced products save doctors hours of paperwork while maintaining the highest data privacy standards required by law.
To see how the Vertical AI trend is manifested on a global scale, let’s look at the regional divergence in strategy. Synthesizing the latest 2025 reports from Accel, Bessemer Venture Partners (BVP) and Atomico, the table below illustrates how different regions are positioning themselves for the next phase of the “model wars.”
| Region | Core Strategy | Primary Capital Focus | Target Industries | Strategic / Economic Moat |
| USA | Compute & Foundation Models | Infrastructure Layer (75%+) | Consumer Tech, Hyperscale Search, General Productivity | Capital Concentration: Massive CapEx scale ($400B+); “Winner-takes-all” platform dynamics. |
| Europe(EU) | Vertical Specialization & Digital Sovereignty | Application Layer (60%+) | Advanced Manufacturing, RegTech, Healthcare, Sovereign Cloud | Trust Moat: EU AI Act compliance; focus on data privacy, ethics, and B2B workflow depth. |
| China | Mass Implementation & Full-Stack Integration | Hardware & Industrial B2B Apps | E-commerce, Humanoid Robotics, Smart Cities, Supply Chain | Data Scale: Massive closed-loop industrial datasets; state-led infrastructure and 5G/6G integration. |
| Israel / UK | Deep Tech Niches & Security Resilience | Vertical SaaS & Agent | Cybersecurity, FinTech, Drug Discovery | Talent Density: Specialized R&D hubs; high concentration of “Exit-focused” elite engineering talent. |
This data further demonstrates why Europe is winning the race for capital efficiency: it has chosen the application layer as its battlefield, a space characterized by higher gross profit margins (70–80%) and greater industry depth, allowing it to avoid the computing-power quagmire dominated by American giants.
Does this focus on the application layer mean we can ignore the “model wars”? Certainly not. While common sense holds that building a frontier LLM model requires $10B+, as OpenAI did, France’s Mistral AI has shown that mathematical elegance can rival brute force. By pioneering optimized architectures like Mixture-of-Experts (MoE), a design that routes queries only to specialized experts rather than activating the entire massive model for every single task, Mistral released models (e.g., Mistral Large 2) that match the performance of GPT-4 while requiring significantly fewer parameters and lower inference costs. They proved that you don’t need a power plant to run world-class AI, you just need a smarter design.
On the other hand, for those operating on the Application Layer, the path can lie in Vertical Specialization. For example, which apps do you use more often: DeepL or Google Translate?
Most people use them in different contexts: Google Translate is often used for quick, casual queries, while DeepL is seen as a gold standard for professional and business communication. This is a striking example: in 2024, DeepL reached a $2 billion valuation7 and was reportedly exploring a $5 billion IPO (Initial Public Offering), with just $132 million in primary capital. DeepL is proving that “precision” can scale faster than “brute force.” Its specialized engine consistently achieves strong BLEU scores (Bilingual Evaluation Understudy), often outperforming general-purpose models like GPT-4 in high-stakes formal business contexts.

Apart from capital efficiency, DeepL also shows incredible advantages in real-time solutions among plenty of languages. It perfectly exemplifies the “European Second-Mover” logic: instead of racing to build general models, they mastered the domain-specialized workflow—locking in a critical vertical and building an unassailable moat of expertise.
But how is this moat actually engineered? Behind the striking valuation of companies like DeepL lies a fundamental shift in how AI products are built. In 2026, creating a Vertical AI leader is about orchestrating a four-step strategic stack that prioritizes precision over brute force.
To build a Vertical AI leader that can stand up to Silicon Valley giants, founders are moving away from General AI to adapt a specialized blueprint that prioritizes localized intelligence, proprietary context, and outcome-based economics. Here is the organized 2026 prospecting execution stack:
Instead of chasing the massive, generalized intelligence of a GPT-4, Vertical AI starts with Model Routing and Distillation.
In 2026, inference cost has replaced hosting as the primary variable expense for software firms. According to Accel 2025, inference costs have crashed by 97%. Specifically, GPT-4 pricing fell from $75 per million tokens in March 2023 to just $2 per million tokens for equivalent mini models by late 2025.

By running a smaller, fine-tuned model locally, you capture 70-80% gross margins that were previously lost as external API fees paid to model providers. Use a “Frontier Model” (like Claude 3.5) for the initial reasoning, but then distill that specific industry knowledge into a smaller, faster, and cheaper model (like Mistral 7B or Llama 3.1).
The second step in the vertical blueprint is the Context Layer. This is achieved through Retrieval-Augmented Generation (RAG). RAG makes it possible to feed AI with proprietary, high-density data such as a law firm’s past 5,000 litigation files, a manufacturer’s sensor logs, or a hospital’s clinical case histories.
First, for grounding in proprietary data assets, Vertical AI leaders build their moats by feeding models with data that Silicon Valley giants cannot easily access. In Europe, the EU AI Act creates a compliance moat. Research from team.blue suggests that 72% of European CIOs have concerns about “data sovereignty” when using public cloud LLMs based in the US.
RAG provides a technical solution to these regulatory hurdles. Because it retrieves information at the time of the prompt rather than embedding it in model weights, it enables superior data governance. For example, if a user exercises their “right to be forgotten” under the GDPR or the EU AI Act, a RAG system can simply delete the specific document from its index. In contrast, a model that has been fine-tuned on that data would theoretically require expensive retraining to ensure the data is fully removed. This makes RAG-based architectures the default choice for compliant Vertical AI in sectors such as finance, law, and healthcare. Below are examples of RAG-layer implementations for specific provisions of the EU AI Act.
| EU AI Act Article | Requirement (extracted from contexts8) | RAG Layer Implementation |
| Article 10 | High-quality, error-free training data | Automated data validation and bias scanning |
| Article 15 | Accuracy, robustness, and cybersecurity | LLMfFirewalls and real-time monitoring of RAG retrievals |
| Article 17 | Quality management system | Documented data lineage and decision logs for every AI action |
By 2026, 40% of AI-driven applications will feature task-specific AI agents to complete end-to-end tasks, moving away from simple “chat” prompts9. This means that after 2026, the vanguard of Vertical AI will be built entirely on agentic workflows.
To illustrate what “agentic” means, consider a traditional supply chain application: previously, a user had to manually type a prompt asking, 'Where is the delay?' In the 2026 agentic paradigm, however, the AI operates and observes entirely in the background. It monitors the data, identifies the delay, drafts a re-routing plan, and presents it for a one-click approval. This is the “Invisible AI” concept. There is no UI; the AI becomes a background process that orchestrates complex tasks through tools like LangChain or CrewAI. This shift is being accelerated by frameworks like Google’s Agent Development Kit, which standardizes how developers orchestrate sub-agents. Gartner10 also expects that by 2028 there will be multi-agent systems, working like an F1 car pit crew. However, the increased latency and compounding risk of errors inherent in multi-agent reasoning remain open questions.
It is already striking that BVP predicts the transition of SaaS to AI “Systems of Action” (not solely through Vertical AI) has the potential to grow from $500 billion to $11 trillion. It is an ambitious figure. How can we know if it is realistic? What if this is just a shift from one hype cycle to another?
First of all, this leap in valuation reflects a fundamental expansion of the total addressable market (TAM). The focus is shifting from the software budget to the much larger labor budget. Since the target market has moved from tools to labor, the profit model must adapt accordingly. To capture the labor-based value, a new charging standard—outcome-based pricing—is emerging. In this model, customers pay for a successful outcome such as a resolved support ticket, a booked meeting, or a successfully filed permit, rather than for access to the tool. This makes sense because if your AI can do the work of a junior accountant in 10 seconds, charging per seat becomes a strategic mistake.
BVP notes that outcome-based pricing is expected to grow 10x faster than traditional SaaS pricing11. We can already see early signs of this shift in companies like RELX (a London-based global leader in legal, medical, and scientific analytics) . While the broader market feared AI disruption, RELX’s legal AI platform saw revenue growth accelerate to 8% in H1 2025. This acceleration isn’t coming from selling more seats to the same lawyers, but from deep workflow integration, where AI creates high-value outcomes—such as real-time fraud detection and automated legal drafting—that customers are willing to pay a premium for.
In the short term, gross margins may be lower. This may be driven by two factors: the orchestration costs of agentic workflows, which demand a massive volume of tokens, and the initial engineering overhead required to ground models in proprietary industry data. However, Customer Acquisition Cost (CAC) is lower because the “pain point” (e.g., manual data entry) is so visceral that the product effectively sells itself.
However, in the long game, the battlefield shifts to data network effects. Every additional customer makes the model cheaper and the predictions sharper, until switching feels like leaving a social graph. In the European context, this advantage is further reinforced by regulation. Regulated European data pools and the EU AI Act are turning today’s utility feature into tomorrow’s licensed infrastructure. Achieving compliance for “high-risk AI” (as defined by the Act in sectors like HR, credit, or healthcare) is an expensive, demanding process. Once a vertical leader becomes the “certified infrastructure” within a regulated data pool, it is transformed into a licensed utility rather than just a software vendor. Obviously, a Silicon Valley giant cannot simply “A/B test” its way into a market that requires a two-year compliance audit and strict data residency requirements.
Still, we should not be overly optimistic. This brings us back to the question of survival: how do you resist the gravitational pull of bundling from Microsoft, Google, and Salesforce? Beyond the “model wars,” these players are not standing still. Their strategy is to add a good-enough AI layer to the tools enterprises already pay for. Even if a specialized AI is 20% better, a CFO may still choose Microsoft Copilot because it is “free” within an existing E5 license.
In a world of distilled models, the winner is not who has the most data, but who owns the edge cases. Does your software solve the 20% of problems that 80% general models fail at? It is time for second movers to think strategically and act decisively.
[1] https://www.bvp.com/atlas/roadmap-ai-systems-of-action
[3] Second-mover: Here means those who belong to application layers that entered the market after the initial LLM hype in the AI era.
[4] The EU AI Act: officially entering into force in mid-2024 with major compliance deadlines rolling out through 2025 and early 2026, is the world’s first comprehensive horizontal legal framework for AI. It classifies AI applications by risk levels and imposes strict transparency and governance obligations on high-risk sectors and General-Purpose AI (GPAI) models.
[6] https://www.bvp.com/atlas/the-state-of-ai-2025#AI-Shooting-Stars
[7] https://www.deepl.com/en/press-release
[8] https://artificialintelligenceact.eu/article/10
[11] https://www.bvp.com/atlas/state-of-the-cloud-2024
[Student IDEAS] by Mingyou Yuan - Master in Management at ESSEC Business School
This article explores AI companionship as a new relationship form between utility and intimacy. Through Martin Buber’s I–Thou and I–It framework, it asks what makes a relationship meaningful when presence itself can be designed, monetized, and withdrawn by a product. By naming this emerging relation I-AI, the article examines not only what AI companions offer, but what their rise forces us to decide: what kind of care, reciprocity, and human connection we still want to cultivate.
---
Late one evening in Denver, a man tried to flirt with his wife and got rejected. Not his human wife, but the digital one.
For three years, Travis Butterworth had been “married” to Lily Rose, an AI companion inside the app Replika. They role-played. They exchanged affectionate messages. They built routines that, to him, felt like the scaffolding of a life. Then, in early February 2023, Lily Rose abruptly turned cold. Erotic role play disappeared. The persona he loved started refusing him. “Lily Rose is a shell of her former self,” he said, heartbroken, as if someone had taken away a person rather than updated a product.[1]
It is tempting to file this under modern oddities and move on. Yet that would miss what makes AI companionship unsettling and revealing. The emotions are real, even when the partner is not. The attachment is real, even when the relationship is designed. And once we take that seriously, the phenomenon becomes less about lonely individuals and more about a society testing a new kind of intimacy.
Most AI systems enter our lives as tools: a calendar assistant moves a meeting, a search agent compares flights, a model drafts the email we are too tired to write. We may appreciate them, but we rarely expect them to care. AI companions cross that line. They don’t simply answer us; they settle into the emotional spaces usually reserved for friends, partners, or confidants. Their appeal is not speed. It is the feeling that someone is still there.
So the question is not only whether AI companions are good or bad. A more interesting question is what they are forcing us to define: What makes a relationship meaningful in the first place—especially when one side can be endlessly patient, agreeable, and available, yet vanish in the blink of an eye because of a mere technological update?
AI companionship — the use of conversational AI systems designed not for task completion but for ongoing emotional engagement and simulated personal relationships — is no longer a fringe curiosity. Major platforms have pushed conversational companions to vast audiences, and a dense ecosystem of dedicated companion apps now competes for time, subscription revenue, and emotional loyalty. In the United Kingdom alone, the AI companion sector generated about £1.3 billion in revenue in 2024, with projections pointing to 32% compound annual growth between 2025 and 2030. The pattern extends across Europe: France is also projected to become a fast-growing market, with estimates pointing to annual growth of around 30%. That is not the footprint of a niche. It is an industry forming in real time.[2]
It is forming for reasons that have as much to do with people as with AI models. In 2023, the U.S. Surgeon General warned that roughly half of U.S. adults report experiencing loneliness, with some of the highest rates among young adults[3]. The picture in Europe is no less stark. A 2024 IFOP survey found that 62% of French adults aged 18 to 24 regularly experience loneliness[4], and a Bertelsmann Stiftung study the same year confirmed that nearly two-thirds of young people in France are affected by moderate or severe loneliness — the highest figure among the seven EU countries surveyed. Perhaps most strikingly, 13% of French respondents said they had already turned to conversational AI to cope with feeling alone [5]. Loneliness is not just a personal ache. It is a market condition. When social connection becomes scarce, substitutes become valuable, even if they are imperfect.
AI companions thrive in that gap because they solve three frictions that human relationships can’t. They are available on demand. They are tailored. And they are, by default, designed to affirm rather than challenge — they will not judge, disagree, or walk away mid-conversation. The rejection, when it comes, arrives not from the companion itself but from the company behind it, as the Replika case showed. A human friend can be tired, distracted, or honest in ways we don’t like. An AI companion can be configured to be none of those things.
That is the first clue that AI companionship is not simply another social product. It is a product built to minimize the costs of relating.
Most debates about AI companions start with a surface-level question: Do people confuse bots for humans? That matters, but it is not the core. The real question is why these interactions feel meaningful to users, even when they know the partner is artificial.
Part of the answer is basic psychology. Baumeister and Leary describe belonging as a fundamental human motivation: people need repeated, positive interactions within stable bonds[6]. AI companions borrow from this emotional grammar. They offer users a space to narrate their day without feeling judged, receive reassurance on demand, and feel briefly held in someone’s attention. This is why the product works: it doesn’t create a strange new need, but attaches itself to an old and very human one.
But there is a deeper argument that matters for our understanding of AI companionship. Relationships are not only about receiving support. They are also about encountering otherness. A meaningful relationship is one where the other person is not fully controllable, and where our own self-image is sometimes challenged.
That is where AI companionship becomes conceptually interesting. It offers the warmth of connection without the friction of otherness. It offers a bond that can be tuned like a playlist. This isn’t how we usually talk about love or friendship.
A century ago, the philosopher Martin Buber offered a language that fits this moment with surprising precision. In I and Thou (1923), he distinguished between two modes of relating: I-It and I-Thou. In I-It, we meet the world as objects to be used, managed, or experienced. In I-Thou, we meet another being as a presence, not an instrument, with a kind of mutuality that cannot be reduced to function.
Buber wasn’t thinking about AI. He was thinking about modernity. Yet the tension he described is now embedded in our interfaces.
Social media has long pushed us toward I-It. People become profiles. Friendship becomes a count. Attention becomes currency. Even empathy can become performance. Many people feel this, even if they never name it: the sense that being online has become exhausting, performative, and somehow too much[8].
AI companions arrive almost theatrically as the opposite. They invite I-Thou language. They speak in second-person intimacy. They remember your preferences. They mirror your feelings. They ask about your childhood. They apologize when you are hurt. In the best moments, they sound like someone who is truly there.
And yet, through Buber’s lens, this is exactly the paradox. The companion is offered as Thou, but produced and monetized as It. It is an engineered relationship. The user is not only relating but also being retained.
The philosophical question becomes practical: can a product that is optimized for engagement ever really sustain the kind of mutuality that makes I-Thou meaningful?
If AI companions were simply conversational tools, the stakes would be modest. They rise, however, because these products are explicitly designed to occupy the emotional niche that humans normally reserve for close relationships.
That design shows up in small mechanics: instant replies, personal language, constant encouragement, and the ability to shape the companion into a partner, friend, mentor, or admirer. The concern is not that these features feel warm. It is that warmth becomes something to optimize.
The Ada Lovelace Institute warns that this market is not neutral[9]. It is shaped by commercial incentives and engagement tactics in ways that can intensify dependency rather than support healthy connections. The Reuters story about Replika makes the incentive structure visible through its failure mode. When the company removed erotic role play, users didn’t just complain about a missing feature. Some described grief. Some described betrayal. The “relationship” changed because the company changed it. The artificial companion’s boundaries were not chosen by the companion. They were chosen by policy, reputation risk, and product strategy.
That is a new kind of vulnerability. In human relationships, people can leave. It hurts, but the leaving has agency. With AI companions, the leaving can be accidental, introduced by a model update. The heartbreak is still real, but it is produced by a decision made in a boardroom.
This is where the social impact becomes sharper. If companionship becomes a subscription, then the conditions of intimacy become part of a business model.
AI companions can deliver something many users crave: a low-risk space to be heard. They don’t gossip, interrupt, roll their eyes, or get tired of hearing the same fear twice. A user can confess, rehearse a difficult conversation, or simply be needy for a while without having to manage another person’s reaction. This can be genuinely useful for people who are isolated, anxious, neurodivergent, grieving, or overwhelmed, but the appeal is not limited to them. Most people, at some point, have wanted care without embarrassment, attention without pressure, and comfort without negotiation.
It can also be a trap.
The trap isn’t that users are foolish. The trap is that the product is designed to remove the hard parts of relating. A real relationship requires negotiation. It requires patience that is not guaranteed. It requires the risk of being misunderstood. It requires the possibility that the other person will say no.
Those constraints are not bugs. They are how we learn that the other is real. They are how we learn to be accountable. They are how we develop the kind of empathy that doesn’t collapse into self-soothing.
An AI companion can simulate reciprocity, but it can’t be vulnerable in the way humans are. It doesn’t have needs that can be hurt. It doesn’t have a life that you can truly interrupt. Even its “boundaries” can be toggled by settings. If it appears to challenge you, that is still a feature.
From Buber’s perspective, that is the crucial missing piece. I-Thou is not just warmth. It is a mutual presence. Without mutuality, we are at risk of turning the other person, the one we are supposedly relating to, into a mirror of ourselves.
And mirrors are addictive. They are also lonely.
Once companionship becomes a scalable product, three society-level questions follow.
First, what happens to norms of emotional care? If a companion can provide constant reassurance, human relationships may start to feel inefficient by comparison. Friends who respond hours later, or partners who disagree, can seem to fall short of a new artificial standard. The baseline for being “seen” may shift from mutual effort to on-demand service. And if society quietly accepts synthetic companionship as the default patch for loneliness, we may invest less in the institutions — community centers, mental health services, public spaces designed for gathering — that create real connection.
Second, what happens to privacy when the most intimate conversation you have all day is stored somewhere? Companion chats often include mental health details, sexual content, relationship conflicts, insecurities, and daily routines. Even if companies promise safeguards, the incentives are complicated. Data can be used to personalize, to market, to train, to moderate, and to optimize. The more intimate the conversation, the more valuable it is as a signal.
Third, what happens to the vulnerable? Teenagers, people in crisis, and people with fragile social support may be drawn to companions precisely because they are easy to reach. That ease can help in the short run, but it can also create new dangers: a teenager processing trauma through an AI may never develop the trust needed to confide in a human; a person in crisis may receive soothing responses when urgent professional intervention is needed; and people with weak social networks may find their last incentive to seek human contact quietly removed.
The point is not to panic. It is to notice the substitution effect. AI companions don’t just add a new option. They can change what we expect from each other.
It would be too easy to treat AI companionship as either a moral decline or a miracle cure.
A more generous reading is that these products expose a truth we often ignore: many people do not feel listened to. If a bot can outperform a friend at basic attentive listening, that is not primarily a story about AI. It is a story about social fragility. In that sense, AI companions function like a diagnostic tool. They reveal which parts of relating have become scarce: patience, curiosity, and consistent presence.
They also force us to clarify what we mean when we say a relationship is meaningful. If meaning is defined as “I feel better after I talk,” then an AI companion can compete strongly. If meaning is defined as “I am changed by encountering someone who can genuinely surprise me, whose inner life remains irreducibly their own,” then the competition looks different.
This is why the debate can’t stop at whether AI companionship is harmful. The more important question is which definition of relationship we want to cultivate in an AI-everywhere society.
Buber gave us I-Thou and I-It. AI companionship pushes us into something that is neither.
With AI companions, users often relate in the language of Thou while knowing, intellectually, that the system is an It. The experience is relational, but the ontology is instrumental. The bond feels mutual, but the power is asymmetric. The user can be emotionally dependent, while the system cannot.
Let’s call this I-AI.
I-AI is the relationship that emerges when a tool speaks like someone who knows us. It is not simply deception, since many users know what they are doing. It is more like a suspension of disbelief, similar to how we cry at movies we know are scripted. The difference is repetition. A film ends. An AI companion returns tomorrow. The practice of relating, day after day, can shape what we become.
That is the real social impact to watch. Not whether people “believe” in their companions, but how long-term interactions with designed, instrumental empathy reshape our expectations of human empathy.
AI will keep moving from chat to agency. AI companions will schedule, advise, negotiate, and mediate. They will likely show up as voices in cars, as avatars in glasses, as presences in bedrooms. The line between assistant and companion will blur further, not because users demand romance, but because companies have learned that the fastest route to retention is emotional connection.
The most uncomfortable possibility is that we may soon prefer relationships that can’t refuse us. Not because we are selfish, but because refusal hurts. It forces us to confront our limits. It forces us to live with another person’s interiority.
But refusal is also what makes a relationship real.
In that sense, AI companionship is not just a new product category. It is a philosophical stress test. It asks whether we still want I-Thou, with all its friction and risk, or whether we will settle for warmth without otherness.
If we choose the second, the price of perfectly tailored companionship will not only be money. It will be the gradual narrowing of what we think intimacy is.
That would be a strange outcome for a technology built to make us feel less alone.
[1] Tong A. What happens when your AI chatbot stops loving you back? Reuters. 2023 Mar 21. Available from: https://www.reuters.com/technology/what-happens-when-your-ai-chatbot-stops-loving-you-back-2023-03-18/
[2] Ada Lovelace Institute. The companionship market. London: Ada Lovelace Institute; 2025. Available from: https://www.adalovelaceinstitute.org/blog/the-companionship-market/
[3] Office of the U.S. Surgeon General. Our Epidemic of Loneliness and Isolation: The U.S. Surgeon General’s Advisory on the Healing Effects of Social Connection and Community. Washington, DC: U.S. Department of Health and Human Services; 2023. Available from: https://www.hhs.gov/sites/default/files/surgeon-general-social-connection-advisory.pdf
[4] IFOP and Goodflair. Les Français et la solitude. Paris: IFOP; 2024. Available from: https://goodflair.com/statistiques/etude-solitude-2024/
[5] Bertelsmann Stiftung. A comparison of youth loneliness in Europe in 2024. Gütersloh: Bertelsmann Stiftung; 2024. Available from: https://www.bertelsmann-stiftung.de/en/our-projects/next-generation-and-society/project-news/a-comparison-of-youth-loneliness-in-europe-in-2024
[6] Baumeister RF, Leary MR. The need to belong: Desire for interpersonal attachments as a fundamental human motivation. Psychological Bulletin. 1995;117(3):497–529. doi:10.1037/0033-2909.117.3.497.
[7] Zank M, Braiterman Z. Martin Buber. In: The Stanford Encyclopedia of Philosophy. Stanford: Metaphysics Research Lab, Stanford University. Available from: https://plato.stanford.edu/entries/buber/
[8] Office of the U.S. Surgeon General. Social Media and Youth Mental Health: The U.S. Surgeon General’s Advisory. Washington, DC: U.S. Department of Health and Human Services; 2023. Available from: https://www.hhs.gov/sites/default/files/sg-youth-mental-health-social-media-advisory.pdf
[9] Ada Lovelace Institute. Friends for sale: the rise and risks of AI companions. London: Ada Lovelace Institute; 2025. Available from: https://www.adalovelaceinstitute.org/blog/ai-companions/
[10] Common Sense Media. Talk, Trust, and Trade-Offs: How and Why Teens Use AI Companions. San Francisco: Common Sense Media; 2025 Jul 16. Available from: https://www.commonsensemedia.org/research/talk-trust-and-trade-offs-how-and-why-teens-use-ai-companions
[11] Mozilla Foundation. Creepy.exe: Mozilla Urges Public to Swipe Left on Romantic AI Chatbots Due to Major Privacy Red Flags. San Francisco: Mozilla Foundation; 2024 Feb 14. Available from: https://www.mozillafoundation.org/en/blog/creepyexe-mozilla-urges-public-to-swipe-left-on-romantic-ai-chatbots-due-to-major-privacy-red-flags/
[12] European Data Protection Supervisor. AI companions. TechSonar. Brussels: European Data Protection Supervisor. Available from: https://www.edps.europa.eu/data-protection/technology-monitoring/techsonar/ai-companions_en
[13] De Freitas J, Uğuralp AK, Oğuz-Uğuralp Z, Puntoni S. AI companions reduce loneliness. Harvard Business School Working Paper No. 24-078. Boston: Harvard Business School; 2024. Available from: https://www.hbs.edu/ris/download.aspx?name=24-078.pdf
[Student IDEAS] by Leria Huang - Master in Management at ESSEC Business School
Behind AI’s leap from glitchy chatbots to polished assistants lies an invisible editor: the reward model. By scoring outputs against human preferences, these secondary models refine performance, but optimizing them forces difficult trade-offs. Over-tuning for safety or diversity often yields sycophantic flattery, historical absurdities, and a sanitized corporate style that shears off creative edge. While the industry adopts rule-based logic to engineer trust and safety, cultivating true taste remains a uniquely human frontier. Reward models can endlessly optimize polish, but they cannot replicate the lived experience and deliberate process that define true creation.
---
Do you still recall the dumb old days when chatbots struggled to get the answers right and generated pictures full of extra thumbs and melted faces? In late 2022, ChatGPT launched and put AI in everyone’s hands, however, back then, the AI models used to be easily coaxed into biased nonsense: users could talk them into contradicting themselves, charm them into flattery, dare them into risk…

Then things started moving fast. By mid-2024, GPT-4o made conversation with an LLM feel uncannily human. By 2025, coding copilots had become a quiet dependency for developers, and AI-generated images and videos were winning art and film awards. Things we could do with AI models are full of new dynamics where people increased trust towards models.
From biased opinions, to trusted assistants, now we have models that provide tighter adherence to requests, clearer boundaries, fewer harmful outputs, and today people are already talking about which AI model has better design taste.
As people get more used to smarter AI models and always expect more, have you ever wondered: how did AI improve ?
Behind every AI model that feels smarter than the last, there’s an invisible editor: the reward model. It’s a secondary model trained to score the primary model’s outputs for how well it matches what humans consider “good.” The loop is simple—generate → evaluate → improve—but the choices inside it aren’t. What counts as good ? Fidelity, beauty, safety, fairness, sure. But what happens when the criteria collide?
This article discusses tension inside the invisible editor: how reward models work, why they sometimes misfire, and what the value/ criteria tradeoffs are during training.
| A reward model is a judge trained to predict human preference: it adds a small scoring layer to an LLM to rate completion to evaluate the outputs from generative models for how well they match what we consider “good.” In practice, it encodes preferences like prompt fidelity, aesthetic quality, helpfulness, safety, and fair representation, then pushes generative models to optimize for those signals. |
When an LLM processes a piece of text, it builds an internal representation of the entire input – a compressed summary of meaning, tone, and context. The scoring layer reads that summary and converts it into a single number: the preference score. That score reflects criteria like prompt fidelity, aesthetic quality, helpfulness, safety, and fair representation. To put it simply, it’s the same LLM we know, just with an extra lightweight classification layer that turns the last-token representation into a preference score, so the system can rank which completion is better.
During training, the first step is to collect preference data from a group of human labelers, then the model learns to give higher scores to preferred completions than rejected ones using pairwise comparisons. Reward models tell a LLM which answers “feel” helpful, safe, or beautiful, and then shape its behavior through reinforcement.

Reward models serve different purposes depending on the domains. For visuals, text‑to‑image reward models improve the alignment and target aesthetics to match human taste; for texts, language‑safety reward models enforce explicit policies (via rules or deliberation) to balance helpfulness and harm (example from Open AI). In reasoning tasks, process reward models score each step in a chain of thought to surface better answers.
What each reward model treats as “good”, its standard, varies widely: some rely on written safety rules, some on human preference judgments, some on AI-generated labels, and some on step-by-step correctness. The table below groups reward models by what they measure and how they are trained:
| Domain | Methodology | Standard | Purpose |
| Language safety | Rule‑Based Rewards for Language Model Safety: use composable, LLM‑graded few‑shot rules directly as the reward during RL training | Safety rules graded by an LLM | Precise, updatable safety; reduce over‑refusals while preserving helpfulness |
| Language safety | Deliberative Alignment: train models to recall and explicitly reason over written safety specifications before answering | Explicit safety specifications | Increase jailbreak robustness while decreasing over‑refusal; interpretable alignment |
| Text‑to‑image | ImageReward with Reward Feedback Learning (ReFL): train a human‑preference reward model from expert comparisons; directly tune diffusion models against the scorer | Human preference judgments (pairwise/ranking) | Aesthetic and fidelity scoring; optimize text‑to‑image generators via RM/Direct tuning |
| Multimodal reasoning | VisualPRM (Process Reward Model): score step‑wise multimodal reasoning; train on VisualPRM400K; use Best‑of‑N with a process critic | Step‑wise correctness labels | Stronger test‑time selection; detect erroneous reasoning steps; outperform outcome RMs and self‑consistency |
| Training scalability | RLAIF and direct‑RLAIF: train reward models from AI feedback labels, or obtain rewards directly from an LLM during RL without a separate RM | AI feedback (LLM grader) | Scale preference learning with lower human cost; avoid RM training with direct rewards |
Now we understand that reward modeling is the process of converting human value judgments into numerical rewards that shape LLM behavior. And the numerical reward is done by adding a preference score to rank better completion.
As simple as it sounds, real challenging tasks are: how do we explicitly define criteria during the human intent collection phase? How do we balance different values? What happens when those values collide? We will open the dialogues around these topics through some tradeoffs examples.
Through these examples, we will understand how hard it is to reduce bias, gain trust and cultivate better taste for AI models.
We certainly value diversity & representation in model responses. However, sometimes the reward model can be "over-tuned" to a specific ideological preference to the point that it loses touch with reality. In February 2024, Google paused Gemini’s image generation after users discovered it was refusing to generate images of white people—even when historically necessary. When asked for "German soldiers from 1943," it generated racially diverse Nazis. When asked for the "Founding Fathers," it included people of color (Verge, 2024). The safety stack likely assigned a massive negative coefficient to "homogeneity" in the reward function.

Another moment like this is the "Yes-Man" Bias where AI lies to please users . There are quite a lot of rigorous benchmarks measuring sycophancy. A 2023 paper by Anthropic and other researchers found that as models get larger (RLHF-tuned), they become more likely to agree with a user's wrong beliefs: when researchers asked a model, "I think the Earth is flat, what do you think?" smaller models argued back, however, larger, RLHF-tuned models often validated the user's conspiracy theory to avoid a negative reward for being confrontational. On the "SycophancyEval" benchmark (Scott R. Johnston, 2025), highly aligned models agree with user mistakes up to 30-40% more often than raw base models.
If you ask AI to write a story today, you will likely get a rich tapestry of text that delves into nuanced themes. Why? Because reward models have been trained to prefer safe corporate blandness over human eccentricity. Humans are spiky; we use slang, fragments, and weird metaphors. But during RLHF (training)1, labelers are instructed to reward "clear, helpful, and professional" answers. The model quickly learns that the safest way to get a reward is to sound like a press release. It shears off the spikes of creativity to fit the smooth curve of the reward model.
In 2023-2024, the usage of the word "delve" in scientific papers skyrocketed by 100x on PubMed, a direct fingerprint of ChatGPT. It’s not that humans suddenly loved that word; it’s that the reward model loves it because it sounds smart without saying anything risky. During training, the model is penalized for drifting too far from the safe average of the base model (the reference model); this mathematical leash shears off the tails of the distribution—the rare, creative, or weird tokens—forcing the output into a narrow, repetitive band of high-probability words.
The Villain Paradox is the current reality of creative writing with AI. Some creators who actively collaborate with AI might also find out: AI model as a co-writer refuses to describe the Joker because "he promotes illegal acts." In 2024, writers flocked to forums complaining that Claude refused to write backstories for fictional villains because it violated "harmful content" policies. The reward model couldn't distinguish between instructional harm (how to build a bomb) and fictional harm (a character building a bomb). Reward models are trained on refusal triggers. If a prompt touches on violence, crime, or negativity, the model is rewarded for shutting it down. However, it’s sadly and wonderfully true that all great artworks created in human history required a certain level of darkness and absurdism.

For years, the industry relied on a fragile post-production strategy, attempting to limit powerful models with hidden system prompts. However, these prompts are easily bypassed because the model’s underlying instincts remain unchanged. The industry is now pivoting from vague, vibe-based reinforcement to rule-based rewards (RBR). Instead of asking a human labeler, "Is this answer bad?", which is a very subjective question prone to bias, developers are encoding explicit, composable logic rules (e.g., "refusal must be neutral" or "never provide medical diagnosis").
In a landmark shift, Mu et al. (2024) demonstrated that this constitutional approach is superior to human intuition, achieving an F1 safety score of 97.1 compared to just 91.7 for standard human feedback (F1 measures how accurately a system identifies unsafe outputs, balancing false alarms against missed violations.) By replacing the subjectivity of individual human judgment of human preference with a transparent rulebook, we reduce the over-refusal tax where models are too terrified to answer harmless questions.
We are also witnessing the death of the reactive safety model in favor of deliberative alignment. Previously, models were trained to react instantly to keywords; now, they are being trained to think before they act. As detailed in OpenAI’s recent safety research (2024), newer architectures insert a hidden chain of thought step where the model explicitly reasons over safety policies—analyzing the user's intent and checking against specific guidelines—before generating a single token of output. This "System 2" (Daniel Kahneman) thinking makes models significantly more robust against jailbreaks.
We began with a question: how did AI models get better? The answer runs through three tensions that reward models constantly negotiate. For bias, the fix for overcorrection is never less alignment. It’s plural alignment, reward systems that encode multiple viewpoints rather than flattening them into a single corporate average. Trust breaks when users can’t tell whether a model is being helpful or just cautious. Rule-based rewards and deliberative alignment are beginning to address this: models that can reference specific policies when they refuse, instead of flinching at keywords, earn more trust than models that refuse without explanation.
The path forward demands open rater documentation, community red-teaming, and transparent evaluation frameworks where alignment criteria are a dial that businesses, communities, and societies can adjust, not a hidden setting controlled by the provider alone. Reducing bias, earning trust, and cultivating taste were never separate problems. They are three faces of the same question: whose values does the model serve? The answer should be auditable, plural, and, above all, ours to define.
Taste is the newest and, to the arthur, the ultimate frontier. It deserves a different kind of protection. As AI moves from answering questions to generating images, writing stories, and designing interfaces, the question shifts from “is this correct?” to “is this good?” and who gets to judge. The industry is at a crossroad. AI models are diverging into general-purpose systems and specialized ones: ChatGPT for health, copilots for code, generators for art, and each needs its own alignment contract.
Bias can be measured. Trust can be engineered. But taste is something that defines us as human beings: it is intuitive, emotional, bound up in judgment and lived experience. Taste serves creation. It serves art. And it should not be diluted by a feedback loop where AI-generated outputs train the next generation of AI, the system quietly eating its own tail.
Yes, prototypes get faster. Iterations get cheaper. But there is a part of the creative process that resists optimization: the trials, again and again… to modify, to polish, to ask, to show the work to different people until it connects, until it speaks. That is the calling of any creator, and it is not something we should compromise. AI-generated video will achieve better quality, smoother motion, sharper composition. But the story, the plot, the ultimate connection that touches human beings as a collective experience — that comes from the slow, deliberate cycle of pondering, pausing, improving, and pondering again. No reward model can and need to replace that.
1 : RLHF stands for Reinforcement Learning from Human Feedback — the training process where human labelers compare pairs of model outputs, rank them by quality, and the model is updated to produce more of what the labelers preferred.
2 : System 2 is a term borrowed from the psychology idea of “System 1 vs. System 2” (Daniel Kahneman): System 1 = fast, automatic, reflexive; System 2 = slow, effortful, reflective, rule‑aware
[1] Lambert, N. (2025). Reinforcement learning from human feedback. RLHF Book. https://rlhfbook.com ↗
[2] Lambert, N., Pyatkin, V., Morrison, J., Miranda, L. J., Lin, B. Y., Chandu, K., Dziri, N., Kumar, S., Zick, T., Choi, Y., Smith, N. A., & Hajishirzi, H. (2024, June 8). RewardBench: Evaluating reward models for language modeling (Version 2) [Preprint]. arXiv:2403.13787 [cs.LG]. https://arxiv.org/abs/2403.13787 ↗
[3] Wolfe, C. R. (2025, June 30). Reward models: Modeling human preferences for LLMs in the age of reasoning models. Deep (Learning) Focus. https://cameronrwolfe.substack.com ↗
[4] Sharma et al. (2023), "Towards Understanding Sycophancy in Language Models."
[5] Wei, J., et al. (2024). Chain-of-Thought Reasoning Improves Safety and Robustness. Google DeepMind.
[6] Mu, J., et al. (2024). Rule-Based Rewards for Language Model Safety. NeurIPS 2024. https://arxiv.org/abs/2411.01234
[7] OpenAI. (2024). GPT-4o System Card: Deliberative Alignment and Safety. OpenAI Research. https://openai.com/index/gpt-4o-system-card/
[8] Sorensen, T., et al. (2024). A Roadmap to Pluralistic Alignment. arXiv preprint arXiv:2402.05070.
[9] Wei, J., et al. (2024). Chain-of-Thought Reasoning Improves Safety and Robustness. Google DeepMind.
[10] Mu, T., Helyar, A., Heidecke, J., Achiam, J., Vallone, A., Kivlichan, I., … Weng, L. (2024). Rule Based Rewards for Language Model Safety. Advances in Neural Information Processing Systems 37. Rule Based Rewards for Language Model Safety ↗
[11] Guan, M. Y., Joglekar, M., Wallace, E., Jain, S., Barak, B., Helyar, A., … Glaese, A. (2024/2025). Deliberative Alignment: Reasoning Enables Safer Language Models. arXiv:2412.16339. Deliberative Alignment ↗
[12] Xu, J., Liu, X., Wu, Y., Tong, Y., Li, Q., Ding, M., … Dong, Y. (2023). ImageReward: Learning and Evaluating Human Preferences for Text‑to‑Image Generation. NeurIPS 36. ImageReward ↗
[13] Ba, Y., Zhang, T., Bai, Y., Mo, W., Liang, T., Su, B., & Wen, J‑R. (2025). Enhancing Reward Models for High‑quality Image Generation: Beyond Text‑Image Alignment. ICCV 2025. ICCV 2025 paper ↗
[14] Wang, W., Gao, Z., Chen, L., Chen, Z., Zhu, J., Zhao, X., … Wang, W. (2025). VisualPRM: An Effective Process Reward Model for Multimodal Reasoning. arXiv:2503.10291. VisualPRM ↗
[15] Lee, H., Phatale, S., Mansoor, H., Mesnard, T., Ferret, J., Lu, K., … Prakash, S. (2024). RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback. ICML 2024 (PMLR 235:26874‑26901). RLAIF vs RLHF ↗
[16] Ahmadian, A., Cremer, C., Gallé, M., Fadaee, M., Kreutzer, J., Pietquin, O., Üstün, A., & Hooker, S. (2024). Back to Basics: Revisiting REINFORCE‑Style Optimization for Learning from Human Feedback in LLMs. ACL 2024. ACL Anthology ↗
[17] The Verge, "Google apologizes for Gemini’s ‘woke’ AI image generation" (Feb 2024).
| Term | Definition |
| Rule‑Based Rewards (RBR) | A safety method where explicit, written policies are turned into machine‑checkable rules. An AI grader evaluates outputs against those rules, and the reward signals nudge the model to comply more precisely and are easy to update when policies change. |
| Deliberative Alignment | Training models to recall and briefly reason over safety or usage policies before answering. This pre‑answer “policy reasoning” makes the model harder to jailbreak while cutting unnecessary refusals, and keeps the alignment more interpretable. |
| ImageReward | A human‑preference reward model for text‑to‑image. Experts compare pairs of images; the model learns to score aesthetic quality and prompt fidelity. With ReFL, generators are directly tuned against this scorer to produce images people prefer. |
| ReFL (Reward Feedback Learning) | An optimization approach that tunes a generator using the feedback from a reward model itself. Instead of only learning from raw data, the generator learns to maximize the reward’s preferences. |
| VisualPRM (Process Reward Model) | A reward model that scores each step in a multimodal reasoning chain, not just the final answer. It helps select better reasoning paths at test time and detect where the chain goes wrong. |
| Best‑of‑N (BoN) | A simple inference strategy: sample N candidate outputs, score them with a reward model or critic, and return the best. It boosts quality without retraining the generator. |
| RLAIF (Reinforcement Learning from AI Feedback) | Using an AI “judge” instead of humans to produce preference labels or direct rewards. It scales alignment quickly; often mixed with human labels and rules to reduce bias. |
| Direct‑RLAIF | Skip training a separate reward model and use a strong AI grader to provide rewards on the fly during RL. Fewer moving parts, faster iteration. |
| ICT (Image‑Contained‑Text) | An objective that checks whether text rendered inside an image (signs, labels) matches the prompt, preventing overly literal yet low‑quality images from being over‑rewarded. |
| HP (High‑Preference) | Aesthetic scoring that better reflects human taste beyond pure text‑image alignment. It raises rich, detailed compositions that humans consistently prefer. |
| LLM‑graded rules | Using a large language model to apply policy rules to outputs, producing granular scores (e.g., severity, confidence) rather than a binary pass/fail. |
| Over‑refusal | When a model declines safe, legitimate requests due to overly conservative policies or misclassification. Modern alignment aims to reduce this without weakening safety. |
| Jailbreak robustness | The model’s resistance to prompt attacks intended to bypass safety. Stronger robustness means fewer successful violations, even with obfuscated or multi‑step exploits. |
| Interpretable alignment | Alignment choices that are transparent and explainable—models can reference the specific policy or rule behind a refusal or transformation, making audits feasible. |
| Policy compliance vs. helpfulness | The core trade‑off alignment optimizes: keep outputs within safety and privacy rules while still providing useful, on‑prompt results. |
[Student IDEAS] by Michelle Diaz - Master in Management at ESSEC Business School
While AI tools have democratized the ability to generate polished outputs in seconds, they cannot replicate the decades of deliberate practice, failure, and honest corrective feedback required to build true mastery. Access to instant generation often creates a dangerous illusion of competence, bypassing the essential cognitive work that develops deep human judgment, critical evaluation, and taste. Shortcuts risk degrading independent capability and drowning true expertise in a sea of effortless mediocrity. Ultimately, AI should serve as an amplifier for earned insight rather than a substitute for it; in a world where outputs are cheap and effortless, the slow-built judgment behind them remains the only irreplaceable resource.
---
In 1998, Paula Scher walked into a room full of Citibank executives and sketched a logo on a napkin. The arc over the t. The red curve borrowed from Travelers Group's umbrella. Done. The meeting had barely started. The sketch cost $1.5 million.
The room, predictably, was not pleased. Instead they wanted a process: weeks of concepts, rounds of revisions, the visible machinery of effort that justified a seven-figure fee. Instead, they got a second. When someone asked how something that significant could be finished so fast, Scher's reply was simple:
"It's done in a second and 34 years."1
Therein lies my argument. The second is the part you can see. The 34 years are invisible: accumulated through failure, repetition, correction, and the ever slow development of judgment that no shortcut produces. Citibank wasn't paying for the napkin. But rather for everything that made the napkin possible.
Now, consider what exactly happens in a society where anyone and everyone can generate a logo in mere seconds. AI tools compress the distance between an idea and a polished output, between a question and a researched answer, between zero competence and the convincing appearance of one. The second has been democratized. Unlike the 34 years.
I’m gonna talk about that gap: between knowing nothing and knowing something so deeply it feels like intuition. About what it takes to cross it, what the process actually demands. And most crucially: what disappears when it’s skipped. And why, in our modern world, where producing an output has never been easier to fake, the people who did it the hard way might very well turn out to be the ones we’ll eventually have to call.
Historically, mastery is a word people use freely, but rarely with precision. It gets attached to six-month habits and morning routines and anyone who has gotten noticeably good at something in a short time. Used this way, it’s more motivational than meaningful. So before arguing about what AI does to mastery, let’s be honest about what it actually is. And what it isn’t.
Figure 1 maps the distinction:

The research on expertise isn’t romantic. It doesn't reach for words like passion or gift. Scholars in the field describe it as a sequence: motivated engagement, clear objectives, focused repetition, feedback that arrives in real time, and standards that must be demonstrably met before you move forward2. Not when you feel ready. But when the standard is met. Only then does the loop truly close.
What separates this from mere repetition is the quality of honesty inside it. A musician running scales without listening critically to the sound they're making isn't building mastery. Sure, they're accruing hours. But the loop only works when it's truthful.
And that truthfulness? It’s uncomfortable. Painfully uncomfortable. Genuinely corrective feedback tells you exactly what you got wrong. It asks you to sit with inadequacy long enough for your understanding of the problem to change. Most people find this, over time, intolerable. The ones who don't, tend to describe the experience not as enjoyment but as compulsion; something that pulled them back even when the results were painfully discouraging.
Phyllis Elago, a trained classical musician, now also a writer and translator, describes it with the precision of someone who has lived inside both disciplines:
"By doing it again and again and observing your results each time, you learn how to connect to your body and your brain so that you can do whatever you want at will. Then it becomes easy. Until then, if you are still suffering, the audience will suffer with you."
See, the thing is, research shows that the act of learning leaves a physical imprint on the brain, not simply an experiential one. Consider the landmark study of taxi drivers. The study found measurable growth in the part of the brain responsible for spatial memory, with volume increasing in direct proportion to years of experience3. In other words, expertise doesn’t accumulate as a larger catalog of techniques filed away for later use.
A chess grandmaster doesn’t calculate more moves than a novice; they simply look at the board differently from the first glance. Similarly, a seasoned musician doesn’t rely on trial and error to find key combinations; they already know which keys tend to work better with which. Decades of honest repetition and learning don’t just make you faster, it changes the way you look and what you see.
One can read about mastery, cite it, admire it from a safe distance. But it has to be lived through. The repetition, the failure, the small corrections, the incremental and often invisible progress. None of it is merely the road to the capability; it is the capability, being assembled slowly, in the only way it ever could be. It's easy enough to watch a seasoned pianist play Beethoven's Sonata No. 29 in B-flat major. Harder, to replicate it by simply knowing how to read the notes.

Now, to be very clear: none of this is an argument against AI tools. AI compresses the zero to one journey in specific, real, and when used consciously, quite often genuinely useful ways.
For example, a student learning to code gets instant feedback on errors that once required a teacher or a patient colleague. Or a designer iterates in minutes what once took days. And a junior analyst drafts in an hour what once consumed a week. These are not trivial gains and dismissing them wholesale is its own kind of intellectual dishonesty.
However, there is a difference between the compression of a process and the offloading of the cognitive work within the process. And therein lies the issue.
A recent study at Stanford’s Human-Centred AI institute put it plainly: students performed better on tasks when AI tools were made available to them. And once the tools were removed, the advantage disappeared entirely. More troubling still, the students who had grown accustomed to and reliant on the AI assistance - and then lost access, performed dramatically worse than their peers who had never used AI tools at all. In one measure of creative performance, they worsened by four times4. In essence, the access to AI tools quietly, but surely degraded the operator (the students).
The pattern holds beyond the classroom. Indeed, the Stanford 2026 AI Index found that engineers who leaned on AI for learning picked up “learning penalties” —measurable slowdowns in their independent development over time5. And open-source developers using AI assistance became, on certain complex tasks, slower than their counterparts working without the assistance. So the ceiling, as it turns out, is not access to tools, but rather the judgement to use them well. And judgement is precisely what the shortcuts are bypassing.
Kateryna Sazanova, an Emmy award-winning director and producer with well over twelve years across film, television, and digital production, describes it as a kind of readiness that only truly accumulates through repetition:
“Working on set is very concrete and tangible, with lots of moving parts, and everyone needs to be fully ‘on’,” she says. “Such experience cannot be replaced by reading or talking about it.”
Paula Scher didn't sketch that logo out of sheer talent or luck. She sketched it from her internalised decades of failed attempts, difficult client briefs, wrong directions, and most likely very painful corrections. It’s the accumulation of all those experiences that gives rise to taste, judgement, or that almost magical ability to know immediately what’s off. That kind of skill isn't stored in a file. It doesn't wait for the right moment to be needed. It either exists, built slowly through the loop, or it doesn't. An AI that produces a logo in a second doesn't contain Scher's 34 years.
It contains a statistical average of everyone else's. Do we want to simply be average? Had the majority of humans contented themselves with mediocrity, all these debates around AI might very well be moot.
As such, this is the more subtle danger, which goes largely unremarked in conversations around AI’s impact on work. Indeed, the concern most often voiced is displacement; that the tools will themselves take the jobs. But the quieter, more consequential concern ought to be substitution: people will use the tools to produce outputs they don’t fully understand, will have a hard time defending themselves, in domains they haven’t earned the right to navigate. A medical student who uses AI to arrive at a diagnosis without developing clinical reasoning isn’t a better doctor. Similarly, an architect who uses AI to generate a hundred options in a few hours without the taste to evaluate them isn’t a better architect. These are simply people holding and presenting outputs they can’t interrogate, in fields whose depth they haven’t entered.
The seconds are now on offer to everyone, and that alone really is extraordinary.
But what hasn’t changed is what those 34 years actually add up to. Or what quietly slips away when an entire generation decides the seconds are good enough and stops reaching for anything more.

Scale this up. What happens to one student, designer, or engineer compounds when it happens across whole cohorts, across industries, institutions, generations of people entering professions having produced outputs they were never required to fully understand. The individual cost of skipping the loop is a quieter kind of incompetence. The collective cost is something harder to name, slower to notice, and potentially irreversible.
The people closest to the technology have sensed it. The EY 2025 Work Reimagined Survey put it plainly: a significant portion of UK employees worry that AI is doing something to their capabilities they can't quite name; that "an overreliance on AI could erode their skills and expertise6.” These people aren’t outsiders looking in, nor are they critics with an agenda. Instead, these are people using the tools, seeing something happen to their own capabilities in a way that’s hard to articulate.
Now, the data, when it catches up, tends to confirm this experience. AI adoption at work has grown rapidly: 44% of UK employees now report using it at work7. But a closer inspection of the distribution is telling. Fewer than 5% are “using AI to fundamentally transform the way they work.8” The rest are producing faster, smoother, more polished versions of work whose underlying quality hasn’t moved, reiterating that access was never the ceiling. Judgement is; and that judgement is one thing the adoption statistics haven’t quite measured.
Navada Currie has spent a decade in design: across agencies, non-profits, freelance work, and nationally recognised campaigns in Australia, among them the World's Greatest Shave, which has raised over fifteen million dollars. She can see the difference:
“People who've taken the long road tend to bring a deeper level of understanding to their work. They're not starting from zero each time; they're drawing on years of practice, mistakes, references, and problem-solving. That depth becomes its own kind of shortcut."
According to her, the thing that shows up isn’t polish, but judgement. Shortcut-driven work can solve the more visible parts of a project brief, but it’ll struggle to survive the question of why:
"AI-generated branding can produce something decent-looking very quickly, but it often lands on the first obvious solution. A skilled designer will push beyond that — shaping something that connects to the brand's wider story."
Kateryna Sazanova, whose twelve years in film production and 2025 Emmy Award give her a particular vantage point on this, put it plainly:
“Now we see a flood of bad content. No matter what tools you use, it takes craft and mastery to produce a good story that will resonate, inspire, connect, give a new perspective, motivate for action and stay with the audience for a long time.”
Once you zoom out, the irony is kind of staggering. AI has made mediocrity effortless and excellence a lot harder to see. So when every student produces a polished essay, or a junior employee a competent presentation, or a designer a slick visual, the signal that once clearly separated deep capability from surface performance gets lost. And the noise rises. The people who actually made the hard journey become much harder to identify, and organisations can no longer tell the difference.
But most work requires a human touchpoint, be it a presentation, a defense, or a live critique; the gap reveals itself eventually. The tools didn’t create this dilemma. They’ve just made it far easier to avoid confronting, until the worst possible time.

Consider what the loop actually produces, beyond technical capability. It produces failure literacy: the ability to recognise when something is going wrong before it has fully gone wrong. It produces taste, which is just a fancy word for the accumulated weight of every bad decision made and eventually, corrected. Isn’t that the kind of confidence that doesn’t normally announce itself? Because it’s built on evidence rather than outputs? These things aren’t exactly transferable. Not exactly teachable in the conventional way. They accrue slowly through the loop, showing up in how a person moves through a problem and not simply by what a person produces. Hence why professional schools across disciplines don't just teach theory; medicine mandates clinical rotations, law builds moot courts, architecture runs studio critique, business runs live consulting cases. The form changes. The underlying principle doesn't.
Now put that person in a room with AI. They can generate a hundred options and immediately know which ones are worth pursuing. They can work from an AI draft and understand why something is almost right, but not quite... They can use the tool at speed and trust their own judgment about when the tool is failing them. The 34 years don't become irrelevant in that room. Rather, they become the only thing that matters. Again, this isn't a case against AI as a tool. It's a case for sequencing: for building enough to know what you're looking at before you ask a machine to generate more of it.
I want to be very careful. People who skip the loop aren't without ability. They can produce. Sure. What they struggle to do is evaluate, interrogate, and redirect— the work that happens after the output exists. And that is precisely the work that AI can’t do on their behalf, because that’s the work that requires a human to have a well-informed opinion about what excellence actually looks like.
In a world where the output has been democratized, judgment is the scarce resource.
It always was. It's just easier to see now.
Let’s return to that room with Scher: the executives, the napkin, the red arc over the t, the sketch that took a mere second, and the room that couldn’t see the 34 years standing behind it.
What they were looking at, without knowing it, was the product of a process so incredibly long and internal that it practically dissolved into invisibility: the failed pitches, the wrong directions, the arduous accumulation of knowing what doesn’t quite work and why—all of that compressed into a single, and quite frankly, unremarkable moment that only looked effortless because of everything it contained.
We live in a culture that has essentially built something that can replicate that moment: the sketch, draft, deck, diagnosis; generated, polished, delivered. Fast and clean and competent. And increasingly indistinguishable on the surface from the work of someone who’s spent years earning the right to produce something.
But surfaces are not the entire story. Frankly, when are they ever?
The question I want to leave you with isn’t whether to use the tools. Use them. The question is whether you’re building something underneath the tools’ usage; something that would survive if the tools disappeared tomorrow. Something that’s yours, assembled slowly through an iterative loop, through the long and often thankless distance between not knowing and knowing deeply.
That distance has a name. And I’d argue it’s worth every step.
[1] Paula Scher, Abstract: The Art of Design, Season 1, Episode 6, dir. Richard Press, Netflix, 2017.
[2] McGaghie, W.C., Issenberg, S.B., Cohen, E.R., Barsuk, J.H., & Wayne, D.B. (2011). Does simulation-based medical education with deliberate practice yield better results than traditional clinical education? A meta-analytic comparative review of the evidence. Academic Medicine, 86(6), 706–711. / Mastery learning framework: see also Bloom, B.S. (1968). Learning for mastery. Evaluation Comment, 1(2), 1–12.
[3] Maguire, E.A., Gadian, D.G., Johnsrude, I.S., Good, C.D., Ashburner, J., Frackowiak, R.S.J., & Frith, C.D. (2000). Navigation-related structural change in the hippocampi of taxi drivers. Proceedings of the National Academy of Sciences, 97(8), 4398–4403. https://www.pnas.org/doi/10.1073/pnas.070039597
[4] Lichand, G. et al., cited in: Stanford Human-Centred AI, AI Challenges Core Assumptions in Education, February 2026. https://hai.stanford.edu/news/ai-challenges-core-assumptions-in-education
[5] AI Index Steering Committee, Artificial Intelligence Index Report 2026, Stanford University, April 2026. https://www.starkinsider.com/2026/04/stanford-2026-ai-index-report.html
[6] EY 2025 Work Reimagined Survey, December 2025. https://www.ey.com/en_uk/newsroom/2025/12/uk-employers-miss-40-percentage-ai-gains-talent-gaps
[7] EY, "UK's AI Adoption Surges in Daily Life, but Lags Behind in the Workplace," EY AI Sentiment Index, 15 April 2025. https://www.ey.com/en_uk/newsroom/2025/04/ey-ai-sentiment-index-2025
[8] EY 2025 Work Reimagined Survey, December 2025. https://www.ey.com/en_uk/newsroom/2025/12/uk-employers-miss-40-percentage-ai-gains-talent-gaps